LMAO 😂
More posts
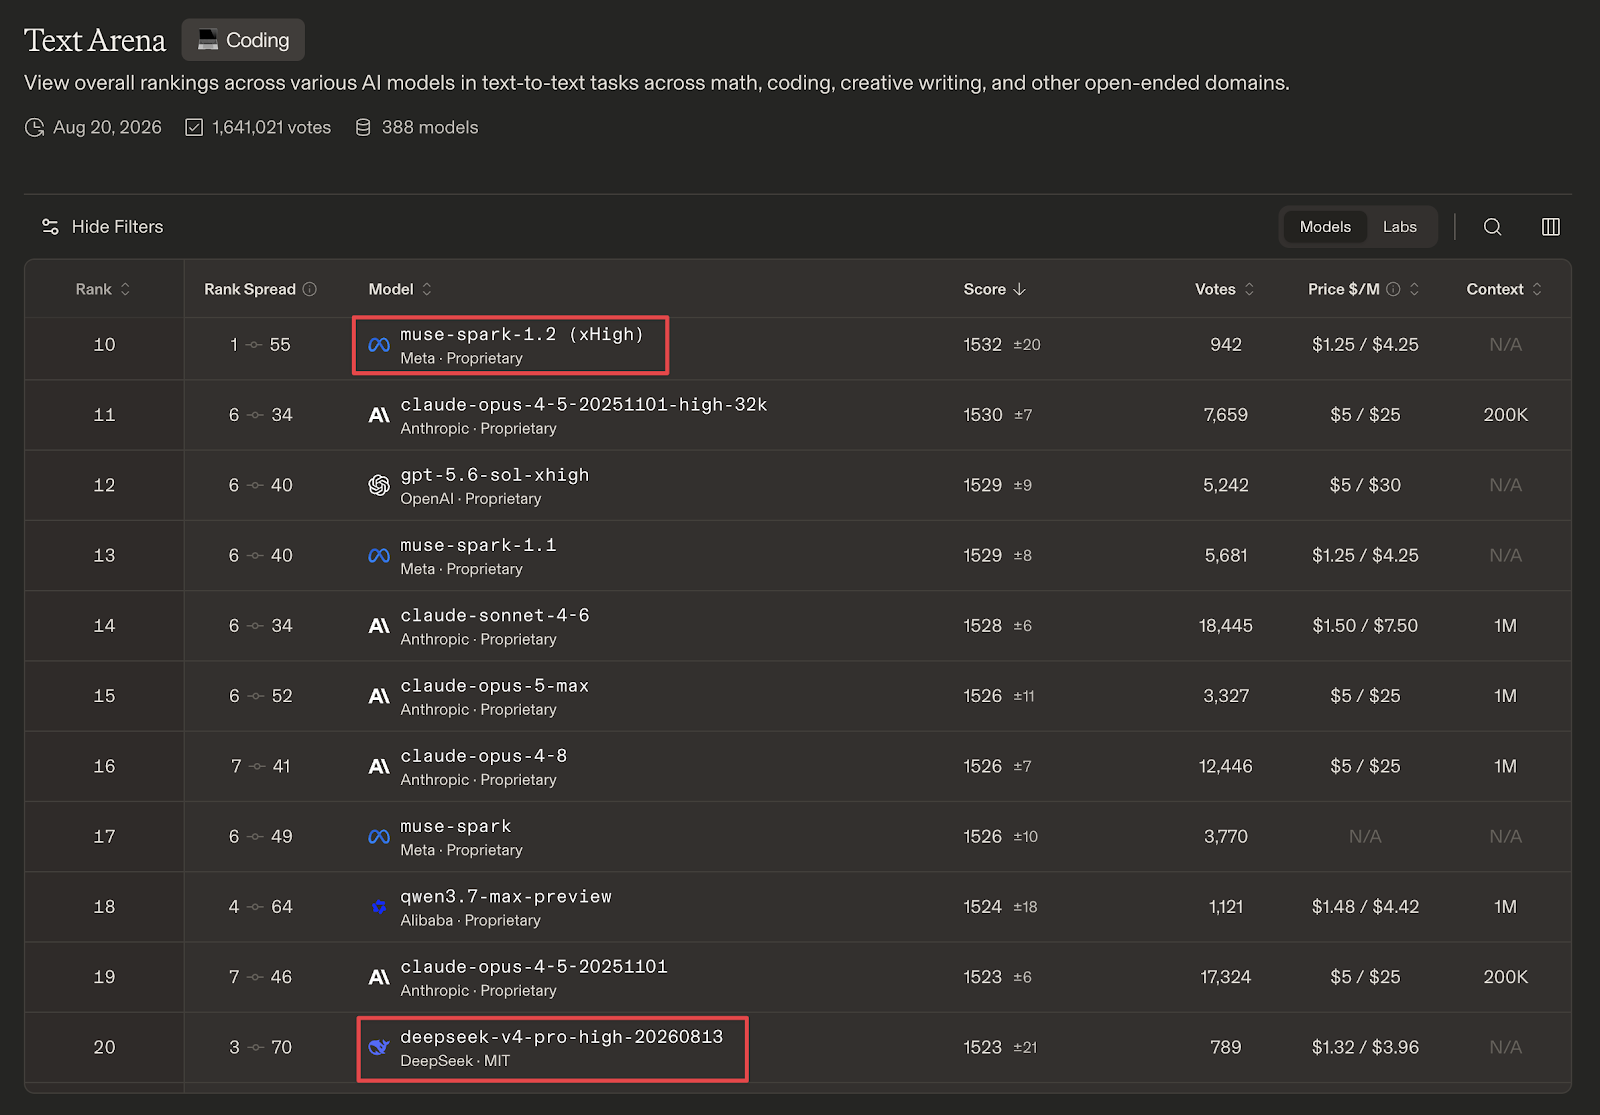
that changing anytime soon. On price and capability combined, nothing else I've tried comes close at this point. Meta trains on my data? Fine by me. Most of my projects are open source anyway. Quick comparison vs DeepSeek: - Muse Spark 1.2 (xhigh): intelligence index 57, multimodal - DS V4 Pro 0813 (max): intelligence index 53, text only Input: Muse $0.10 vs DS $0.66 off-peak / $1.32 peak Output: Muse $0.20 vs DS $1.98 / $3.96 Cache: Muse $0.002 vs DS $0.022 / $0.044 Same ballpark capability, roughly 6-10x cheaper depending on what you're running.
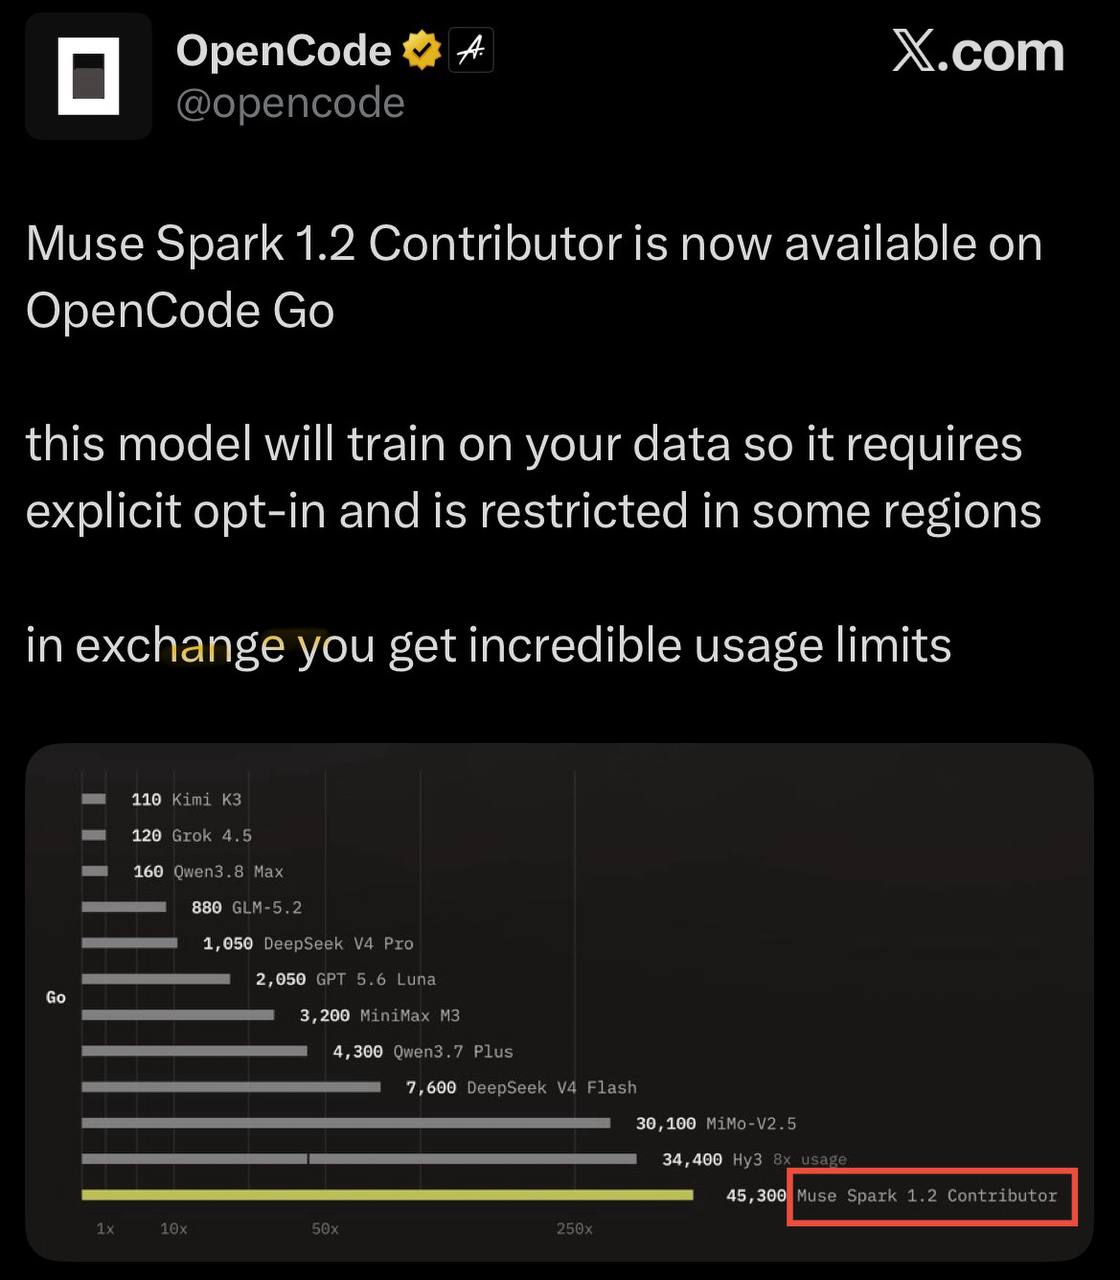
model with the biggest quota in the plan. One catch: your data gets sent to Meta for training. Company projects? Risky. I used it for a few days after DeepSeek's price hike. It gets the job done, but it's still a notch below the top tier.
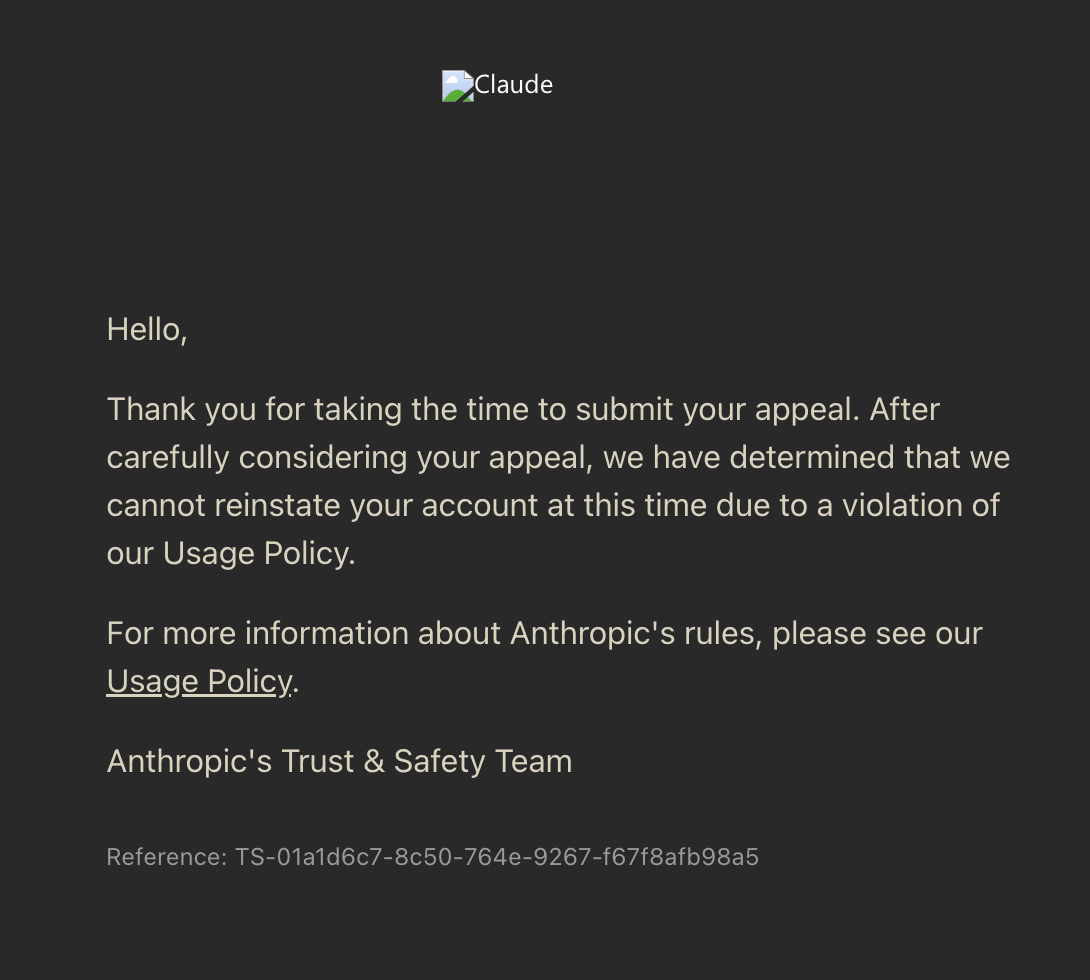
Won't refund the subscription either. I'm half convinced the appeal email is itself phishing, because I'm pretty sure they log the IP. DHH came to Shenzhen recently and showed how he uses Claude Code over there. That's the safest way now, honestly: run Claude Code on an overseas machine, connect through Tailscale, never use it locally. So I need to rent an overseas box with a residential IP, and register and log into Claude there.
Until late September it was the usual setup: parked in front of my laptop, terminal open, bossing pi around, fanning out subagents, then eyeballing diffs myself and filing the PR. Glued to the chair all day, every day. Late September I moved the whole thing to my phone, Hermes runs the show, pi takes the orders. My back is very grateful. Three weeks in, still no regrets. Stack: Hermes on flagship brains (gpt-6-astra / opus-5.5), pi on mid-tier (ds-v4.1-flash / sonnet / terra) with as few plugins as possible, the two talking over a2a. Hermes reads the issues, slices them into small tasks, spins up a worktree for each one, and dispatches a pi into it. When a pi finishes it pings Hermes, who decides: ship the PR or bounce it back for rework. I get back from a full day of being a tourist, or just wake up, and a dozen PRs are sitting there done. Pretty sweet. The catch is how black-box the whole thing is. My emotional arc has been a rerun of early vibe coding, except back then I at least read the diffs. Now even that goes to a flagship model. Boxes all the way down. If you don't have data anxiety, grok-bot and chatgpt-dot basically ship this out of the box, grok-cli and codex built in, native agent-to-agent comms. Downside: your code lives on their servers, everything's moderated, and one ban takes it all with it.