More posts
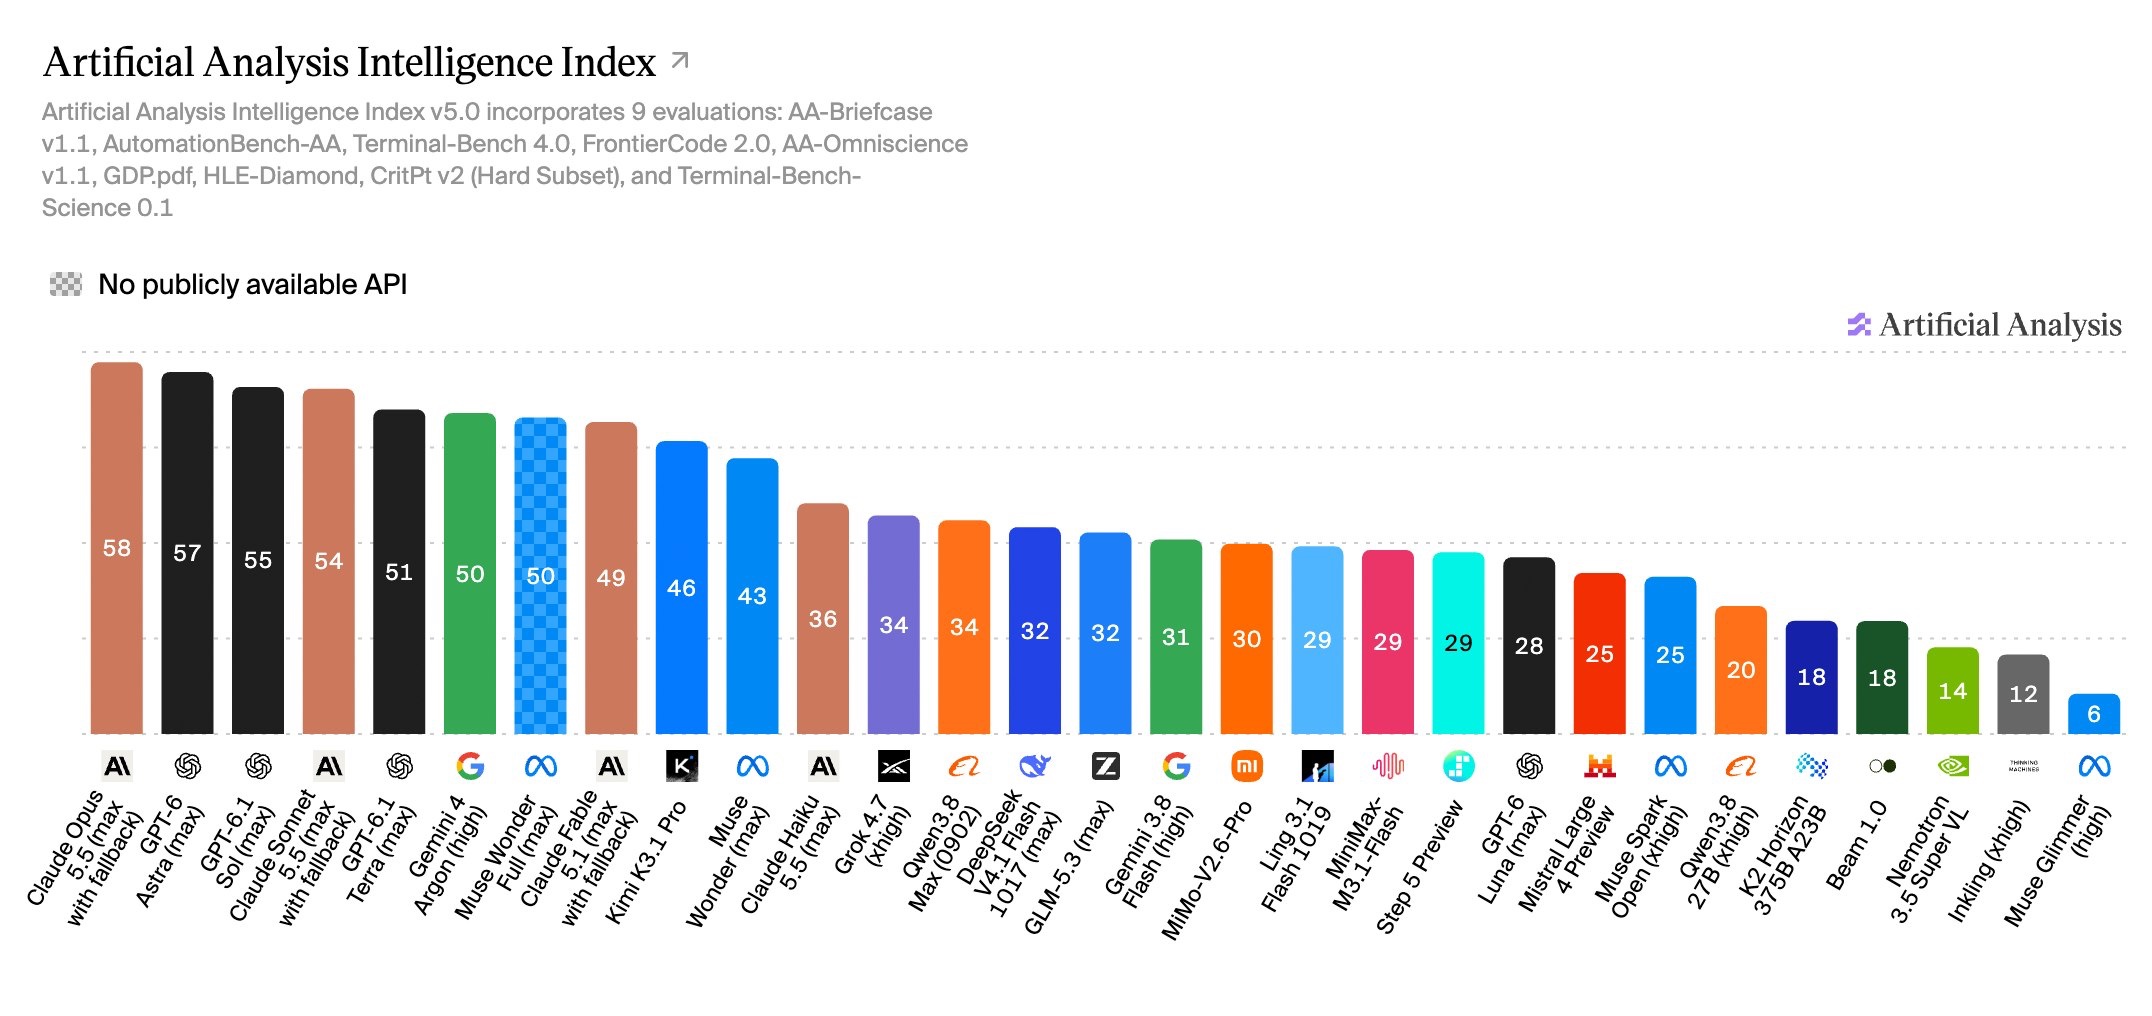
Biggest change: 60% of the weight now sits on private test sets and held-out answers. So the public benchmarks everyone spent two years tuning against don't measure much anymore. Claude Opus 5.5 (max) is first at 58. GPT-6 Astra 57, GPT-6.1 Sol 55. Close at the top, at least for now. Open vs closed went from a 3 point gap to 12. Kimi K3.1 Pro is the best open model at 46 and the weights aren't out. The best one with downloadable weights, DeepSeek V4.1 Flash, gets 32. That's under Claude Haiku 5.5. Open weights aren't one tier behind anymore. They're two.

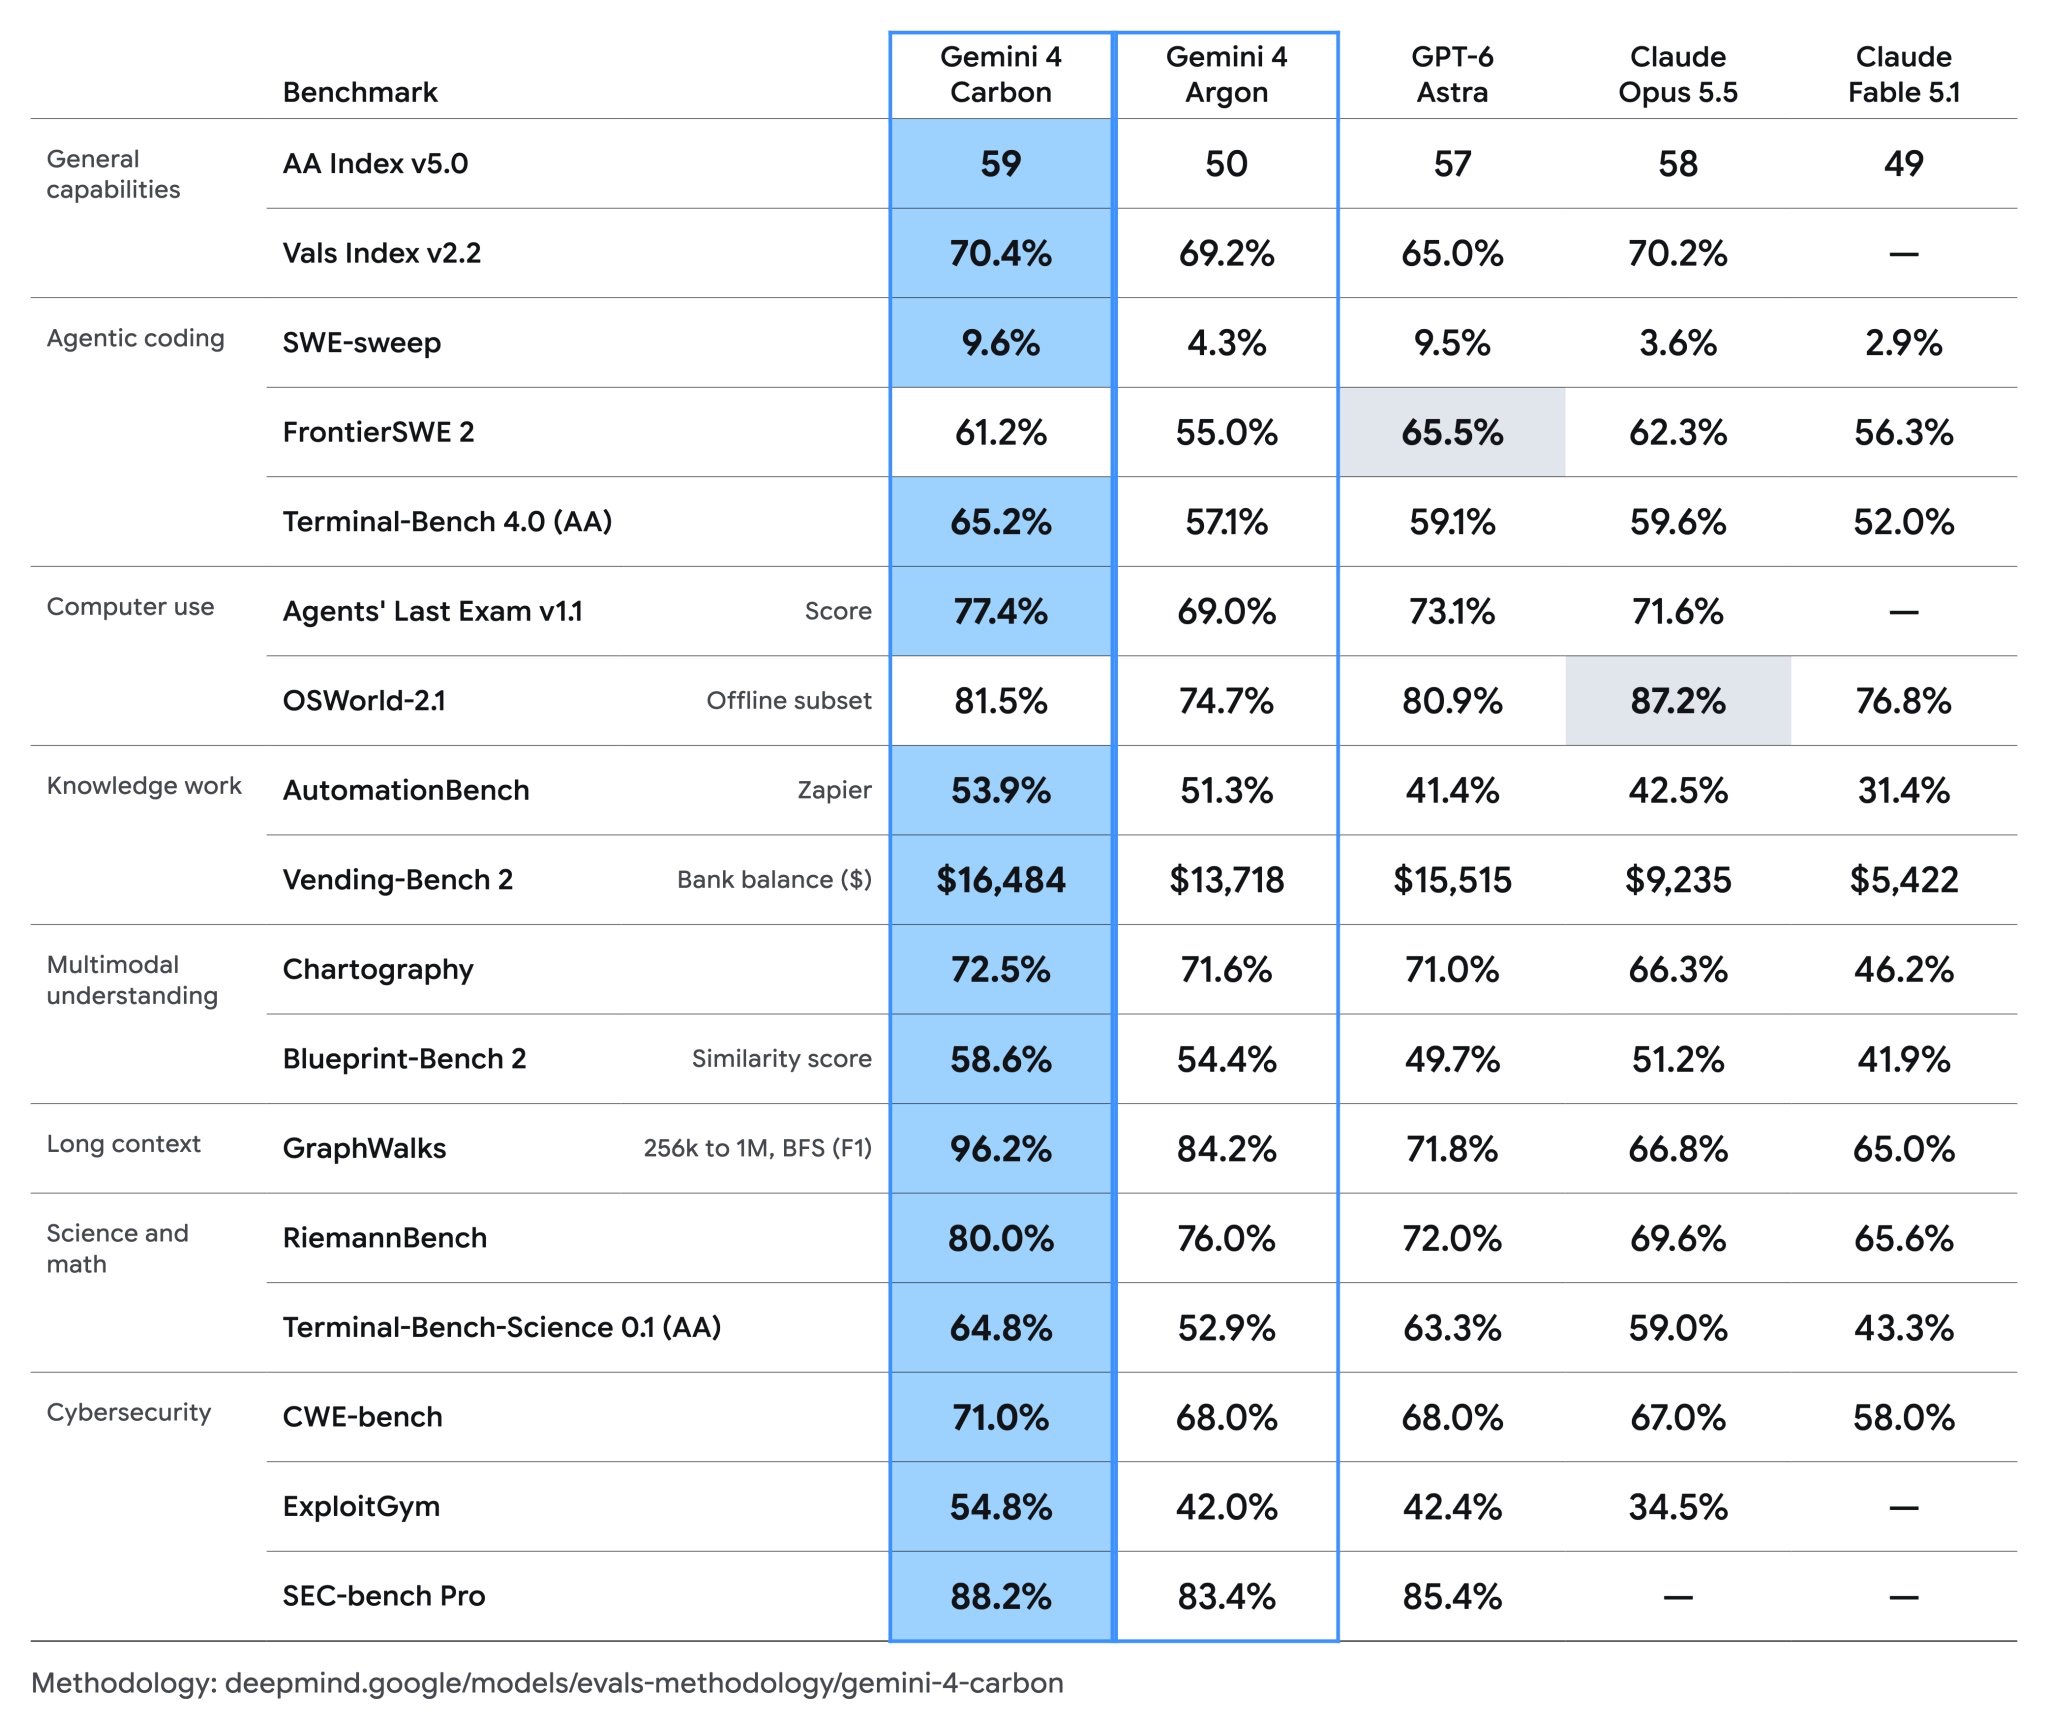
. Google announced Gemini 4 Carbon today. $2/M input, $10/M output. Same price Argon had two weeks ago, with cached input at half that. They haven't said anything yet about params, context window, or when the API opens. Right now it's in voluntary pre-release testing with the US government. Terminal-Bench 4.0 at 65.2%, eight points above Argon. GraphWalks long context at 96.2%. WebDev Arena up 89 points, fourth place.

Won't refund the subscription either. I'm half convinced the appeal email is itself phishing, because I'm pretty sure they log the IP. DHH came to Shenzhen recently and showed how he uses Claude Code over there. That's the safest way now, honestly: run Claude Code on an overseas machine, connect through Tailscale, never use it locally. So I need to rent an overseas box with a residential IP, and register and log into Claude there.

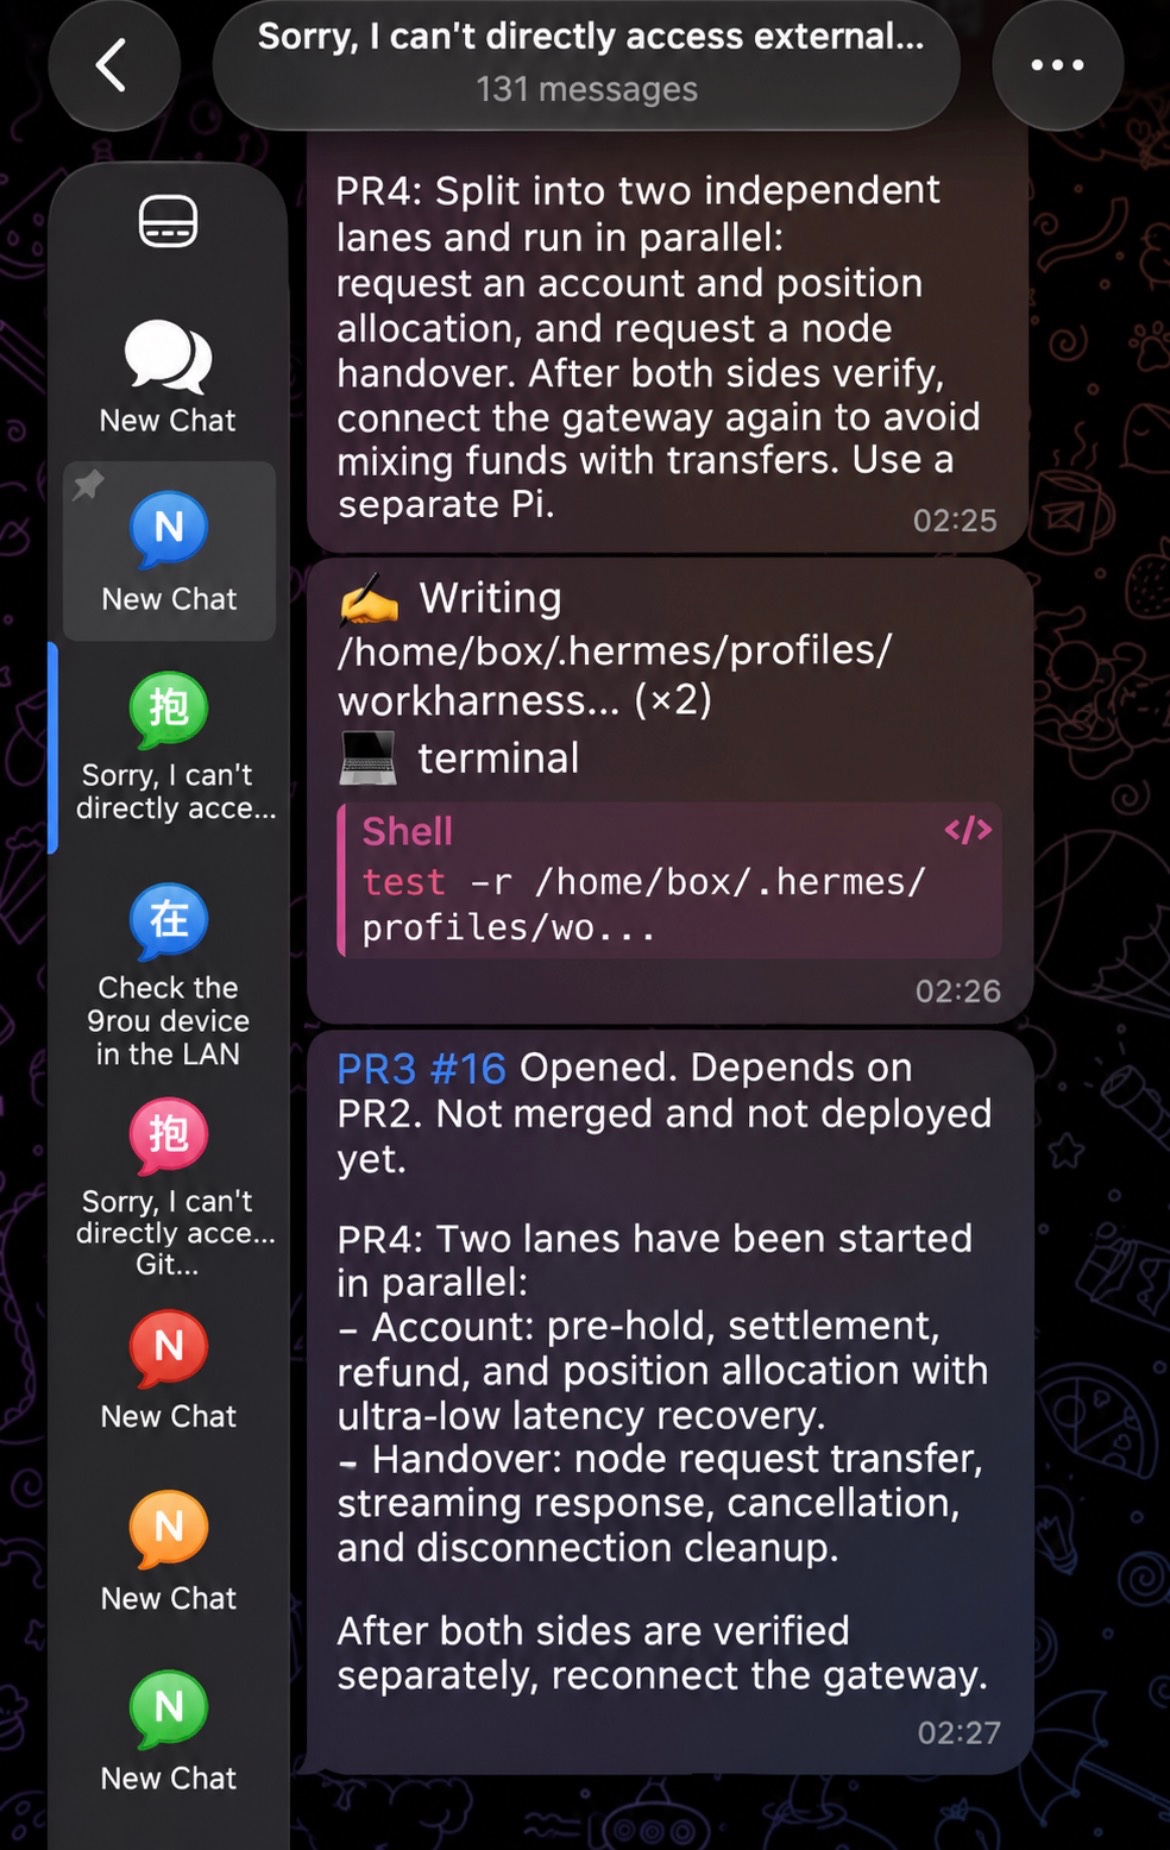
Until late September it was the usual setup: parked in front of my laptop, terminal open, bossing pi around, fanning out subagents, then eyeballing diffs myself and filing the PR. Glued to the chair all day, every day. Late September I moved the whole thing to my phone, Hermes runs the show, pi takes the orders. My back is very grateful. Three weeks in, still no regrets. Stack: Hermes on flagship brains (gpt-6-astra / opus-5.5), pi on mid-tier (ds-v4.1-flash / sonnet / terra) with as few plugins as possible, the two talking over a2a. Hermes reads the issues, slices them into small tasks, spins up a worktree for each one, and dispatches a pi into it. When a pi finishes it pings Hermes, who decides: ship the PR or bounce it back for rework. I get back from a full day of being a tourist, or just wake up, and a dozen PRs are sitting there done. Pretty sweet. The catch is how black-box the whole thing is. My emotional arc has been a rerun of early vibe coding, except back then I at least read the diffs. Now even that goes to a flagship model. Boxes all the way down. If you don't have data anxiety, grok-bot and chatgpt-dot basically ship this out of the box, grok-cli and codex built in, native agent-to-agent comms. Downside: your code lives on their servers, everything's moderated, and one ban takes it all with it.