Tencent's Hunyuan Hy3 is out. Best agent capability at its size.
295B total params, activates only 21B per inference. Simple queries answer fast. Complex ones tap deeper experts. 256K context, Apache 2.0 open source.
Pricing sits near DeepSeek V4 Flash: ¥1/M tokens in, ¥4/M out, ¥0.25 cache hit. OpenRouter has two weeks free.
Agent scores: BrowseComp 84.2, barely behind GPT-5.5 at 84.4. ClawEval 68.5, beating DeepSeek V4 Pro (62.4) and Qwen 3.7 Max (65.2).
Tested it alongside DeepSeek V4 Pro, K2.7, M3. Coding isn't the strongest, but agent ability is real, and the price is right. Solid pick as a general purpose agent model for openclaw, hermes, etc.
openrouter.ai/tencent/hy3:free
Tencent's Hunyuan Hy3 is out. Best agent capability at its size.
More posts
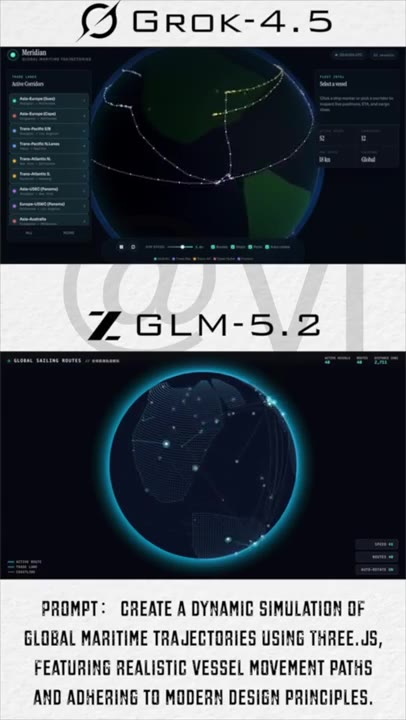
SpaceXAI dropped Grok 4.5 and it's actually good enough to pay
attention to now. Coding and engineering: hangs with GPT 5.5 and Claude Opus 4.8. SWE Bench Pro hit 64.7%, first time beating GPT 5.5 on this one. In practice I'd put it around GLM-5.2 level. $2/M input, $6/M output. Cheap relative to the rest of the frontier.
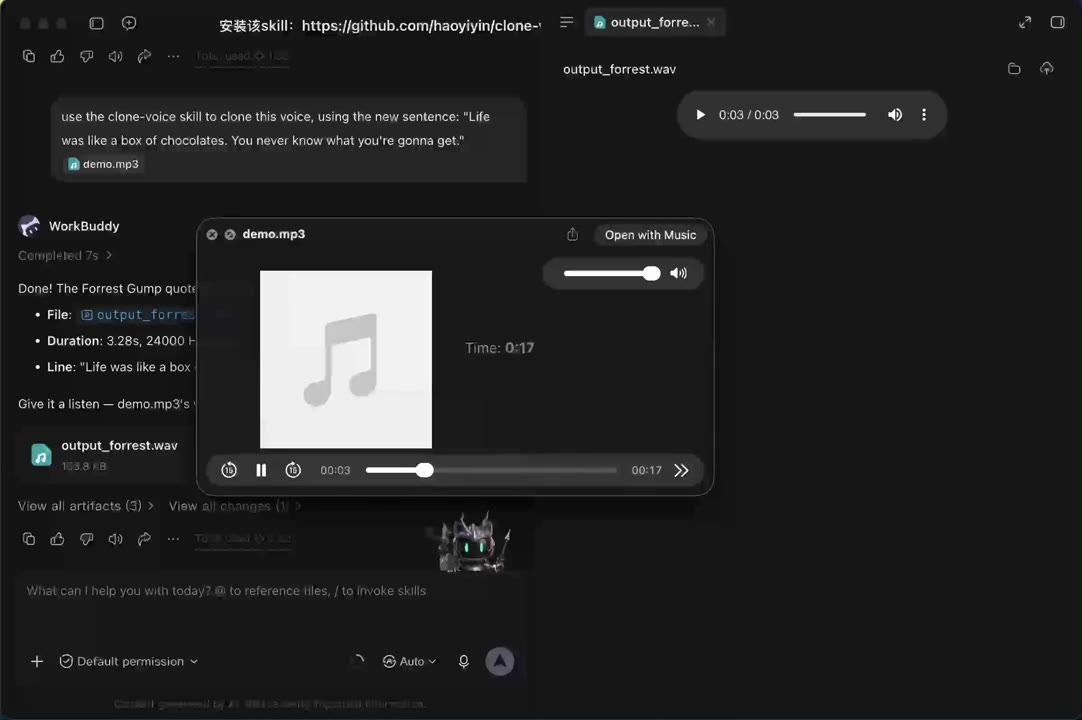
Grok + voice cloning. A fake account made me $3k.
I never use up my Grok Super video credits. They rot every month. So I started a thirst trap page. Grok handles the outfit videos. Same face, same body. Swap the clothes and setting. Voice is a cloning tool I built. Looks like one person, talks like one person. Did better than I expected. Few thousand followers in a week. 10k in under a month. Brand deal DMs followed. Easy to replicate. Voice cloning tool is open source. Grok Super or any video gen tool works. The rest is just execution. github: haoyiyin/clone-voice
Meituan shipped LongCat-2.5
. 1.6T params, ~48B active, native multimodal, aimed at long-horizon agents, trained start to finish on Chinese hardware. Images get quantized into multi-level discrete tokens, and that's where Visual Coding and 3D pick up. On the RL side, failed trajectories get turned back into verifiable training tasks. W4A4 inference, 43% faster prefill. Meituan's own evals put it between Claude Opus 4.8 and Opus 5.

SenseTime open-sourced SenseNova Loop-9B-Preview.
It stacks layers instead of parameters. The decoder has 32 layers, but layers 4 through 27 run twice with shared weights, so a forward pass does 56 layers of work while the checkpoint stays at 9B. Their own eval numbers: 71.38 on BIRD-Dev and 13.72 on AutomationBench, both above Qwen3.5-27B. Terminal Bench is still behind.
