OpenAI is shutting down Atlas, its AI browser, less than 9 months
More posts
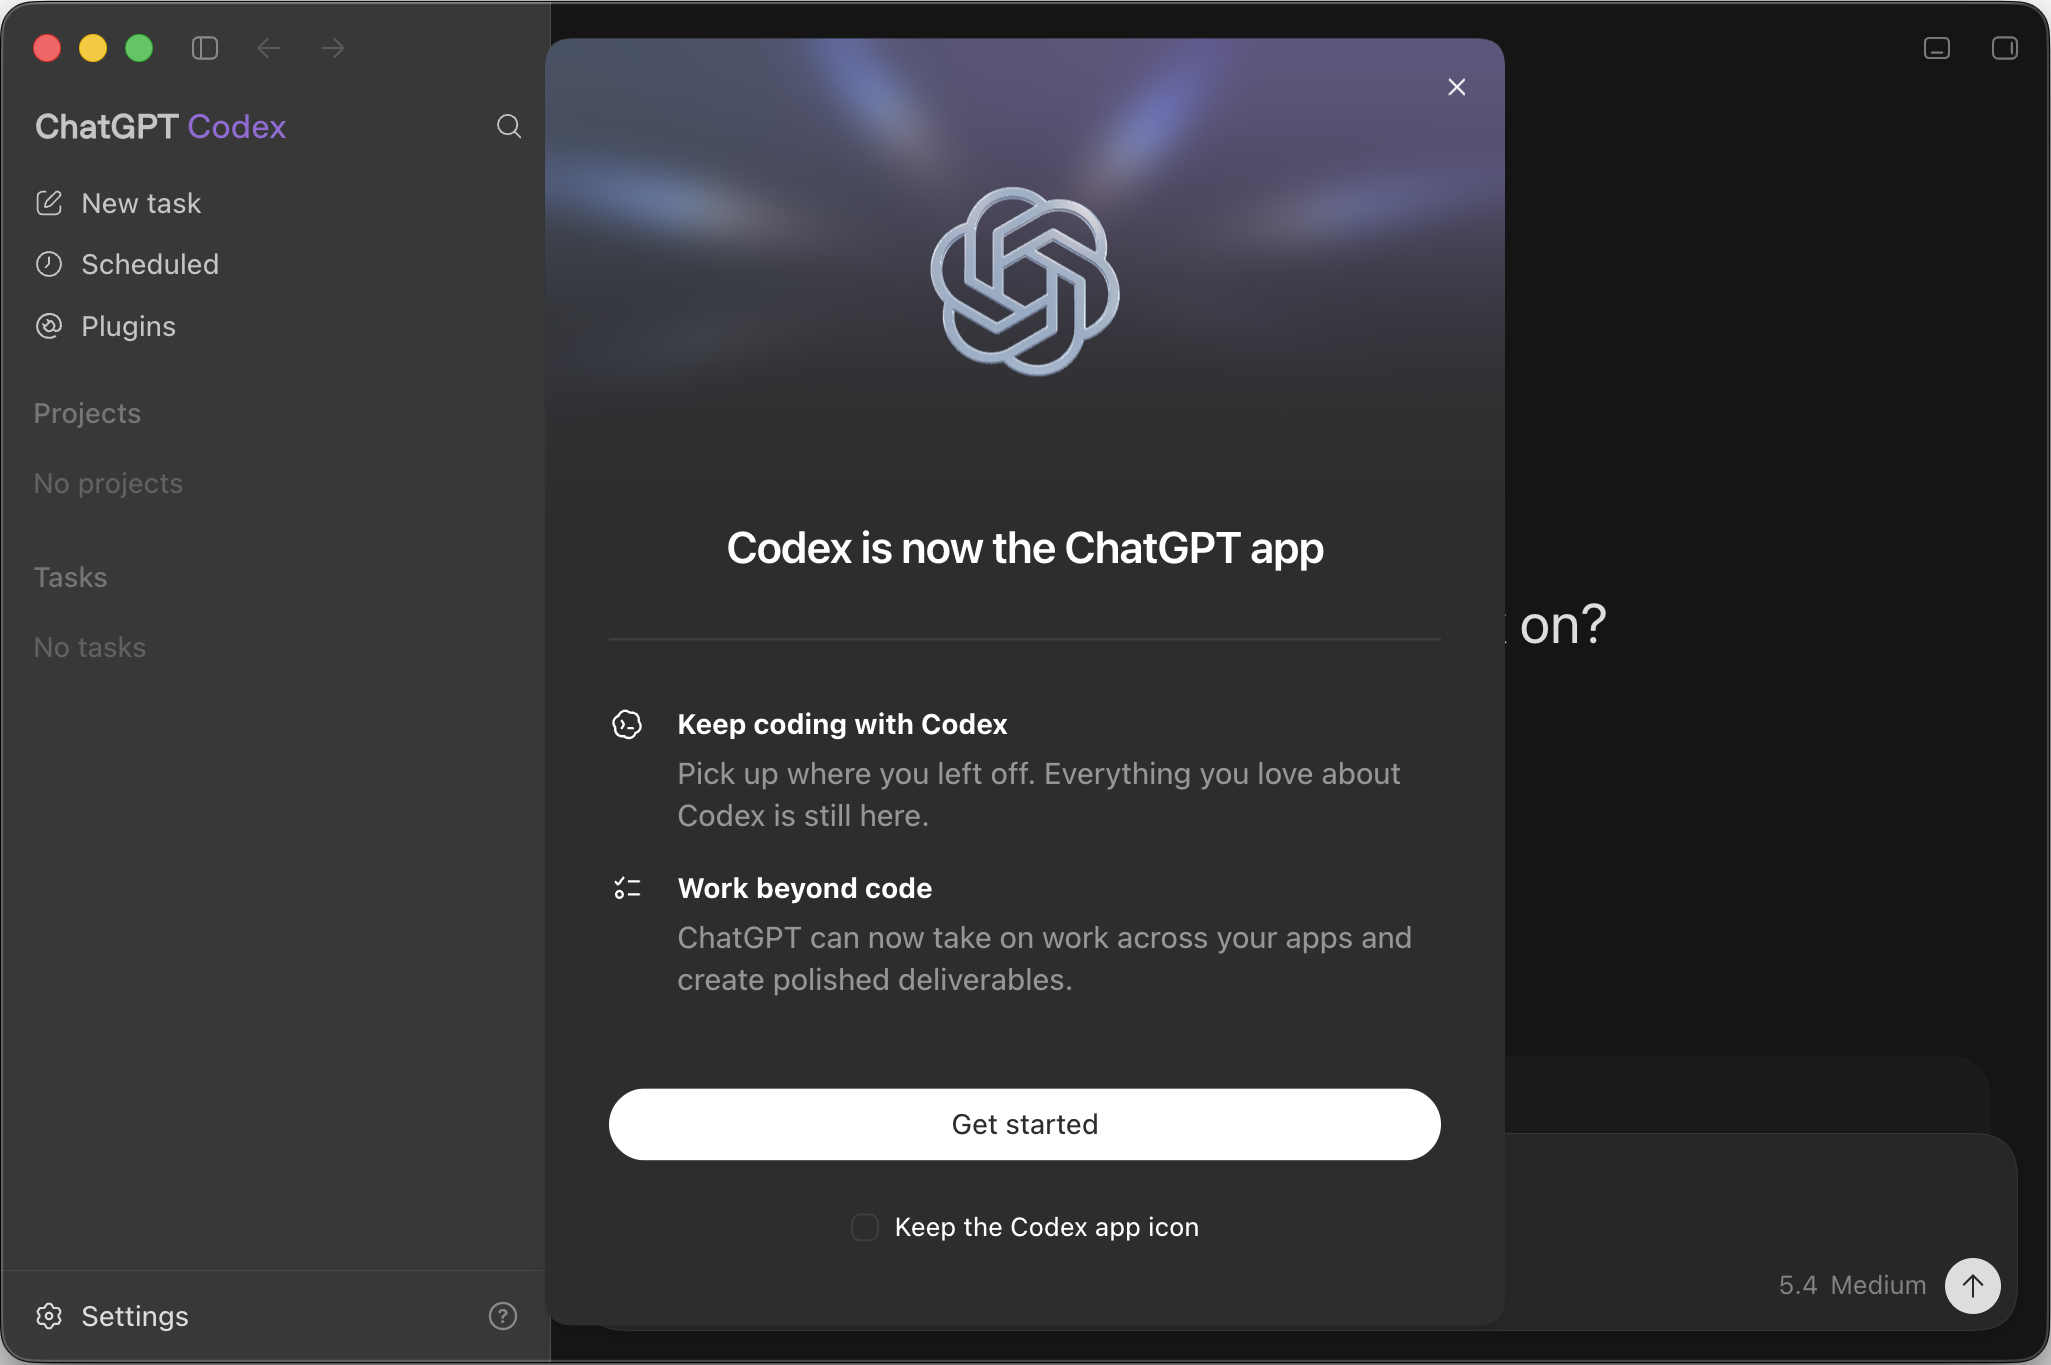
OpenAI dropped a ChatGPT Work app.
Turns out they finally realized calling it "Codex" made everyone assume it was for developers. ChatGPT Work is literally just Codex rebranded under the ChatGPT name. Same features, different label. The site is kind of a mess right now. You scroll through and see two apps both named "ChatGPT." New one is bigger (includes all the Codex stuff), old one is stripped down to just chat. Same icon, same name, two different downloads. Nobody bothered to distinguish them. 🔗 openai.com/index/chatgpt-for-your-most-ambitious-work

SpaceXAI dropped Grok 4.5 and it's actually good enough to pay
attention to now. Coding and engineering: hangs with GPT 5.5 and Claude Opus 4.8. SWE Bench Pro hit 64.7%, first time beating GPT 5.5 on this one. In practice I'd put it around GLM-5.2 level. $2/M input, $6/M output. Cheap relative to the rest of the frontier.
Meituan shipped LongCat-2.5
. 1.6T params, ~48B active, native multimodal, aimed at long-horizon agents, trained start to finish on Chinese hardware. Images get quantized into multi-level discrete tokens, and that's where Visual Coding and 3D pick up. On the RL side, failed trajectories get turned back into verifiable training tasks. W4A4 inference, 43% faster prefill. Meituan's own evals put it between Claude Opus 4.8 and Opus 5.

SenseTime open-sourced SenseNova Loop-9B-Preview.
It stacks layers instead of parameters. The decoder has 32 layers, but layers 4 through 27 run twice with shared weights, so a forward pass does 56 layers of work while the checkpoint stays at 9B. Their own eval numbers: 71.38 on BIRD-Dev and 13.72 on AutomationBench, both above Qwen3.5-27B. Terminal Bench is still behind.