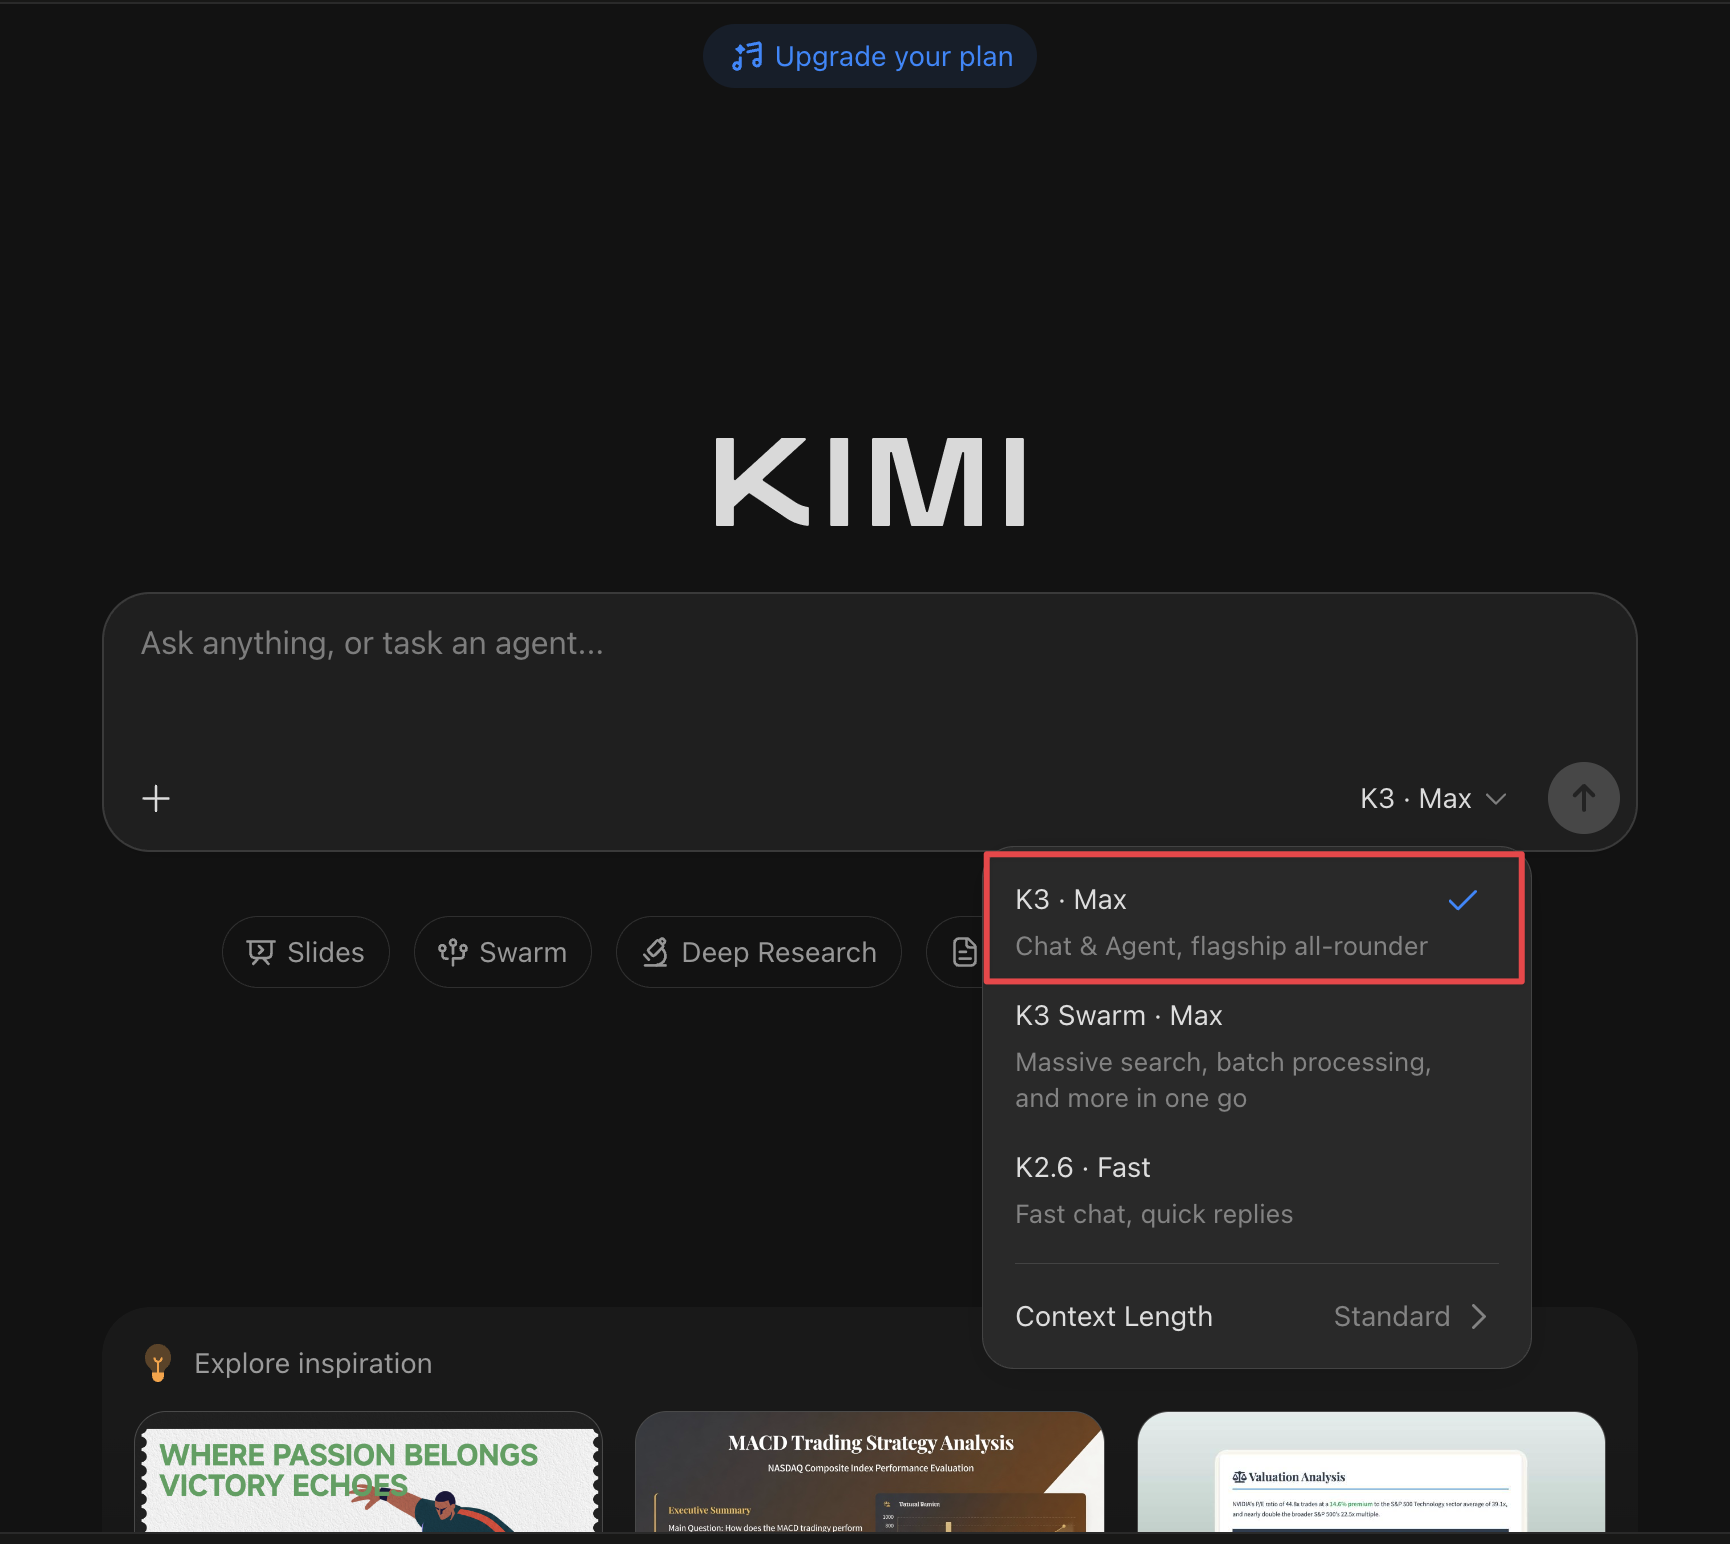
kimi web ( kimi.com ) just added the k3
More posts
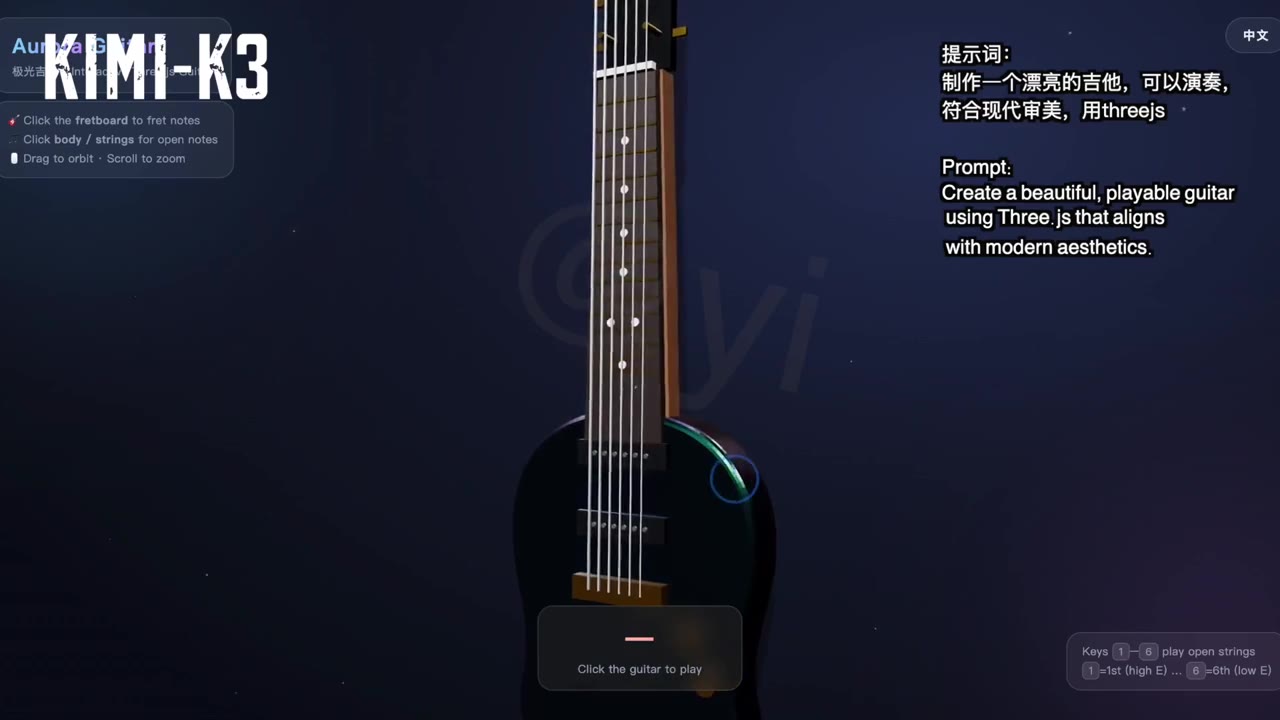
2.8T params, 896 MoE experts, only 16 active at a time. Native 1M context + multimodal. AA index 57, beats Opus 4.8 and GPT-5.5. #1 on Arena WebDev, 1527 on long agent tasks (2nd). Pricing is brutal. ¥2/M input (90%+ cache hit), ¥100/M output. Opensourcing before July 27. Strongest open model right now. I used K3 to generate a playable guitar. Final result stunned me. Cost me ¥5 in API calls but I hit errors the whole time. Honest take: too pricey right now, compute is tight.
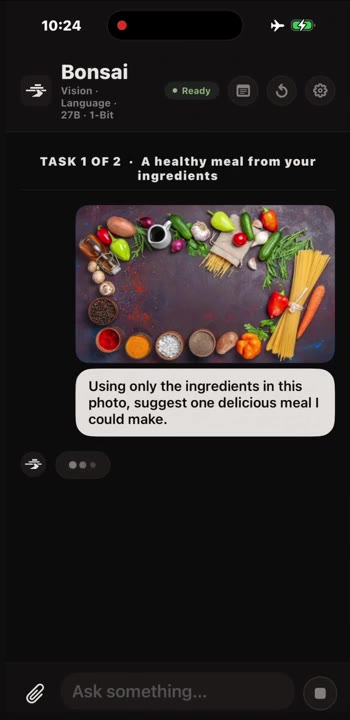
. First time anyone's done it. Bonsai 27B, built on Qwen3.6 27B with end-to-end ultra-low quantization. Ternary: 5.9GB, 80.49 avg. Keeps 95% of FP16. 1-bit: 3.9GB, 76.11 avg. Math hits 93.40 — 2 points off FP16. iPhone 17 Pro: 11 tok/s, 262K context. A 27B model running locally on a phone. Wild.
. 1.6T params, ~48B active, native multimodal, aimed at long-horizon agents, trained start to finish on Chinese hardware. Images get quantized into multi-level discrete tokens, and that's where Visual Coding and 3D pick up. On the RL side, failed trajectories get turned back into verifiable training tasks. W4A4 inference, 43% faster prefill. Meituan's own evals put it between Claude Opus 4.8 and Opus 5.

It stacks layers instead of parameters. The decoder has 32 layers, but layers 4 through 27 run twice with shared weights, so a forward pass does 56 layers of work while the checkpoint stays at 9B. Their own eval numbers: 71.38 on BIRD-Dev and 13.72 on AutomationBench, both above Qwen3.5-27B. Terminal Bench is still behind.
