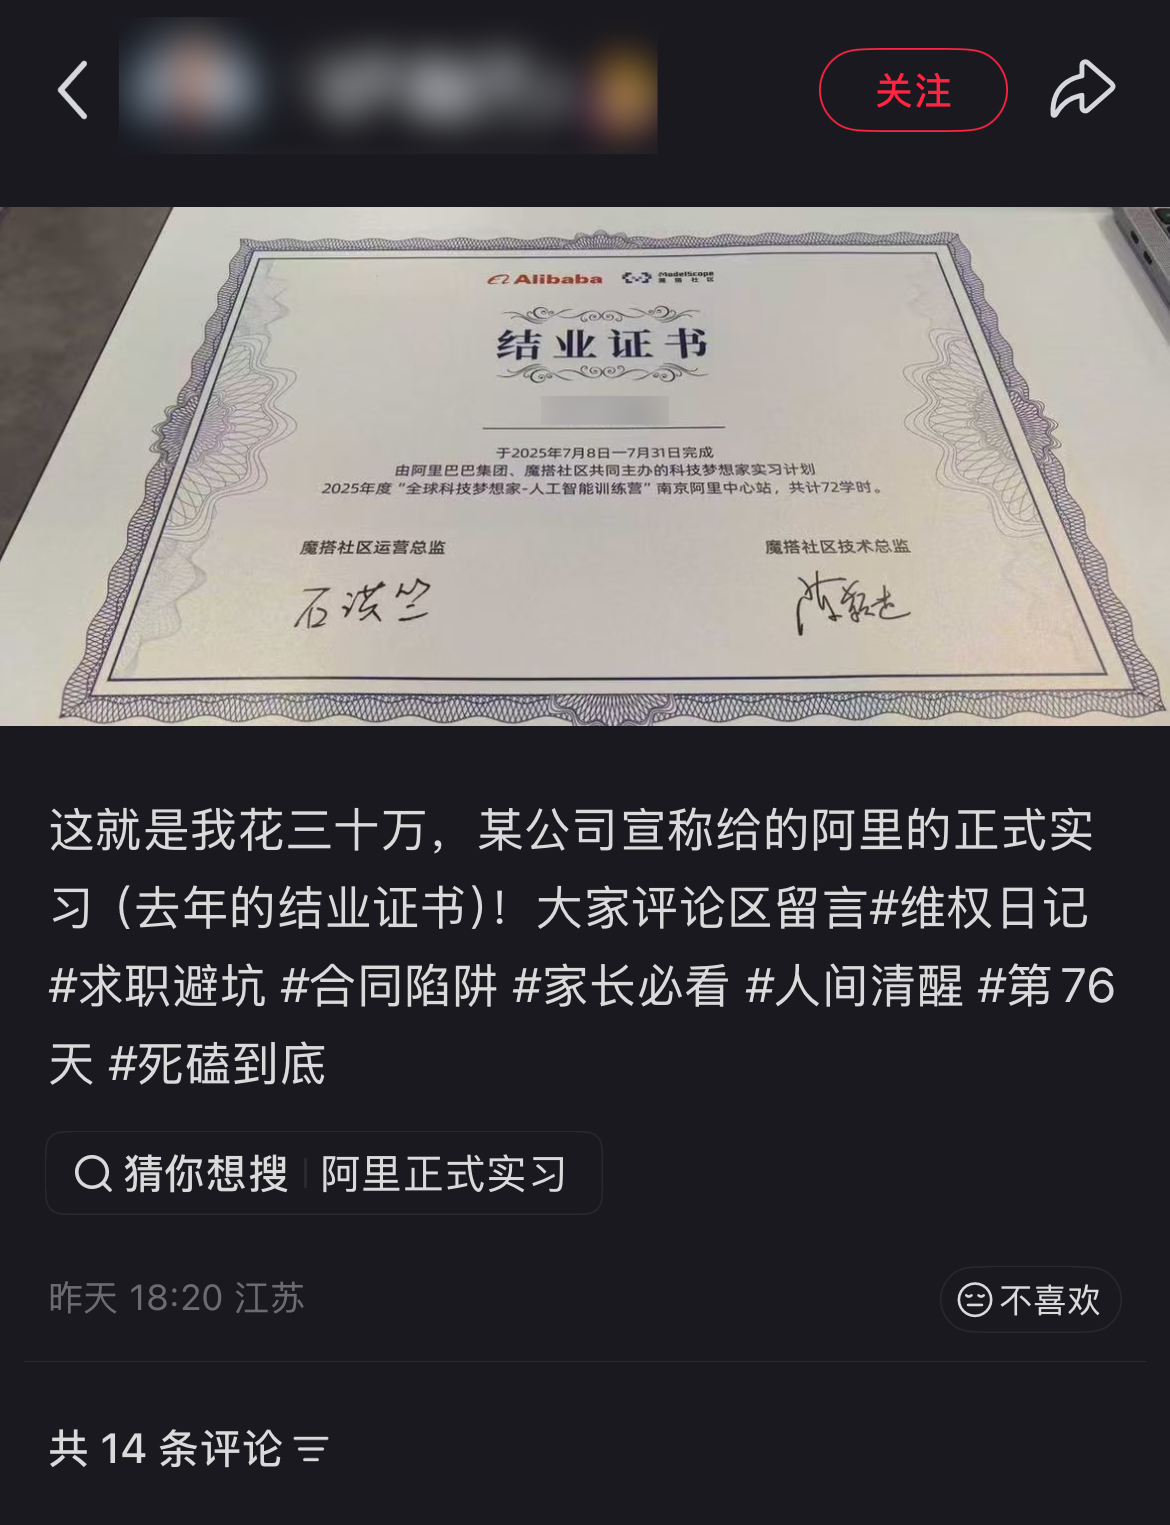
A parent in china dropped 300K rmb on an AI certificate
lmao a parent in china dropped 300K rmb on an AI certificate. it's a completely worthless piece of paper. scammers are eating good
More posts
most agent tools open a fresh browser or a separate profile. want to reuse your own? they copy your profile into the agent's, slow, and half the time your logins break. chrome 146 shipped CDP remote debugging (chrome://inspect/#remote-debugging). in theory, this lets an agent control your real window. i tested it. flaky on anything longer than a few minutes. weird bugs, no consistency. the move that works: a browser extension, like what manus does. install the playwright extension, connect it via playwright cli or mcp, and the agent drives your current window directly. same cookies, same logins, nothing new to launch. tested it through a long coding practice grind. didn't drop once.chromewebstore.google.com/detail/playwright-extension
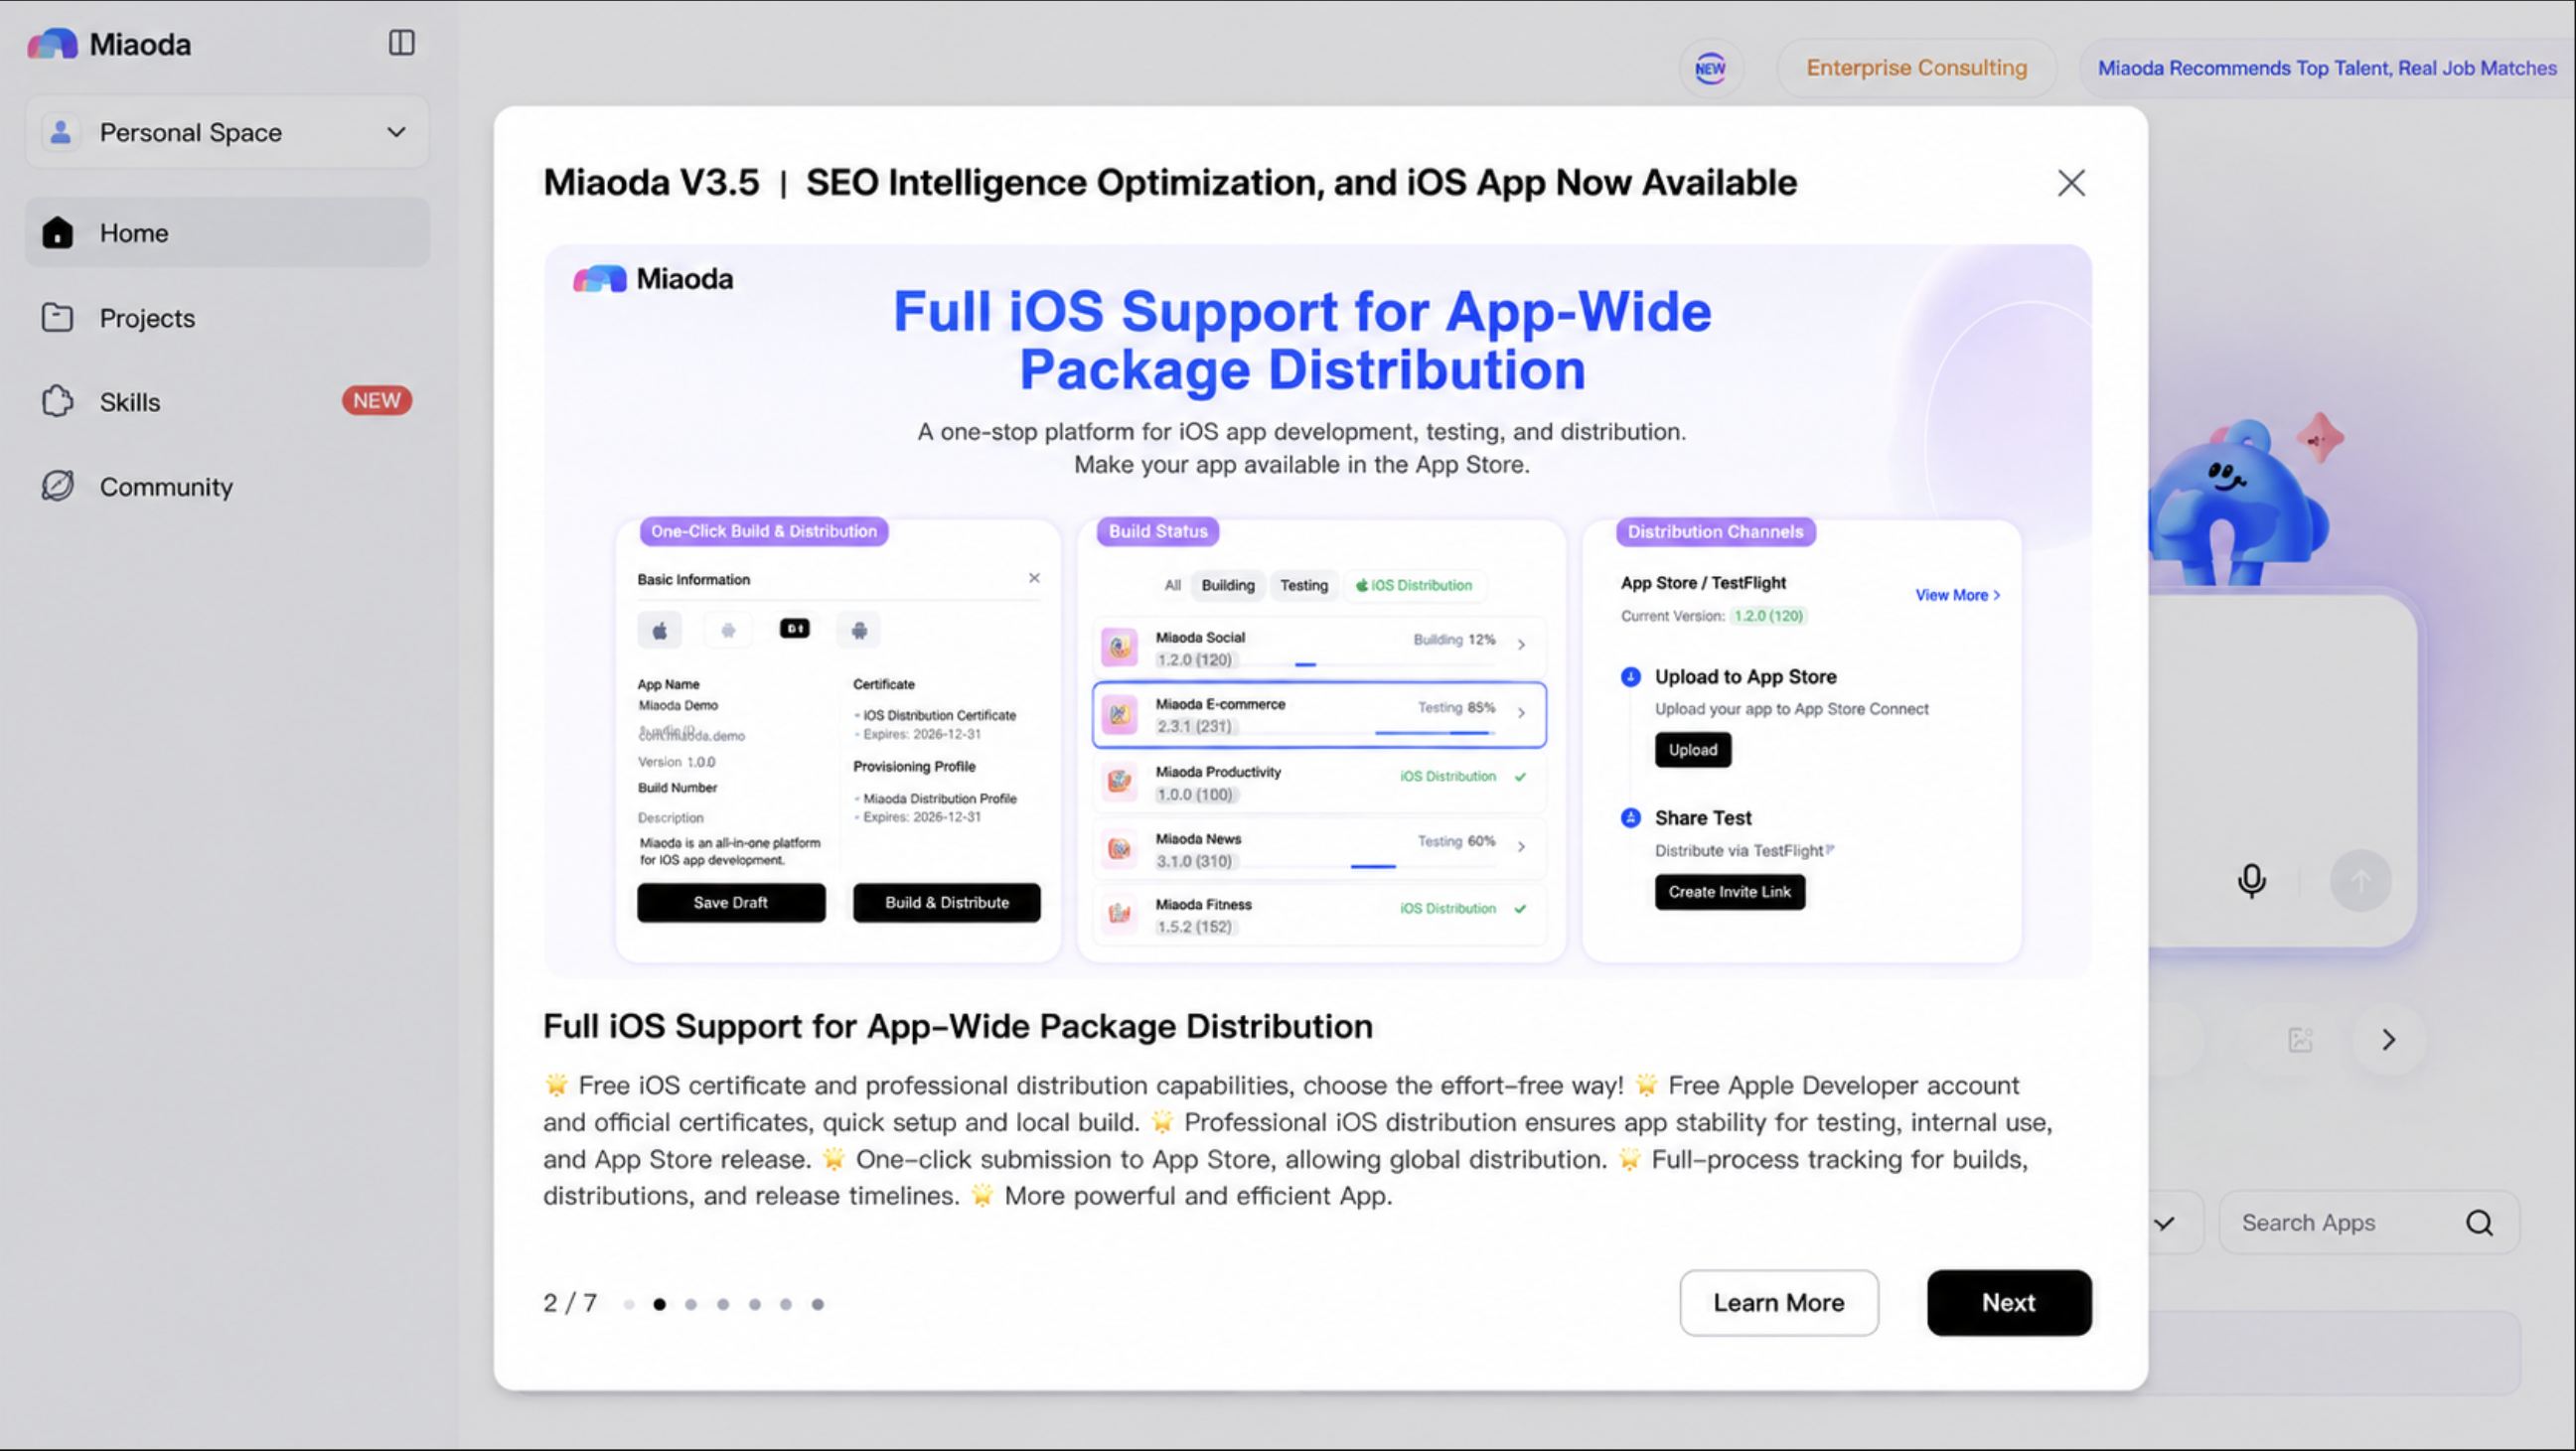
The old way: buy a Mac, learn Xcode, pay Apple $99/year, and drown in certs and provisioning profiles. Baidu Miaoda skips all of it. Describe your idea, it spits out a native iOS app, handles cloud builds, signs everything, and ships straight to App Store Connect. All automatic. No Xcode. No certs. No Mac required. First platform to go end-to-end: natural language → native iOS app → App Store. Nobody else does this.
. 1.6T params, ~48B active, native multimodal, aimed at long-horizon agents, trained start to finish on Chinese hardware. Images get quantized into multi-level discrete tokens, and that's where Visual Coding and 3D pick up. On the RL side, failed trajectories get turned back into verifiable training tasks. W4A4 inference, 43% faster prefill. Meituan's own evals put it between Claude Opus 4.8 and Opus 5.

It stacks layers instead of parameters. The decoder has 32 layers, but layers 4 through 27 run twice with shared weights, so a forward pass does 56 layers of work while the checkpoint stays at 9B. Their own eval numbers: 71.38 on BIRD-Dev and 13.72 on AutomationBench, both above Qwen3.5-27B. Terminal Bench is still behind.
