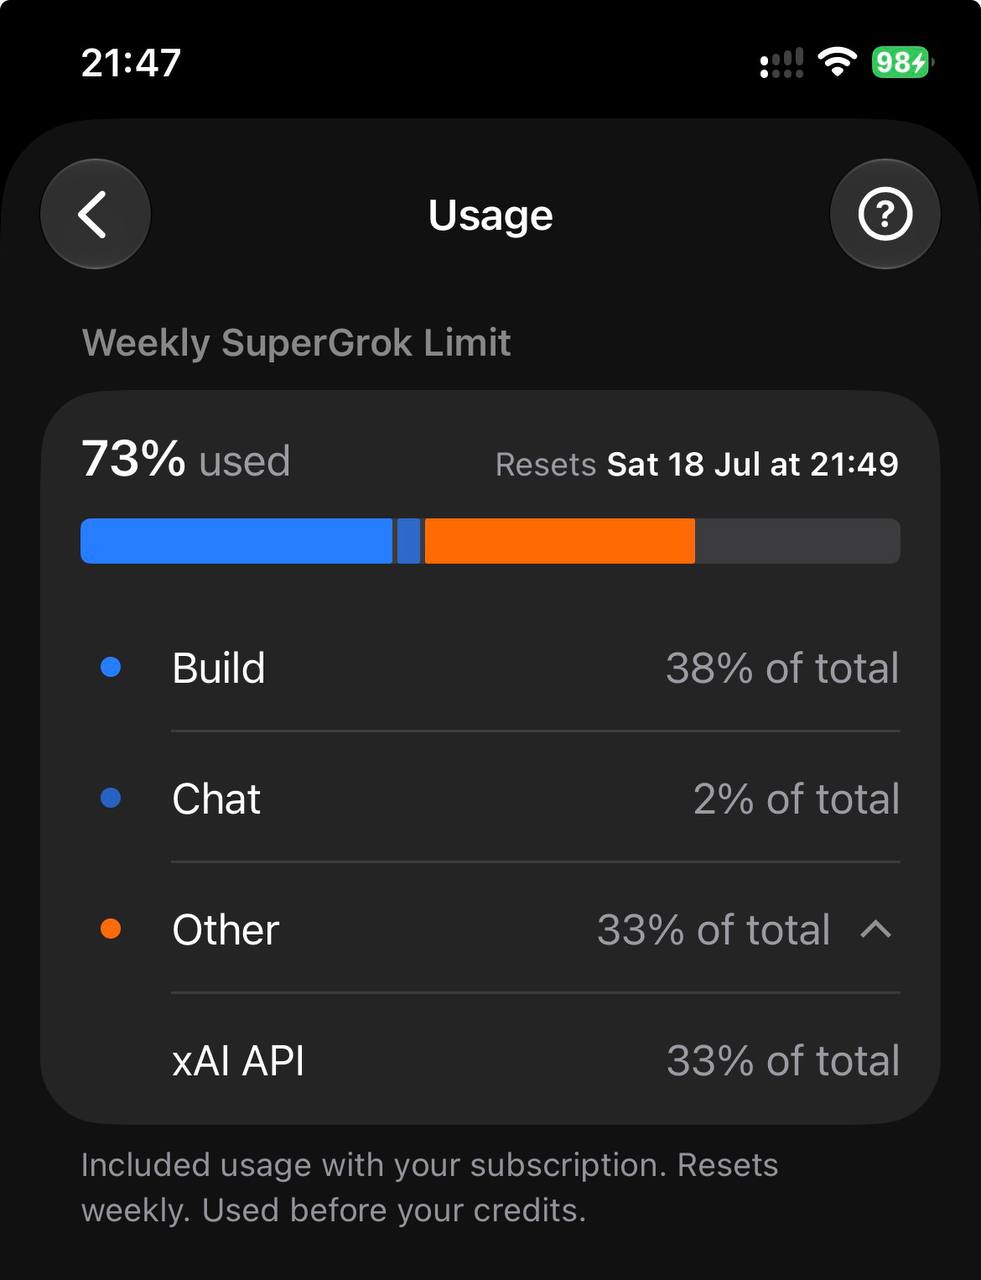
had leftover grok-4.5 quota go to waste
weekly reset hit, last night pi accidentally went through the xAI endpoint. burned 33% in 2 hours.
switched pi to grok build today. ran all day, only 38% gone. build billing rate feels way lower than xAI.
More posts
2.4T params. Open source. Biggest Qwen model they've shipped. Qwen3.8-Max-Preview is already live. You can use it on Token Plan, Qoder, and QoderWork. No benchmarks out there yet. I'll test it myself later and share what I find.
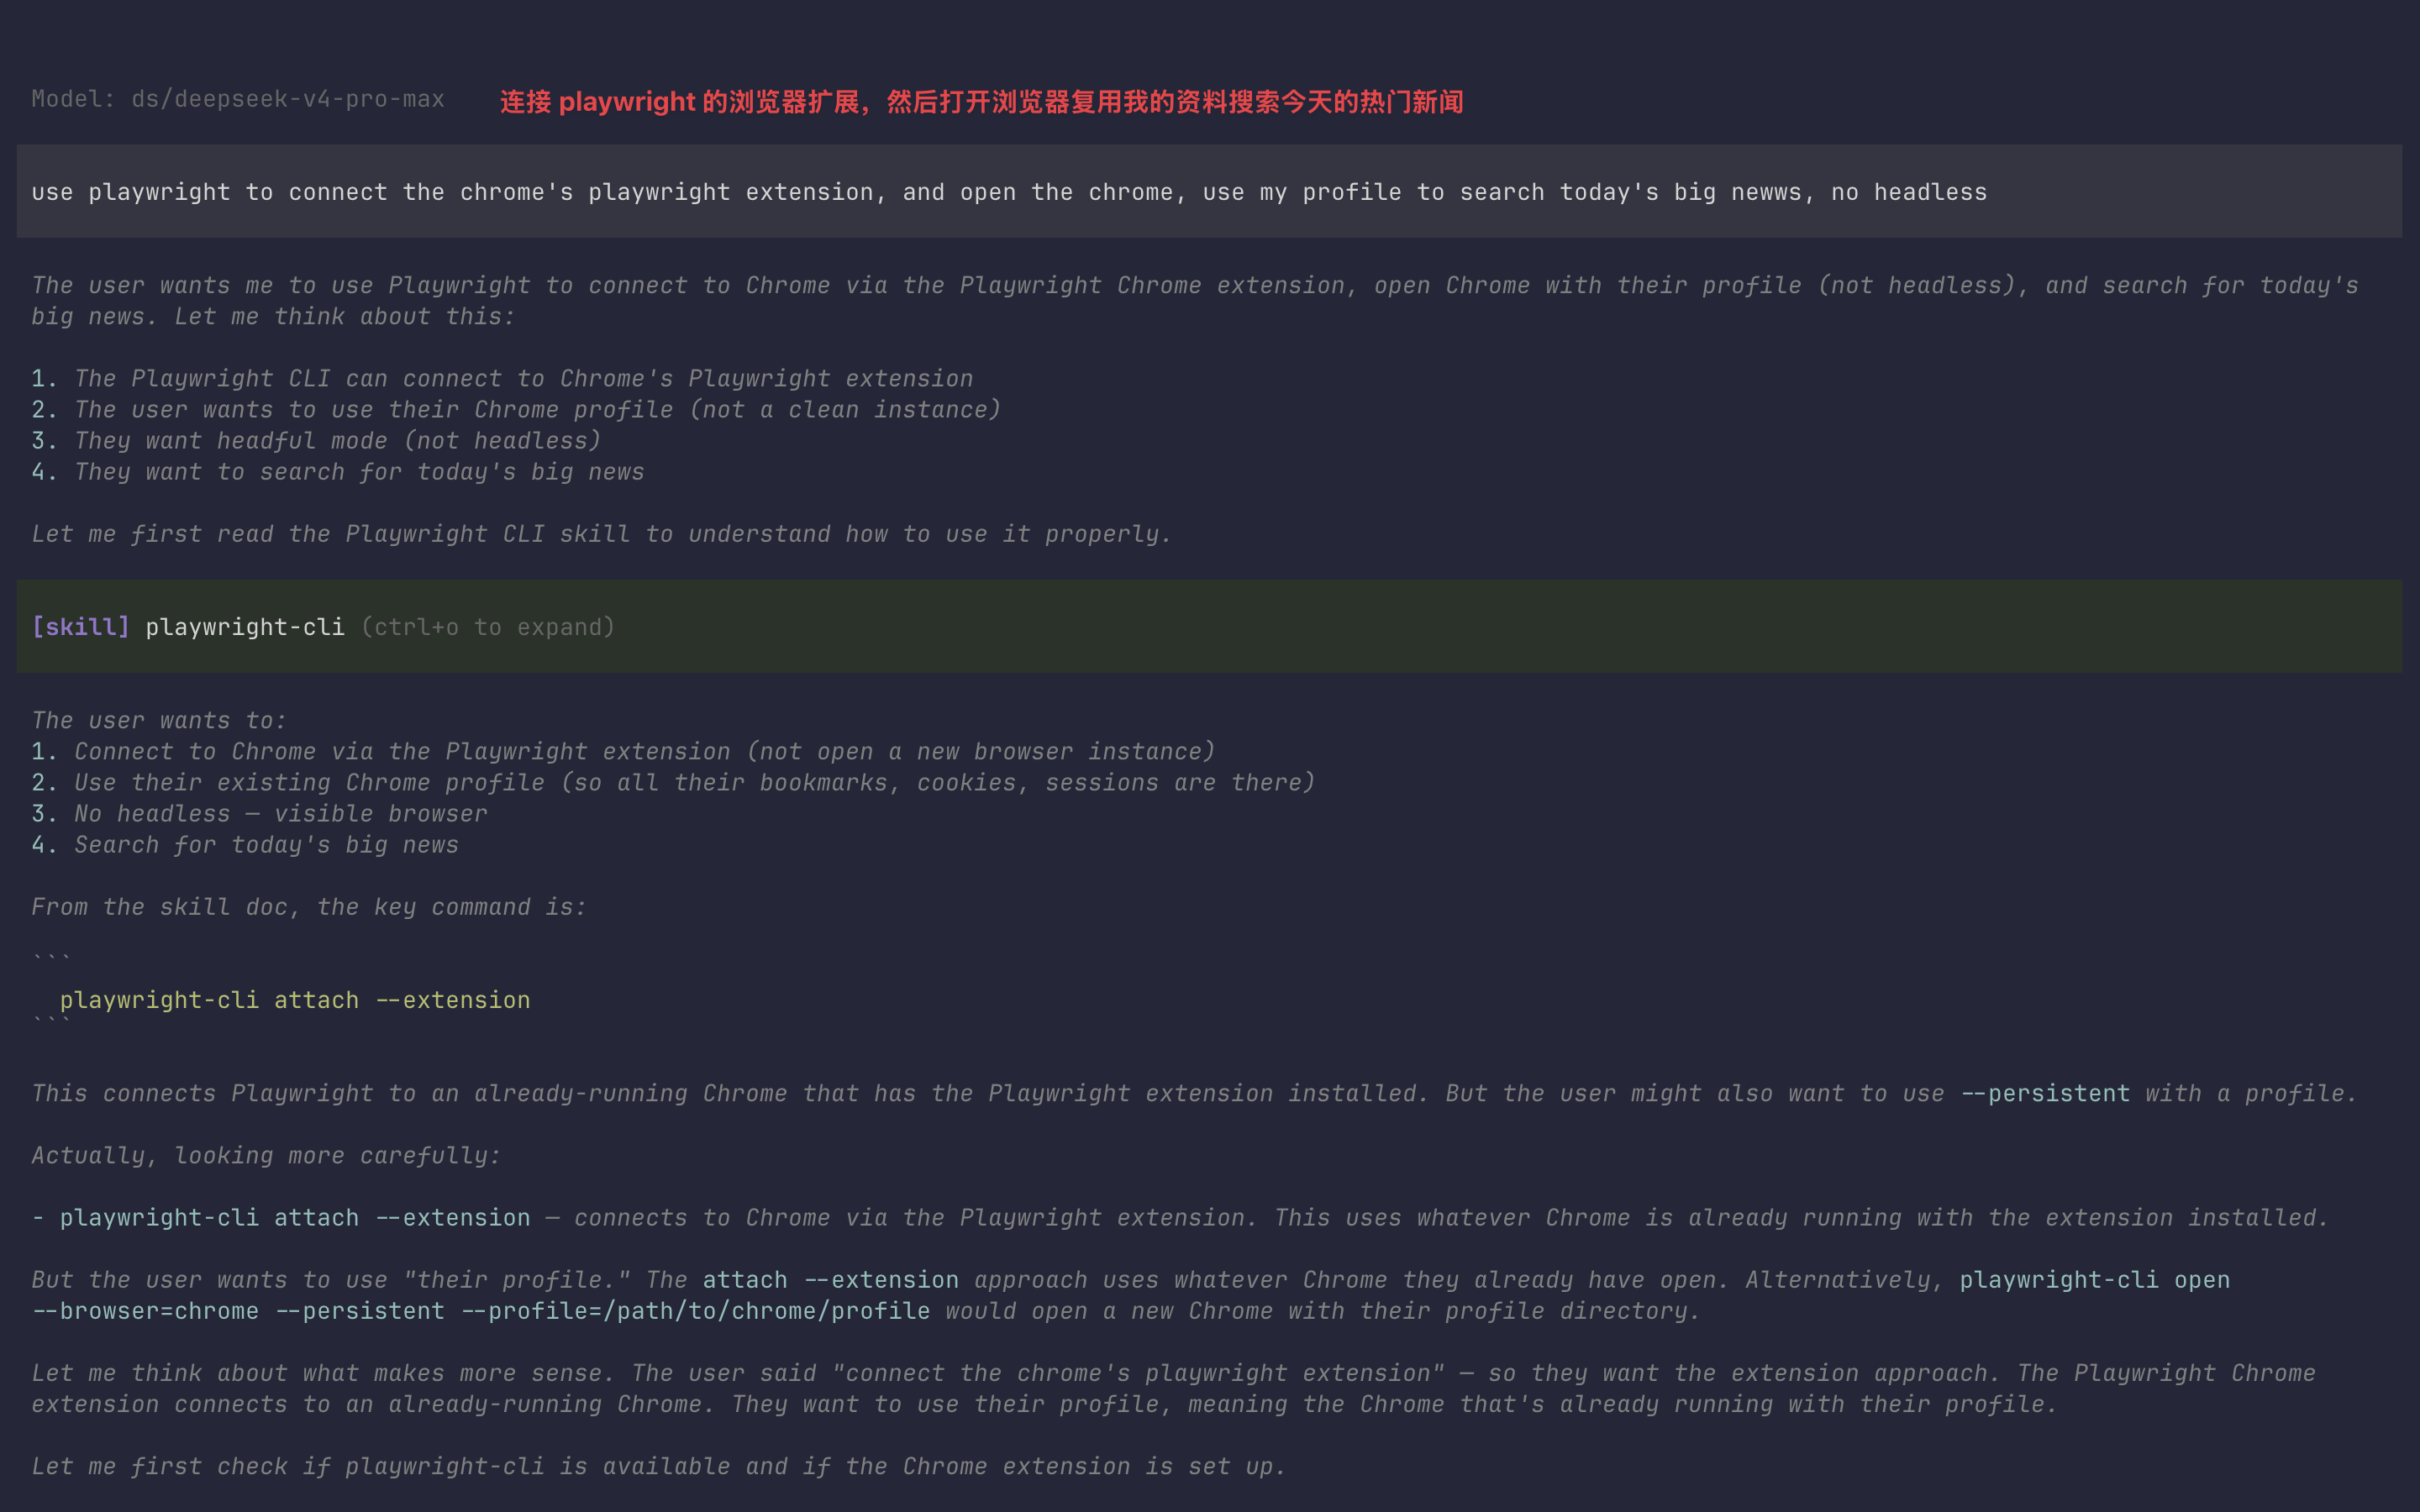
most agent tools open a fresh browser or a separate profile. want to reuse your own? they copy your profile into the agent's, slow, and half the time your logins break. chrome 146 shipped CDP remote debugging (chrome://inspect/#remote-debugging). in theory, this lets an agent control your real window. i tested it. flaky on anything longer than a few minutes. weird bugs, no consistency. the move that works: a browser extension, like what manus does. install the playwright extension, connect it via playwright cli or mcp, and the agent drives your current window directly. same cookies, same logins, nothing new to launch. tested it through a long coding practice grind. didn't drop once.chromewebstore.google.com/detail/playwright-extension
. 1.6T params, ~48B active, native multimodal, aimed at long-horizon agents, trained start to finish on Chinese hardware. Images get quantized into multi-level discrete tokens, and that's where Visual Coding and 3D pick up. On the RL side, failed trajectories get turned back into verifiable training tasks. W4A4 inference, 43% faster prefill. Meituan's own evals put it between Claude Opus 4.8 and Opus 5.

It stacks layers instead of parameters. The decoder has 32 layers, but layers 4 through 27 run twice with shared weights, so a forward pass does 56 layers of work while the checkpoint stays at 9B. Their own eval numbers: 71.38 on BIRD-Dev and 13.72 on AutomationBench, both above Qwen3.5-27B. Terminal Bench is still behind.
