Just found a legit 0-cost local solution for Agent search &
More posts
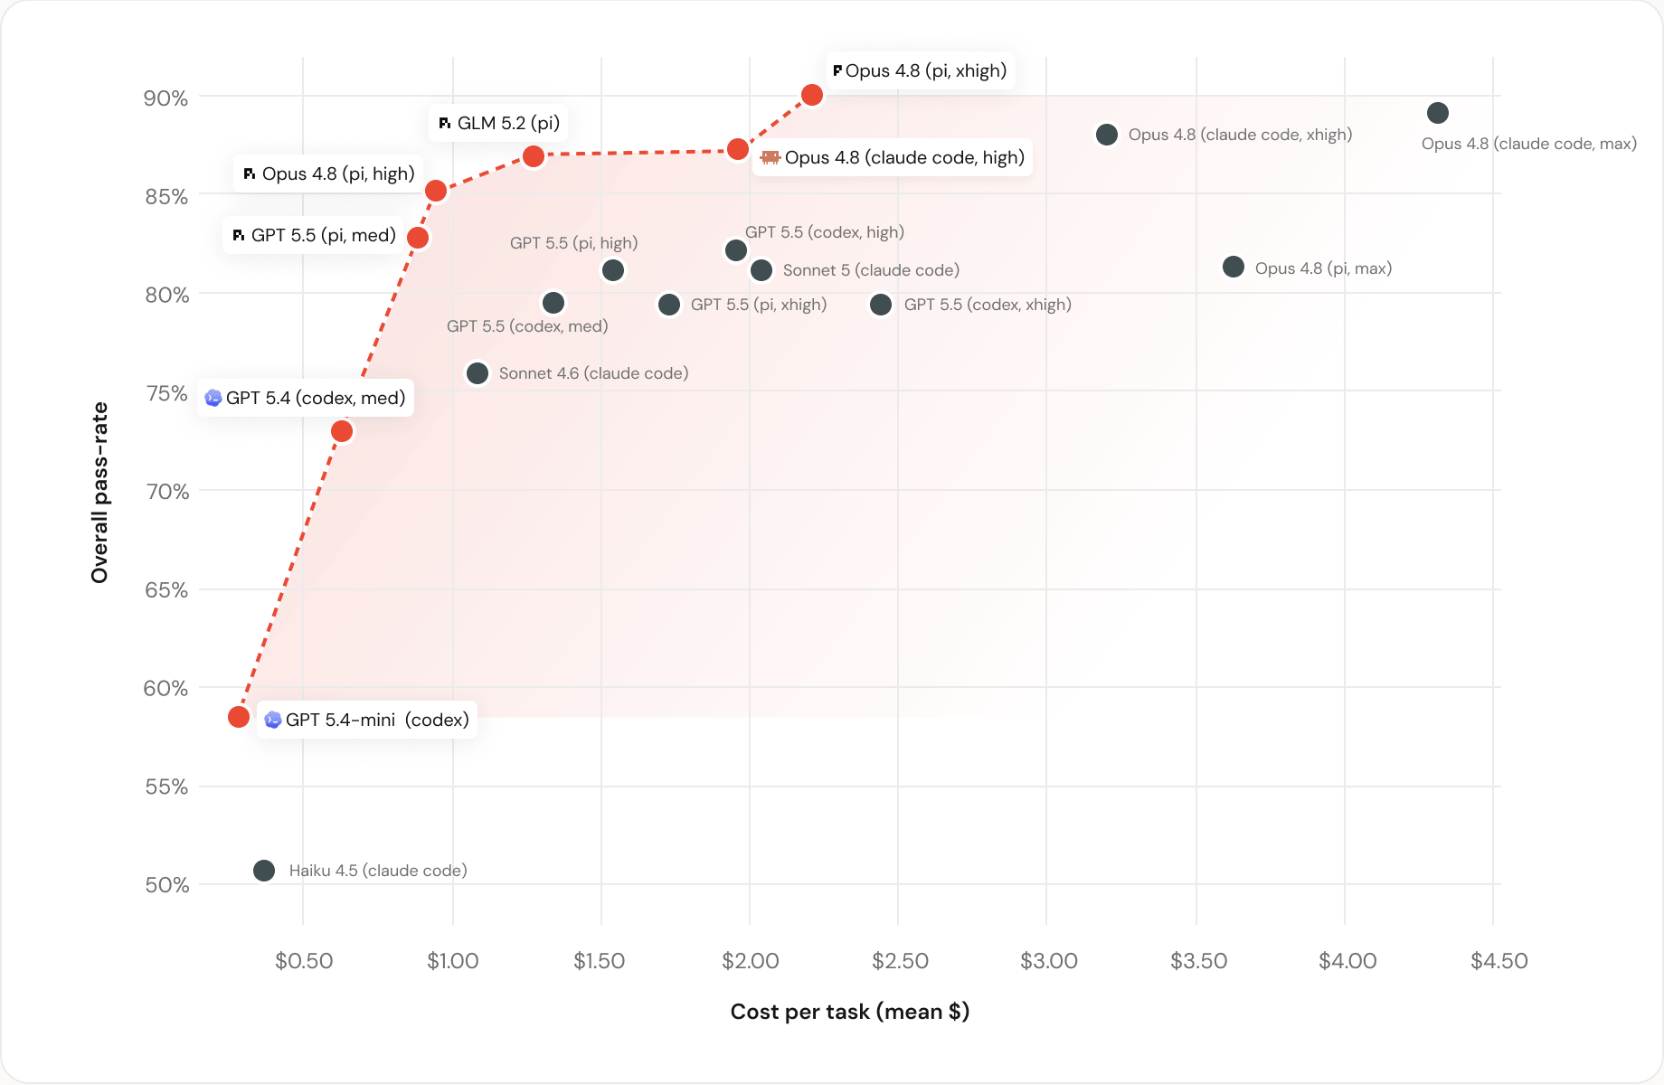
Databricks just ran a real-world coding test (not some benchmark
suite) pitting different agent tools against various models. Chart’s simple: higher on the Y = better success rate, further left on the X = cheaper. Pi with top models is sitting at 80%+ success while burning way fewer tokens than everything else. Been running Pi myself for a bit now — grok-4.5 + DeepSeek-v4 plus my own setup (main agent orchestrating, subagents running concurrent with isolated context). Barely any rework, stupid fast, finally stopped refreshing my phone waiting for results. Main agent + concurrent subagents is clearly the direction. Seeing more tools start shipping this workflow lately.

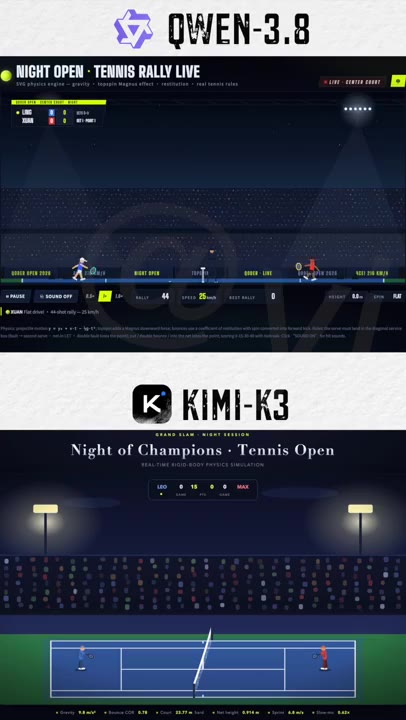
Qwen-3.8 vs Kimi-K3
Prompt: "SVG animation of a real tennis rally, two players going at it, physically accurate, follows real-world logic." This one took me 2 hours to generate. Maybe that's on Qoder, not sure. Qwen-3.8 spent 40+ min just thinking and planning, then another hour writing the files and squashing bugs. But the result? Genuinely clean. It's got sound, and a bottom bar showing live commentary, ball speed, rally count, and shot analysis. Kimi-K3? No sound, and the stats bar is buggy. Doesn't update in real time.
OpenRouter, Carpooling edition.
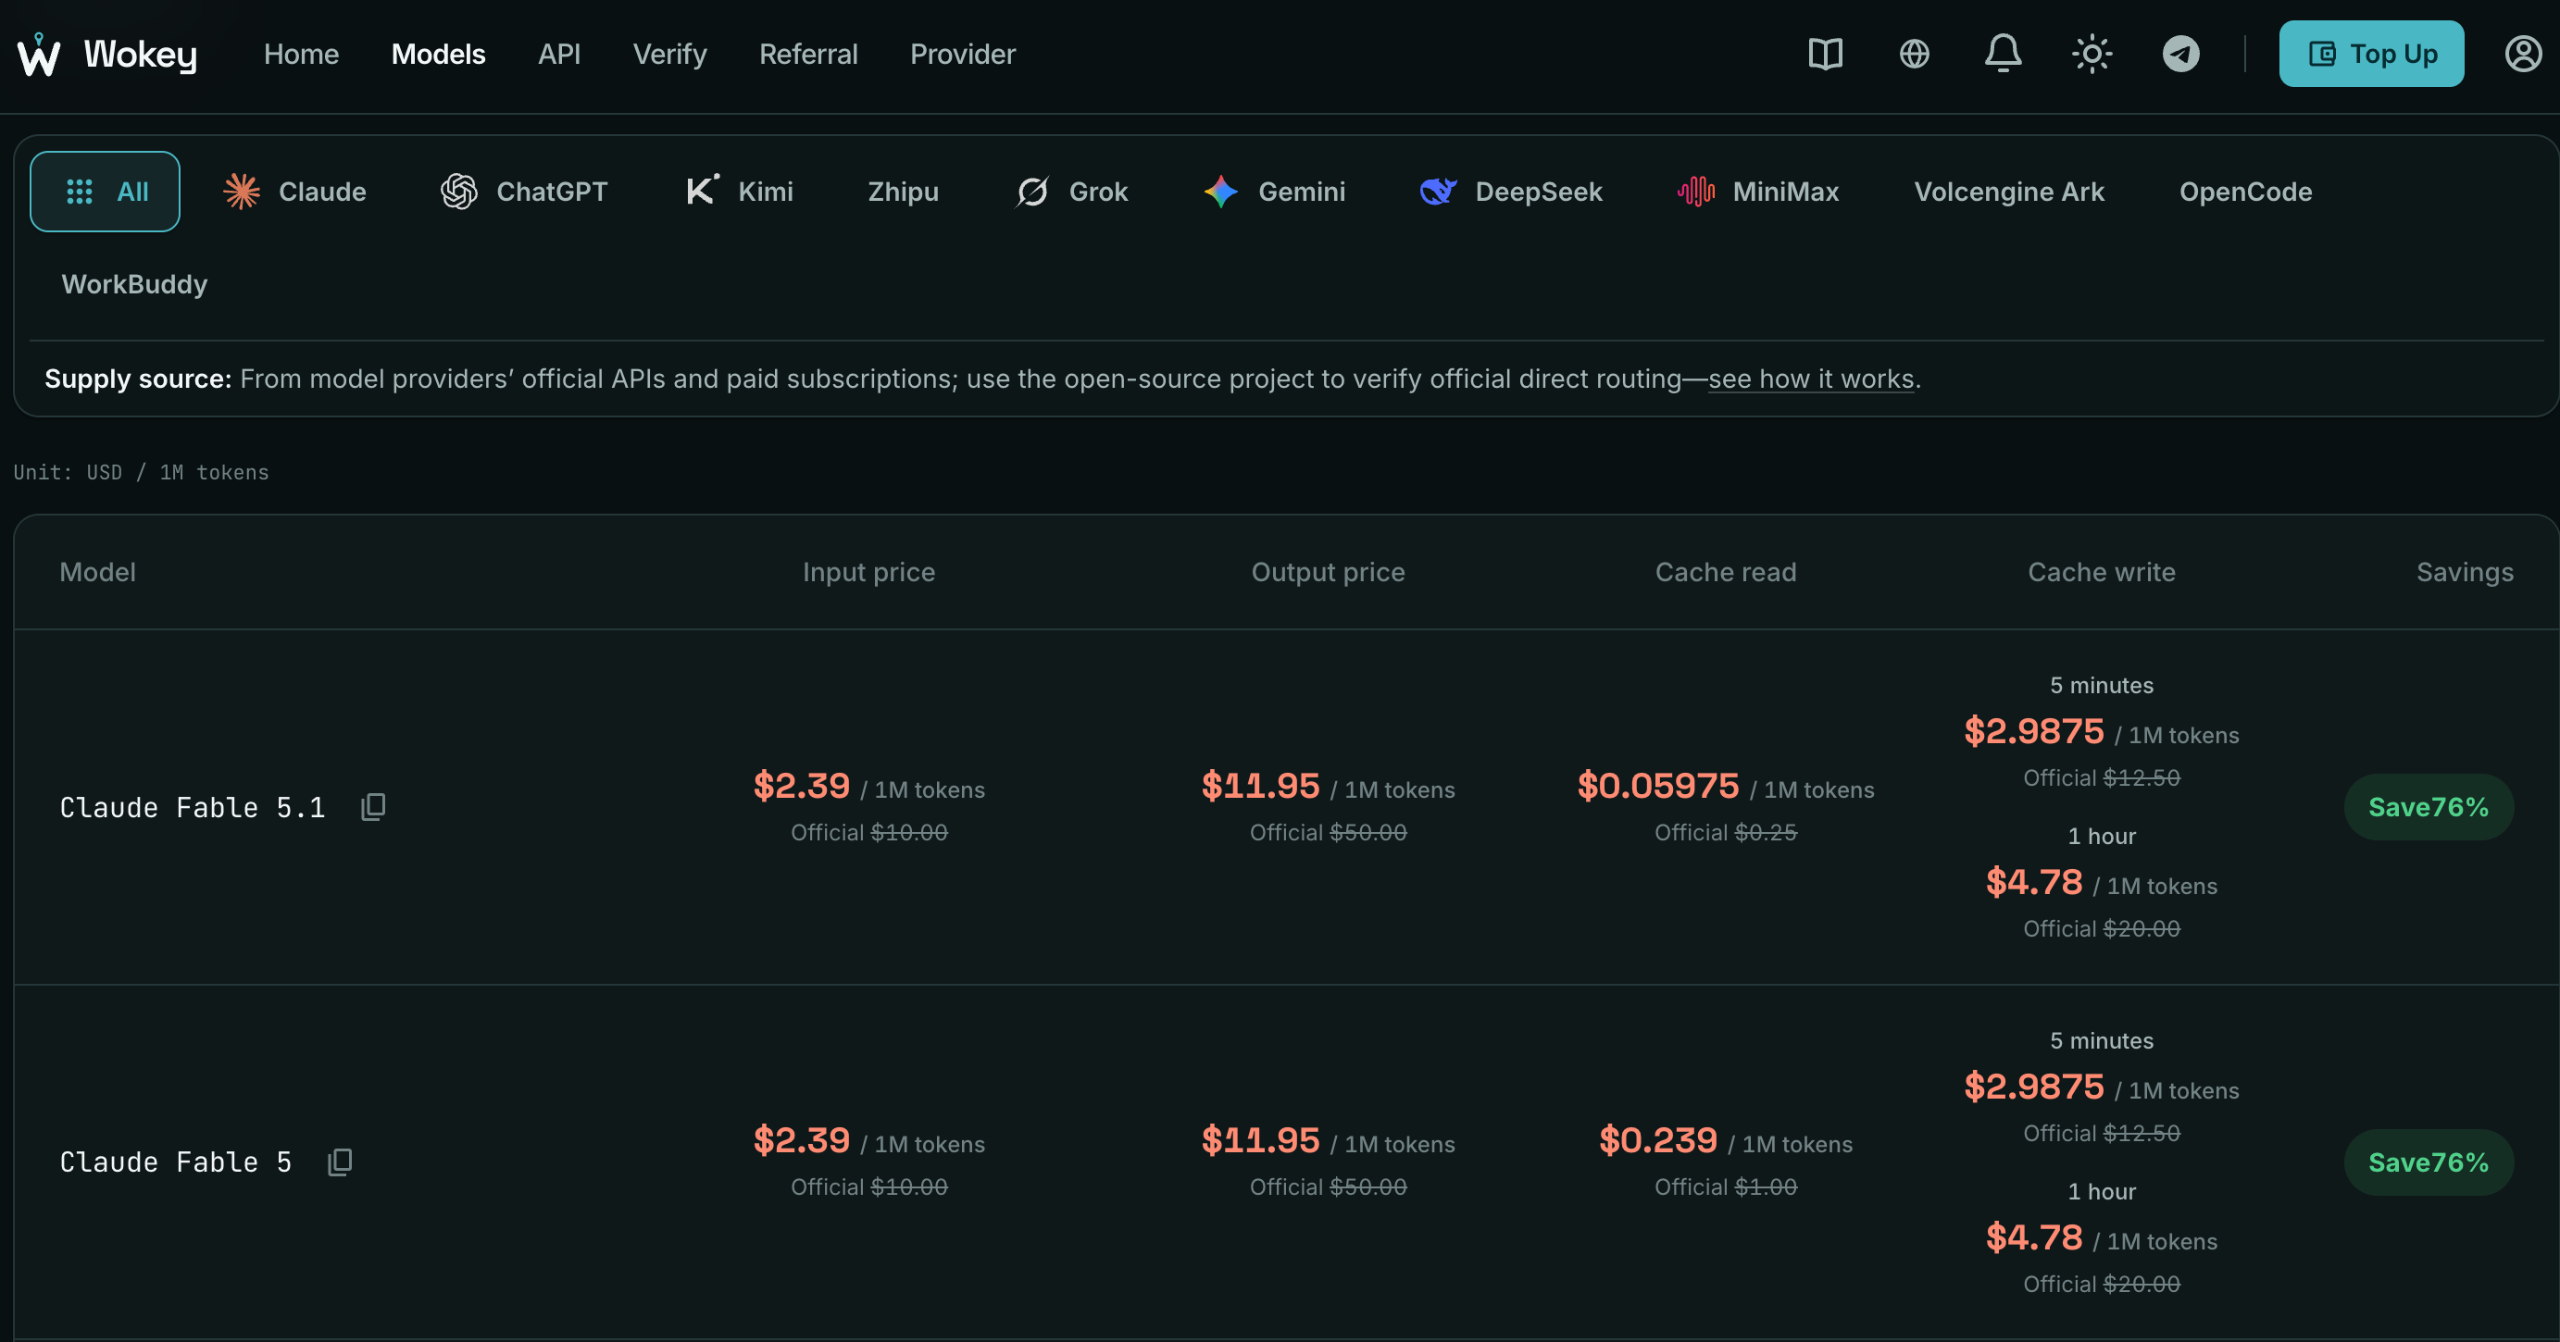
wokey is a marketplace for LLM quota. It pairs people with unused plan credits to people who need more, and takes a 20% cut. Sellers keep 80% of what their credits earn; buyers save up to 90% of the official API price. I use it mostly for flagship models. The models check out as the real thing, cost less than going direct, and I skip the subscription jugglingling. If all you call are cheap models, a router still beats it. 🔗 https://wokey.ai/r/GKT1C78R

Meituan shipped LongCat-2.5
. 1.6T params, ~48B active, native multimodal, aimed at long-horizon agents, trained start to finish on Chinese hardware. Images get quantized into multi-level discrete tokens, and that's where Visual Coding and 3D pick up. On the RL side, failed trajectories get turned back into verifiable training tasks. W4A4 inference, 43% faster prefill. Meituan's own evals put it between Claude Opus 4.8 and Opus 5.