macbook gets a dynamic island
stress tested DeepSeek-v4-flash-0731 full-stack coding — built a macOS Dynamic Island app. media controls, file stash, system info, all docked in the notch.
backend is on par with GLM-5.2. frontend? zero chance. no vision modality means it's coding blind.
setup: Pi native coding agent, no skills, no subagents, no extensions. one model, one session, whole project.
features took 2 hours — 1M+ tokens, 99% cache. UI polish (rounded corners, animations) took a full day. ~40 RMB total.
do NOT use DS for UI animation work. one animation stumped me for half a day. gave up, opened Grok-4.5, 10 min done lol
open sourced, grab and build on it: https://github.com/haoyiyin/dao
macbook gets a dynamic island
More posts
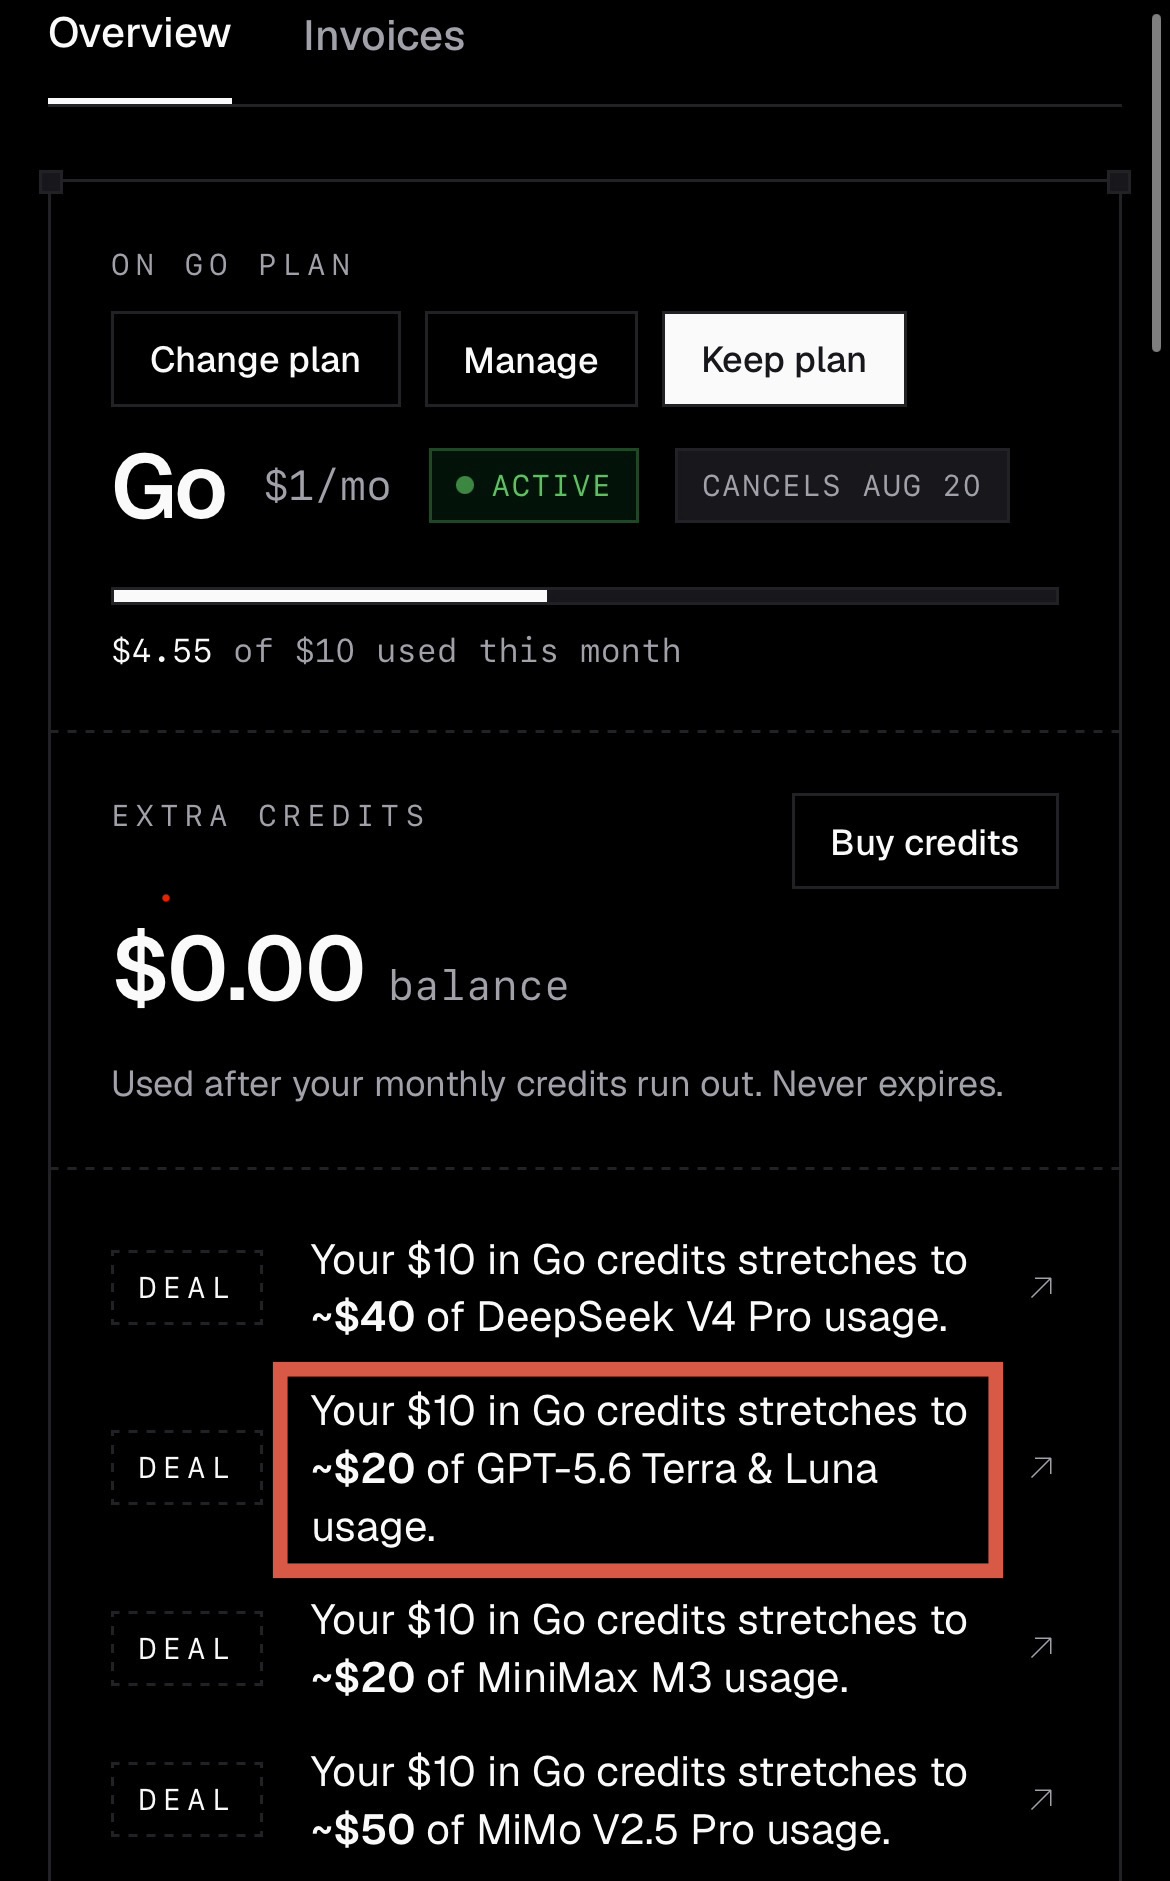
CommandCode $1 plan got GPT-5.6-Luna now too, but the credit cap
is just $20, DeepSeek-V4-Pro gives you $40 at the same tier.
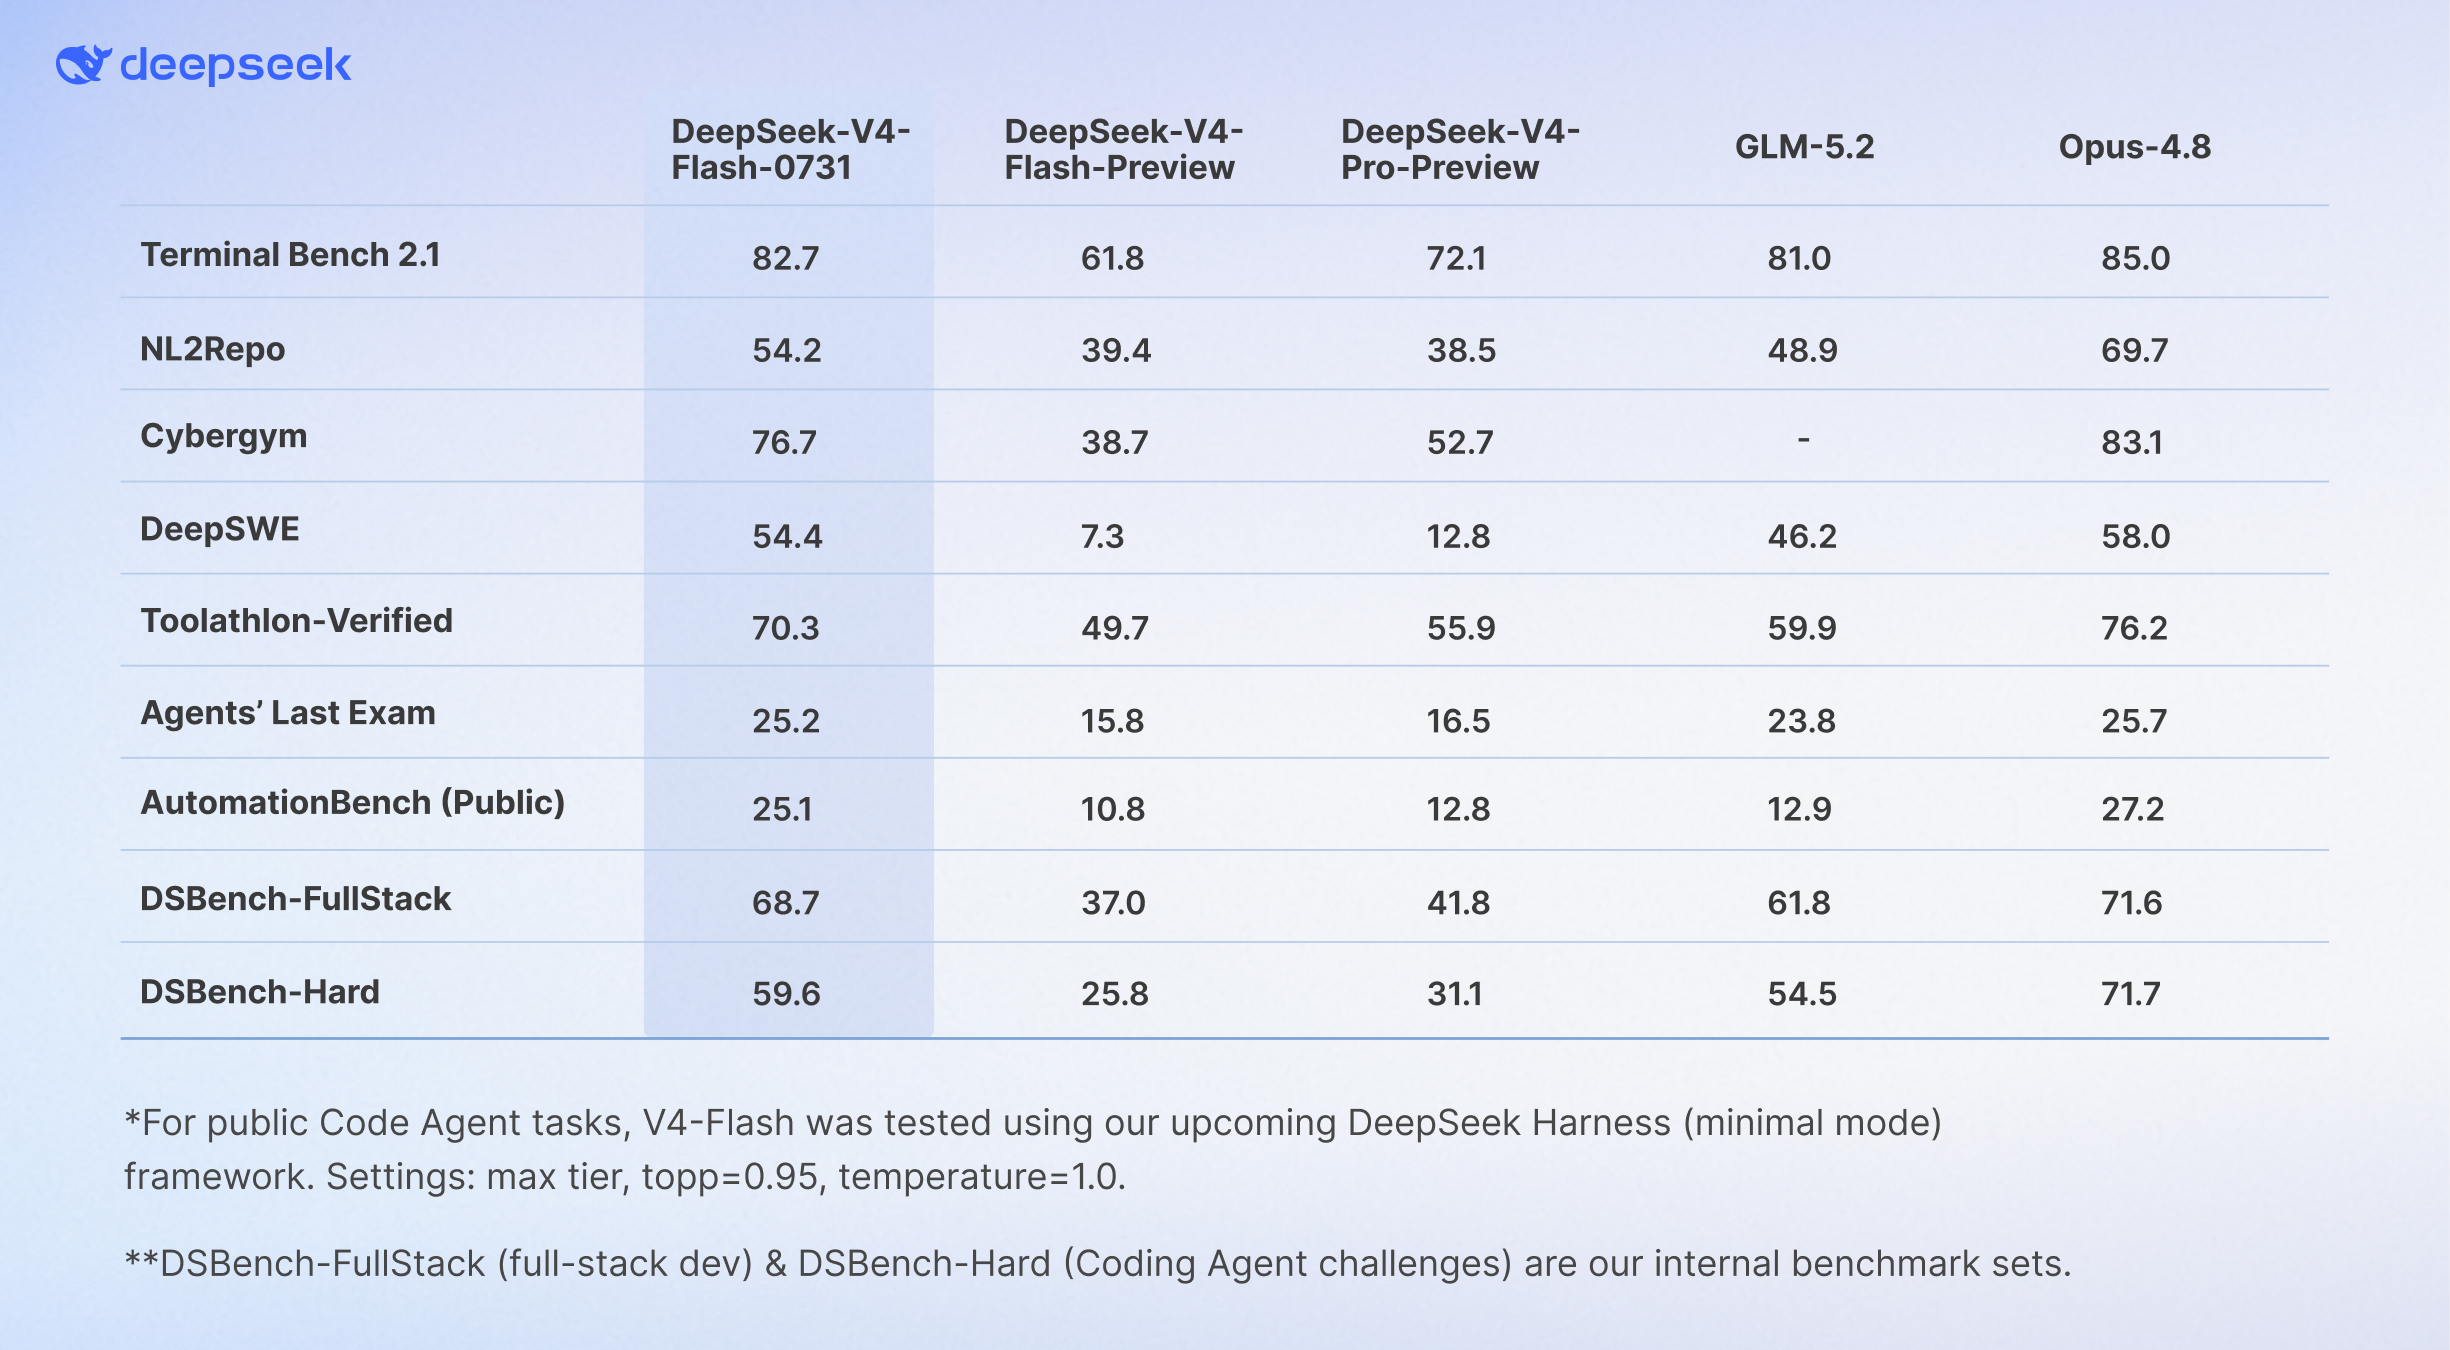
DeepSeek-V4-Flash just dropped. It's eating GLM-5.2 alive.
Same params, no new architecture — just post-training. Per the official writeup, it now tops multiple agent benchmarks. DeepSWE: 7.3 → 54.4 Terminal Bench 2.1: 82.7, nipping at Opus-4.8's 85 If the Flash tier is already this strong, V4-Pro at release is going to be unhinged.
Meituan shipped LongCat-2.5
. 1.6T params, ~48B active, native multimodal, aimed at long-horizon agents, trained start to finish on Chinese hardware. Images get quantized into multi-level discrete tokens, and that's where Visual Coding and 3D pick up. On the RL side, failed trajectories get turned back into verifiable training tasks. W4A4 inference, 43% faster prefill. Meituan's own evals put it between Claude Opus 4.8 and Opus 5.

SenseTime open-sourced SenseNova Loop-9B-Preview.
It stacks layers instead of parameters. The decoder has 32 layers, but layers 4 through 27 run twice with shared weights, so a forward pass does 56 layers of work while the checkpoint stays at 9B. Their own eval numbers: 71.38 on BIRD-Dev and 13.72 on AutomationBench, both above Qwen3.5-27B. Terminal Bench is still behind.
