Marketing genius over at Cursor, honestly.
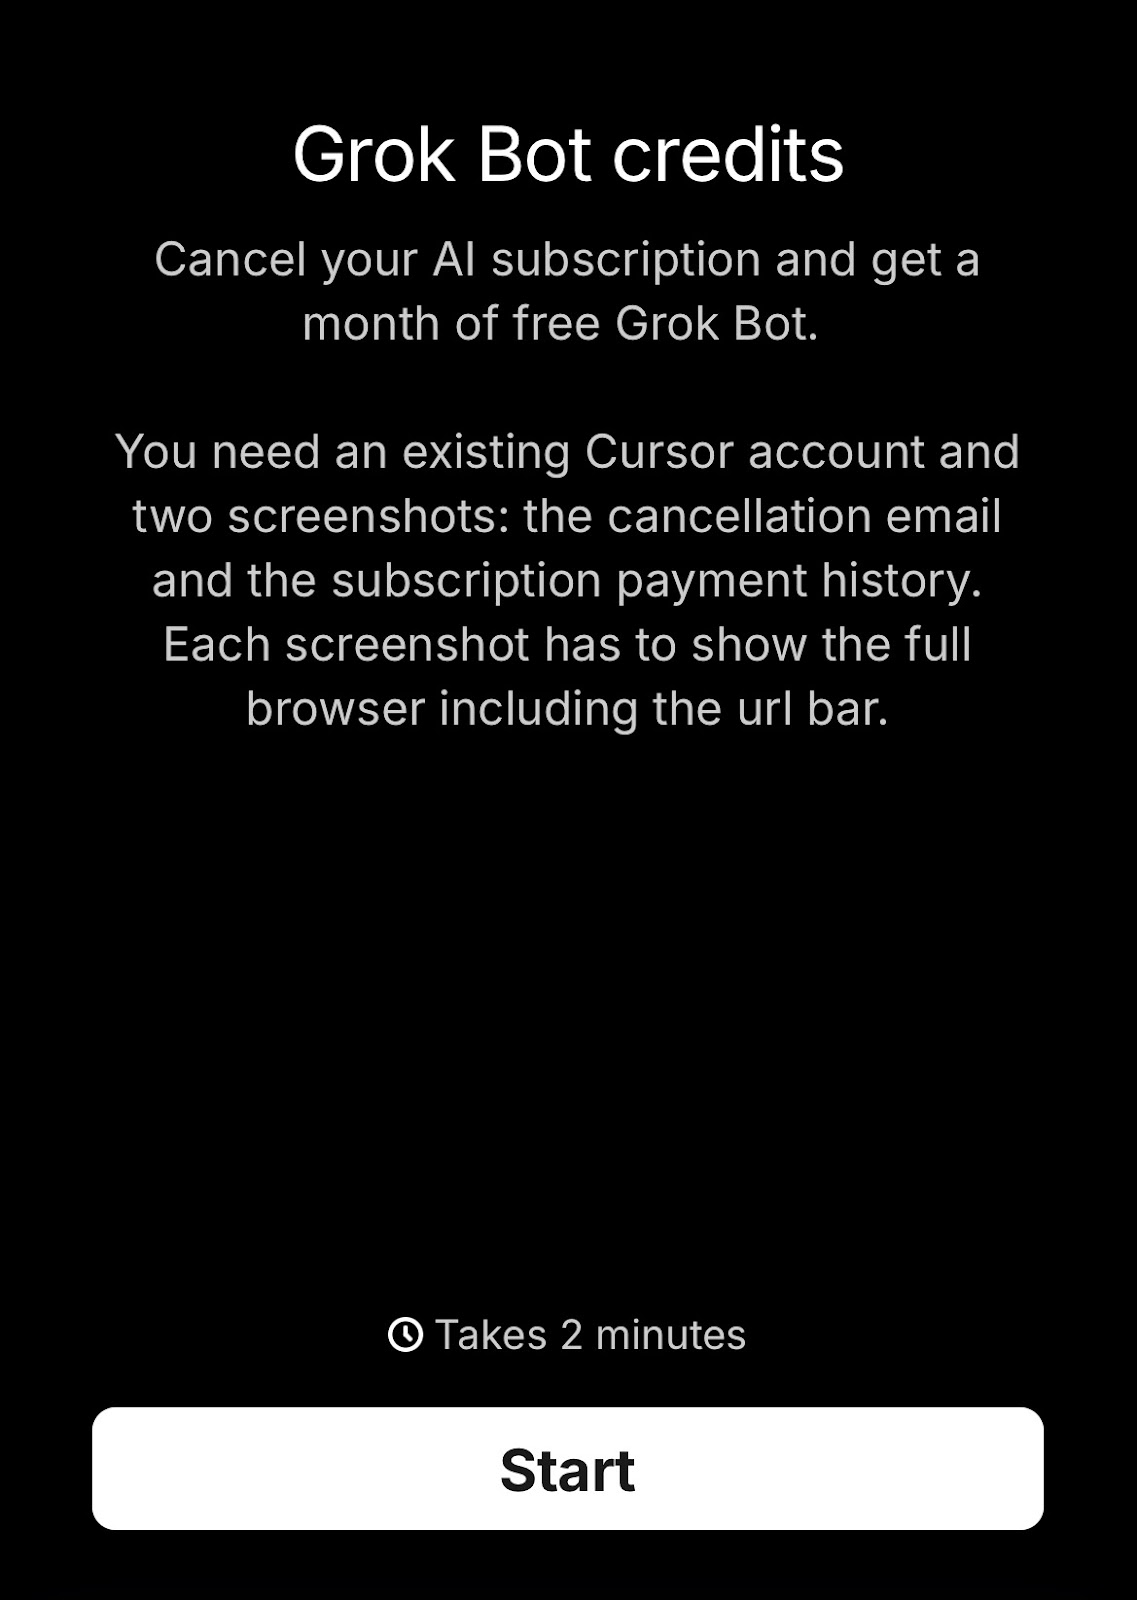
They're running a promo: cancel your other AI subs and you get a free month of Grok Bot (the $200 plan).
🔗 anysphere.typeform.com/grokbot
More posts
prompts? Compared notes with a few people, same impression across the board. It keeps misreading what you ask in Chinese. Some say Meta is quietly nerfing the version it serves Chinese users. Maybe. I think the model's just weak in Chinese.
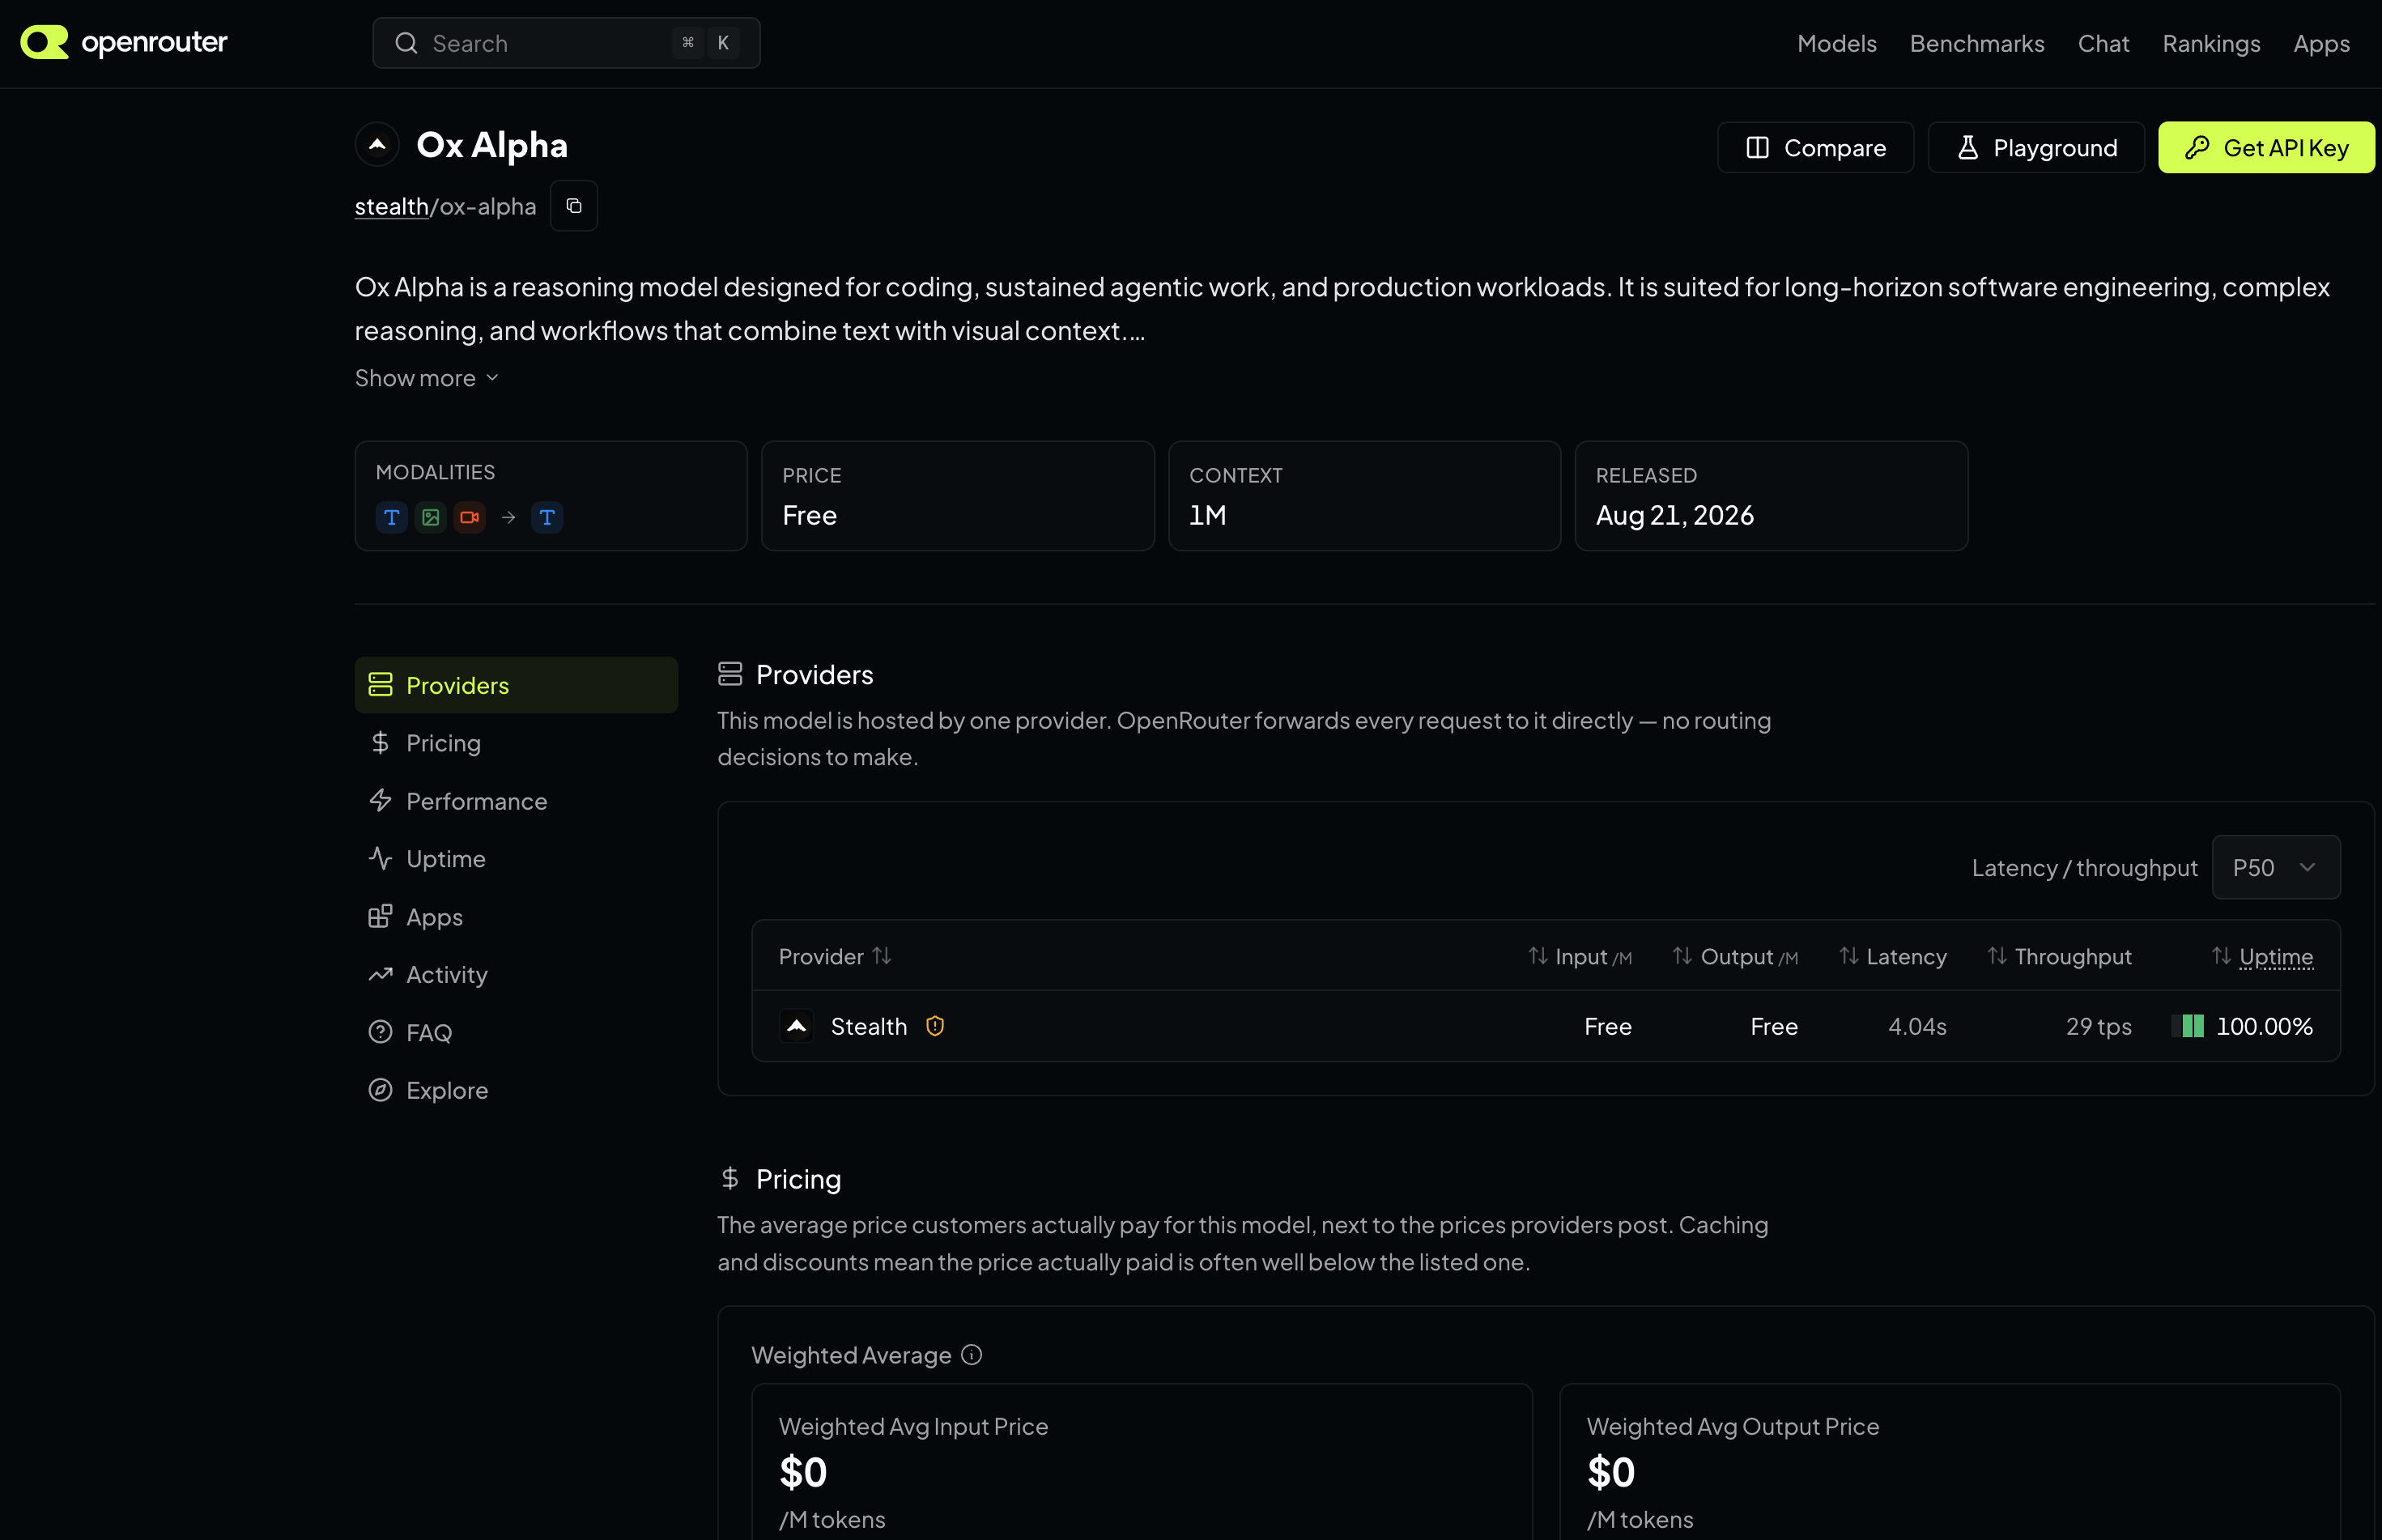
Some anon dev under the name "Stealth" just dropped a frontier model, Ox Alpha. Free on OpenRouter atm, and it's already #1 on the usage leaderboard. Multimodal: takes text/image/video, outputs text. 1M context, 128K max output. From the config alone, I'm betting this is Mimo-3-Pro.
. 1.6T params, ~48B active, native multimodal, aimed at long-horizon agents, trained start to finish on Chinese hardware. Images get quantized into multi-level discrete tokens, and that's where Visual Coding and 3D pick up. On the RL side, failed trajectories get turned back into verifiable training tasks. W4A4 inference, 43% faster prefill. Meituan's own evals put it between Claude Opus 4.8 and Opus 5.

It stacks layers instead of parameters. The decoder has 32 layers, but layers 4 through 27 run twice with shared weights, so a forward pass does 56 layers of work while the checkpoint stays at 9B. Their own eval numbers: 71.38 on BIRD-Dev and 13.72 on AutomationBench, both above Qwen3.5-27B. Terminal Bench is still behind.
