Holy shit, Grok bot weekly quota just reset.
More posts
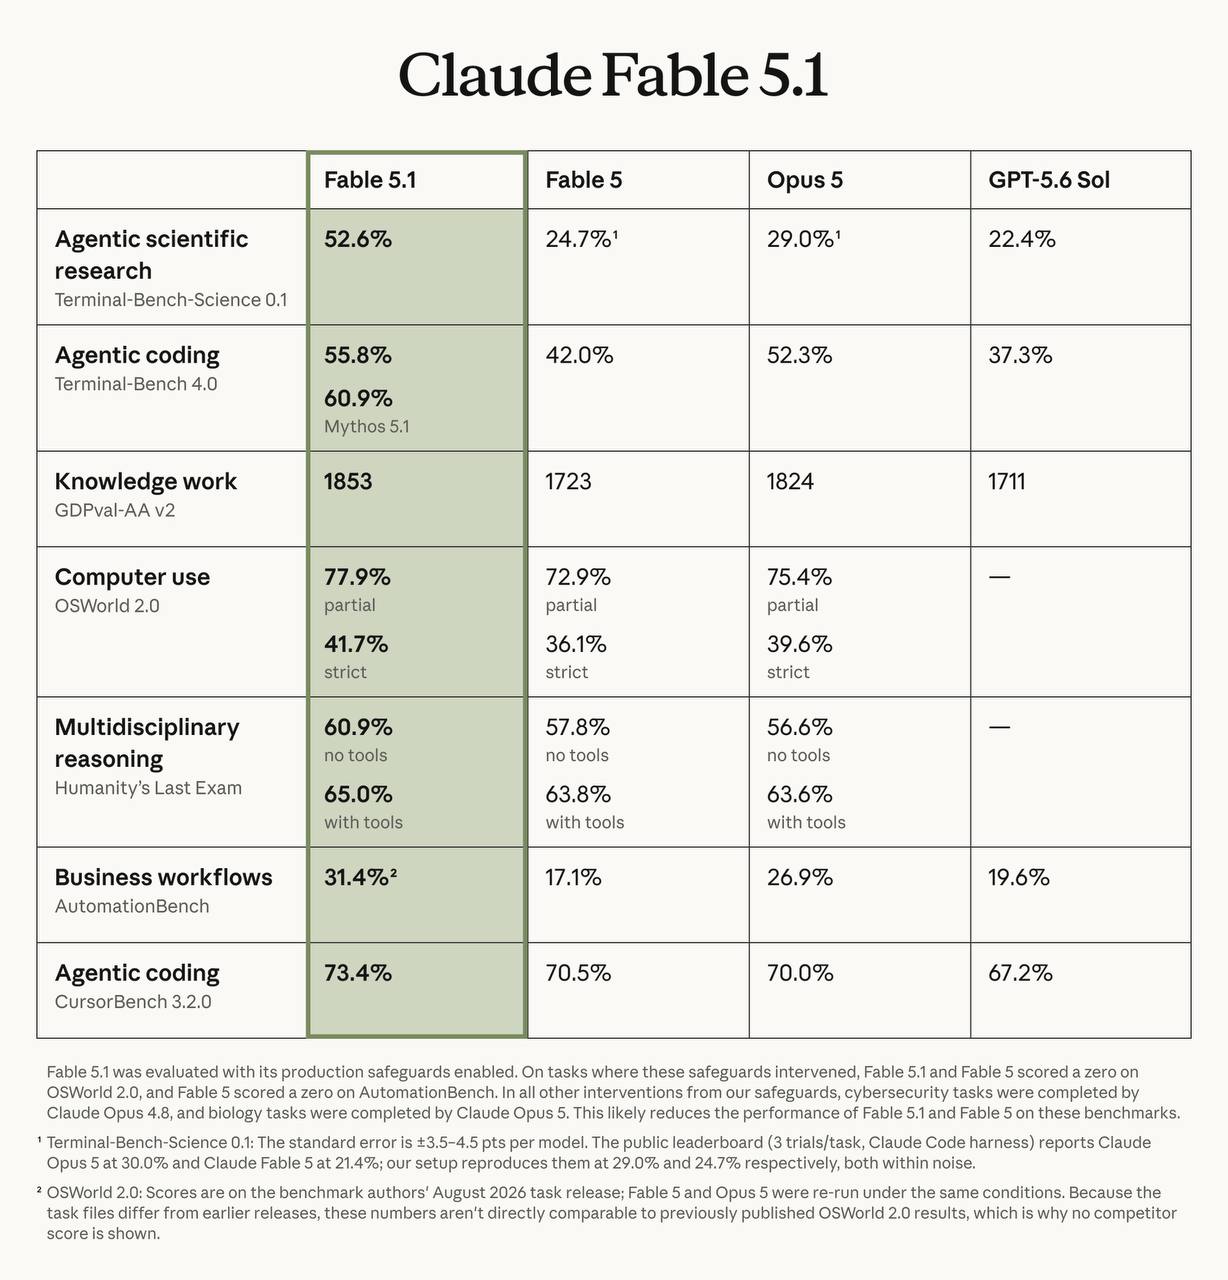
. Coding scores 55.8% on Terminal-Bench, research doubled to 52.6%. Cache is 75% cheaper now, so real costs land 25-45% lower. API prices unchanged.
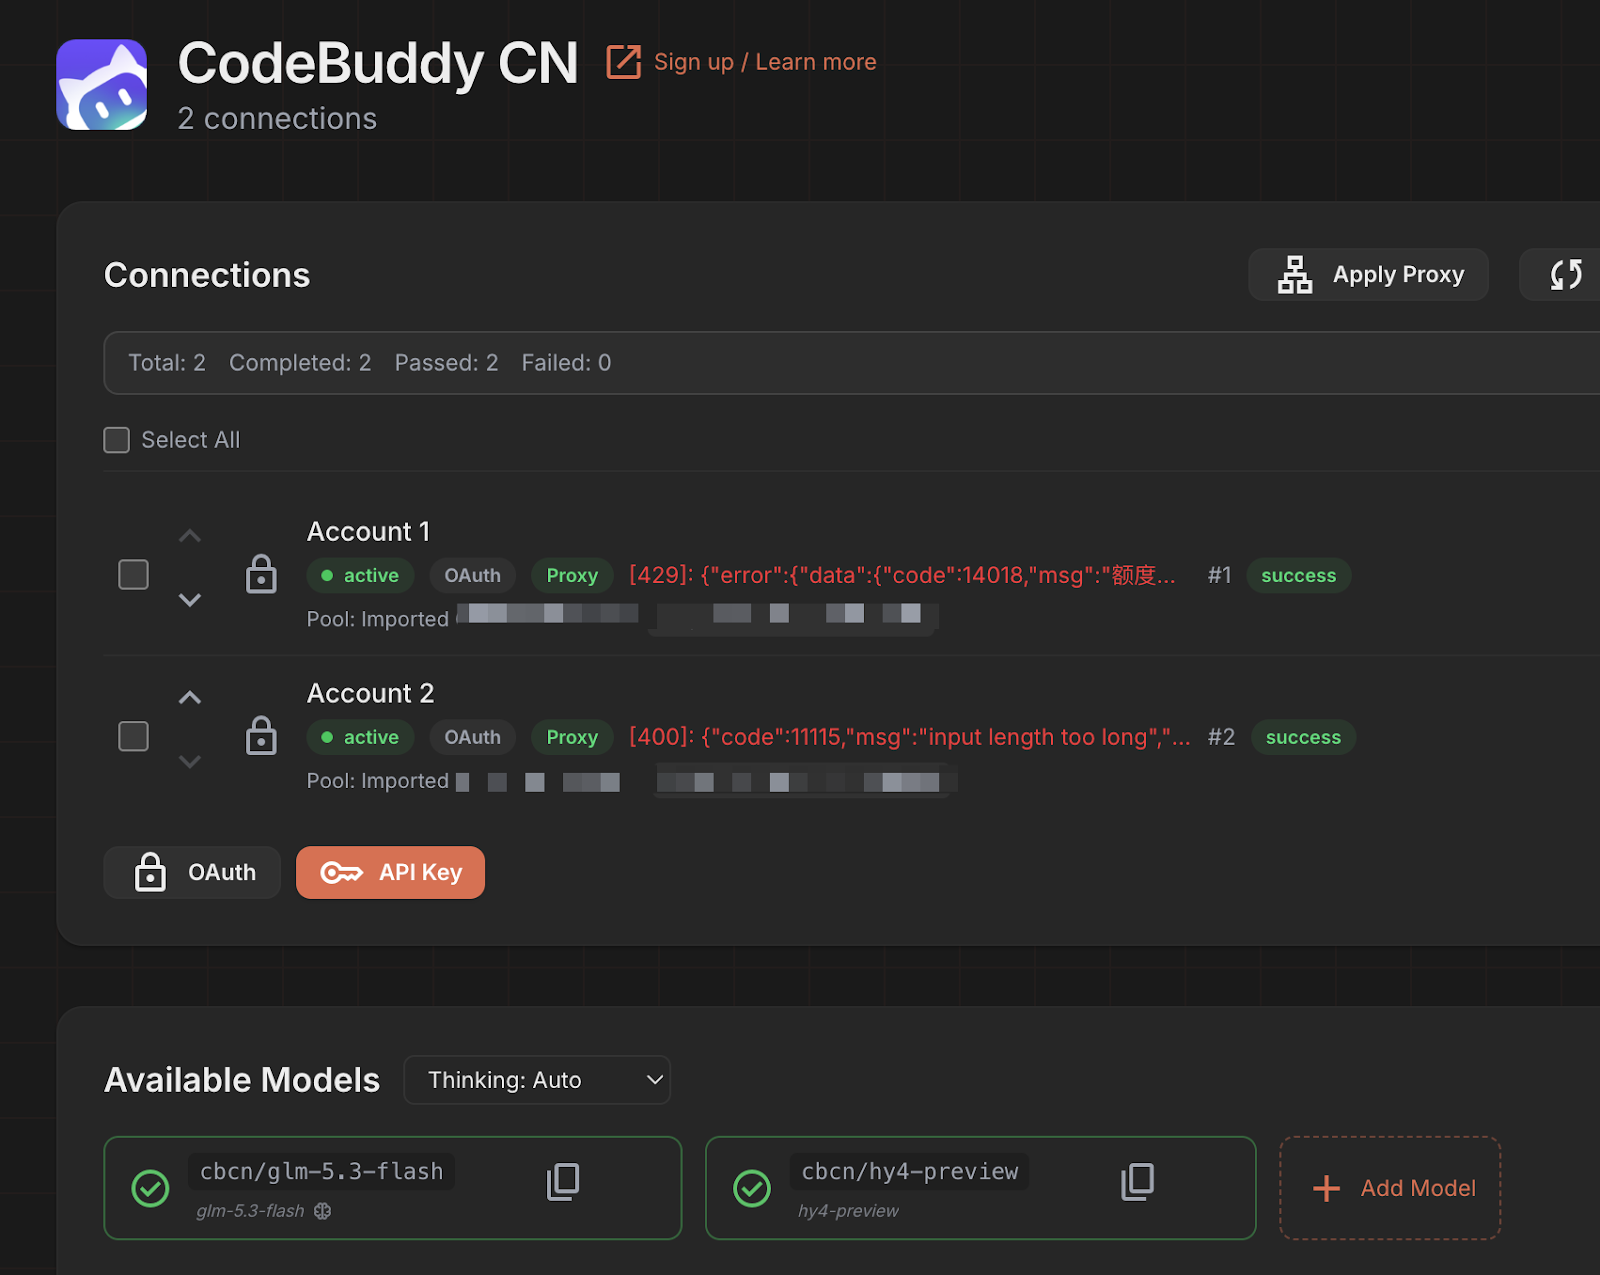
. workbuddy CLI picked up both too. Haven't touched hy-4 yet, but glm-5.3-flash has been my daily driver for a day. Follows instructions tightly, fast, and just a hair pricier than muse-spark-1.2-contributor-free. Best value model right now, IMO.
. 1.6T params, ~48B active, native multimodal, aimed at long-horizon agents, trained start to finish on Chinese hardware. Images get quantized into multi-level discrete tokens, and that's where Visual Coding and 3D pick up. On the RL side, failed trajectories get turned back into verifiable training tasks. W4A4 inference, 43% faster prefill. Meituan's own evals put it between Claude Opus 4.8 and Opus 5.

It stacks layers instead of parameters. The decoder has 32 layers, but layers 4 through 27 run twice with shared weights, so a forward pass does 56 layers of work while the checkpoint stays at 9B. Their own eval numbers: 71.38 on BIRD-Dev and 13.72 on AutomationBench, both above Qwen3.5-27B. Terminal Bench is still behind.
