Meta shipped Muse in the US — an AI agent that books travel
More posts
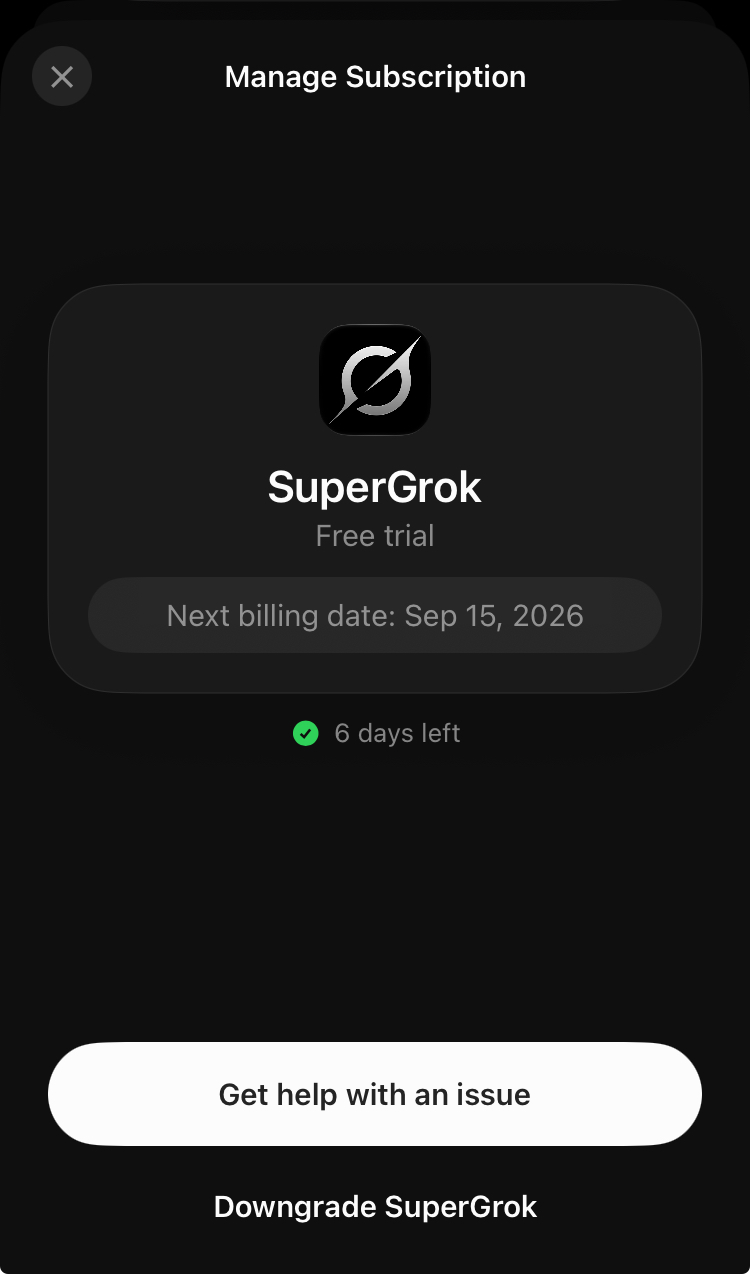
Grok gave me a free 7-day SuperGrok trial and it was awful
. Big companies really play dirty with this — trial or not, you're still a SuperGrok user, but grok-4.6 was so gutted a local 38B model runs circles around it. I'd tell it to follow the plan, it says "will do," and then... nothing. I describe what I need, say "ask me if anything's unclear," it replies "ask me" — and that's where the conversation ends. Almost thought it was a tooling bug until I tested with a paid Grok account. Works perfectly fine there.

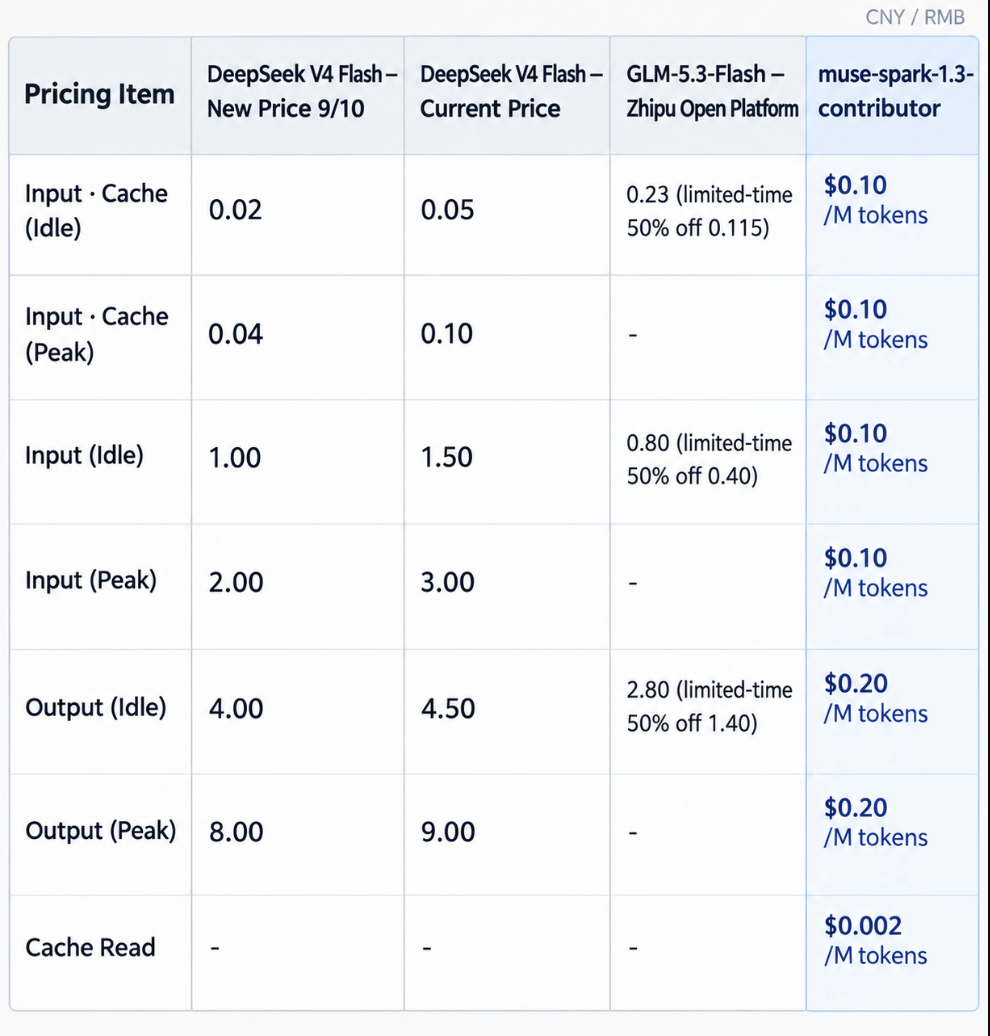
DeepSeek dropped back to its old prices.
Starting 12:00 noon Beijing time, September 10 — Flash series repriced: - Cache hit: ¥0.02/M tokens (back to historical low) - Input, no cache: ¥1 (July 16 pricing) - Output: ¥4 (still double the pre-hike number) Two months of whiplash: April slasher to ¥0.02 (industry floor), then August 16 peak/off-peak surge of 150%-400%, now September 10 pulling back. Price cuts are a race to the bottom — Zhipu GLM 5.3 Flash went half-price to poach users, Meta Muse Spark 1.3 pressuring from the other side.

Meituan shipped LongCat-2.5
. 1.6T params, ~48B active, native multimodal, aimed at long-horizon agents, trained start to finish on Chinese hardware. Images get quantized into multi-level discrete tokens, and that's where Visual Coding and 3D pick up. On the RL side, failed trajectories get turned back into verifiable training tasks. W4A4 inference, 43% faster prefill. Meituan's own evals put it between Claude Opus 4.8 and Opus 5.

SenseTime open-sourced SenseNova Loop-9B-Preview.
It stacks layers instead of parameters. The decoder has 32 layers, but layers 4 through 27 run twice with shared weights, so a forward pass does 56 layers of work while the checkpoint stays at 9B. Their own eval numbers: 71.38 on BIRD-Dev and 13.72 on AutomationBench, both above Qwen3.5-27B. Terminal Bench is still behind.