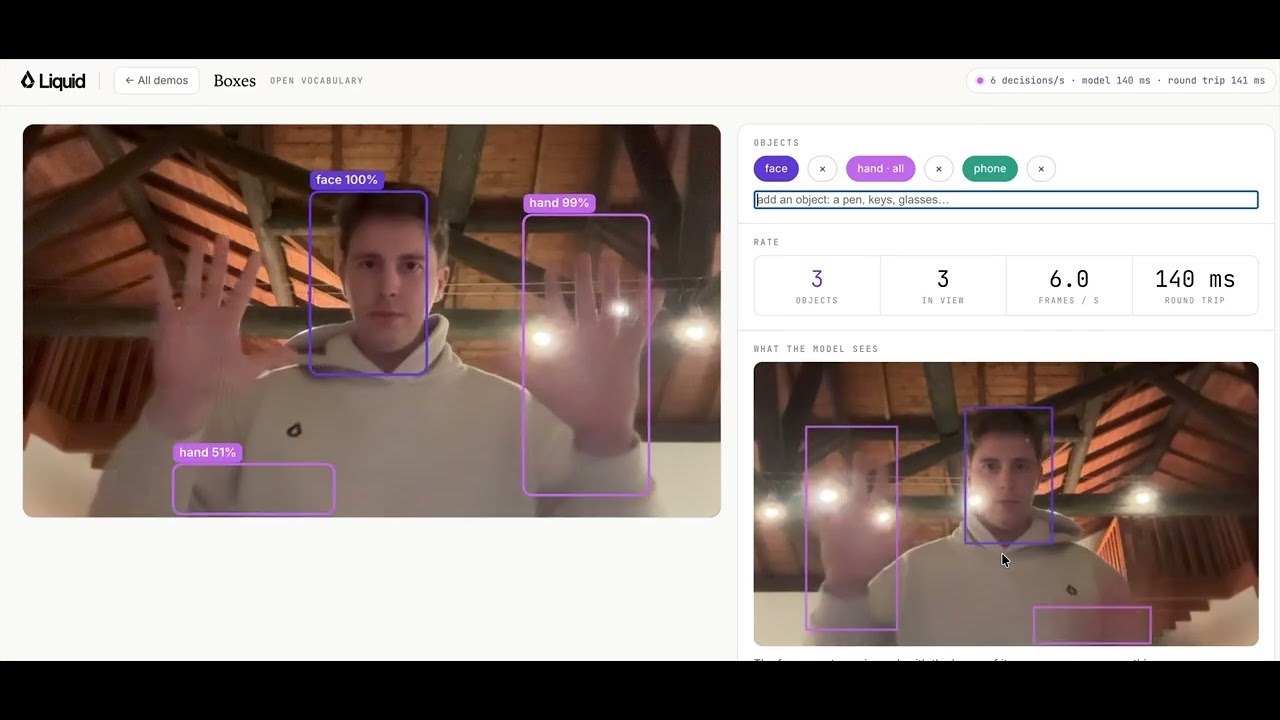
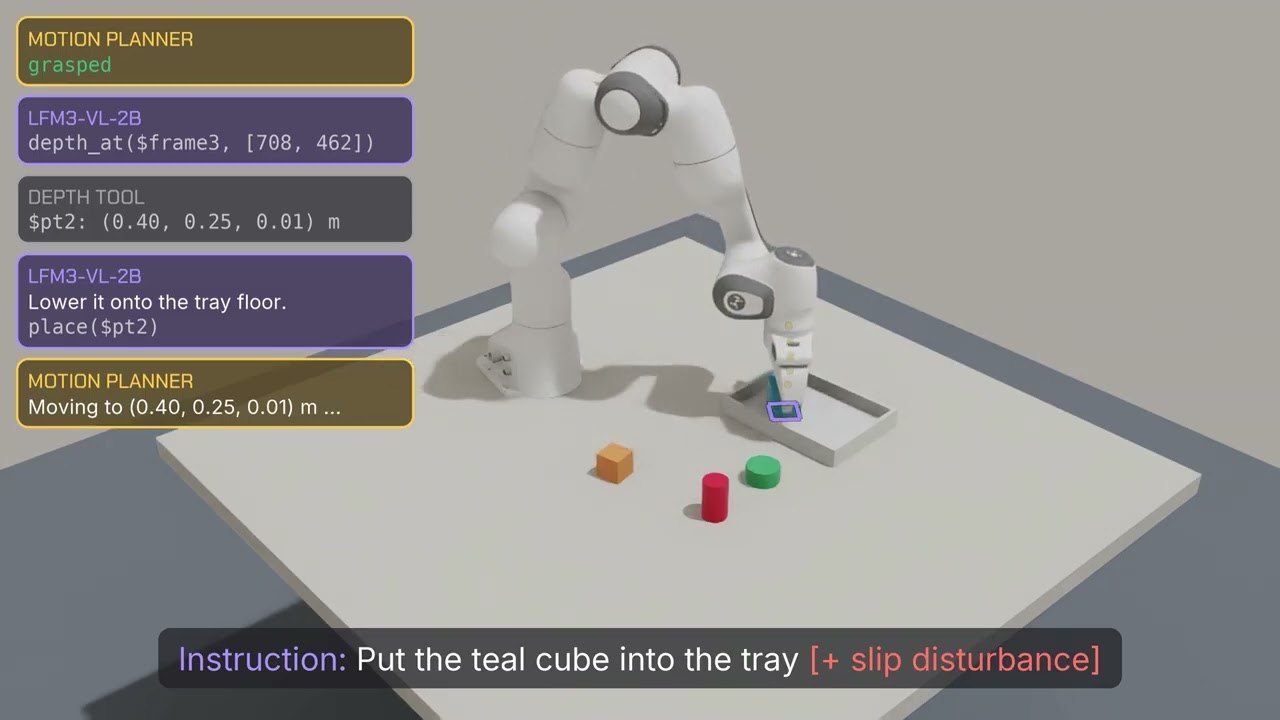
Liquid AI shipped LFM3: a 1.7B backbone, and six models grown off it (text, vision, audio, omni, plus two decision models). All open-weight.
256K context, roughly 1GB at 4-bit, fine-tunes on one GPU.
a full 128K context costs 1.6GB of KV cache. Qwen3.5-4B takes 4.3GB for the same thing.
🔗 https://www.liquid.ai/blog/lfm3