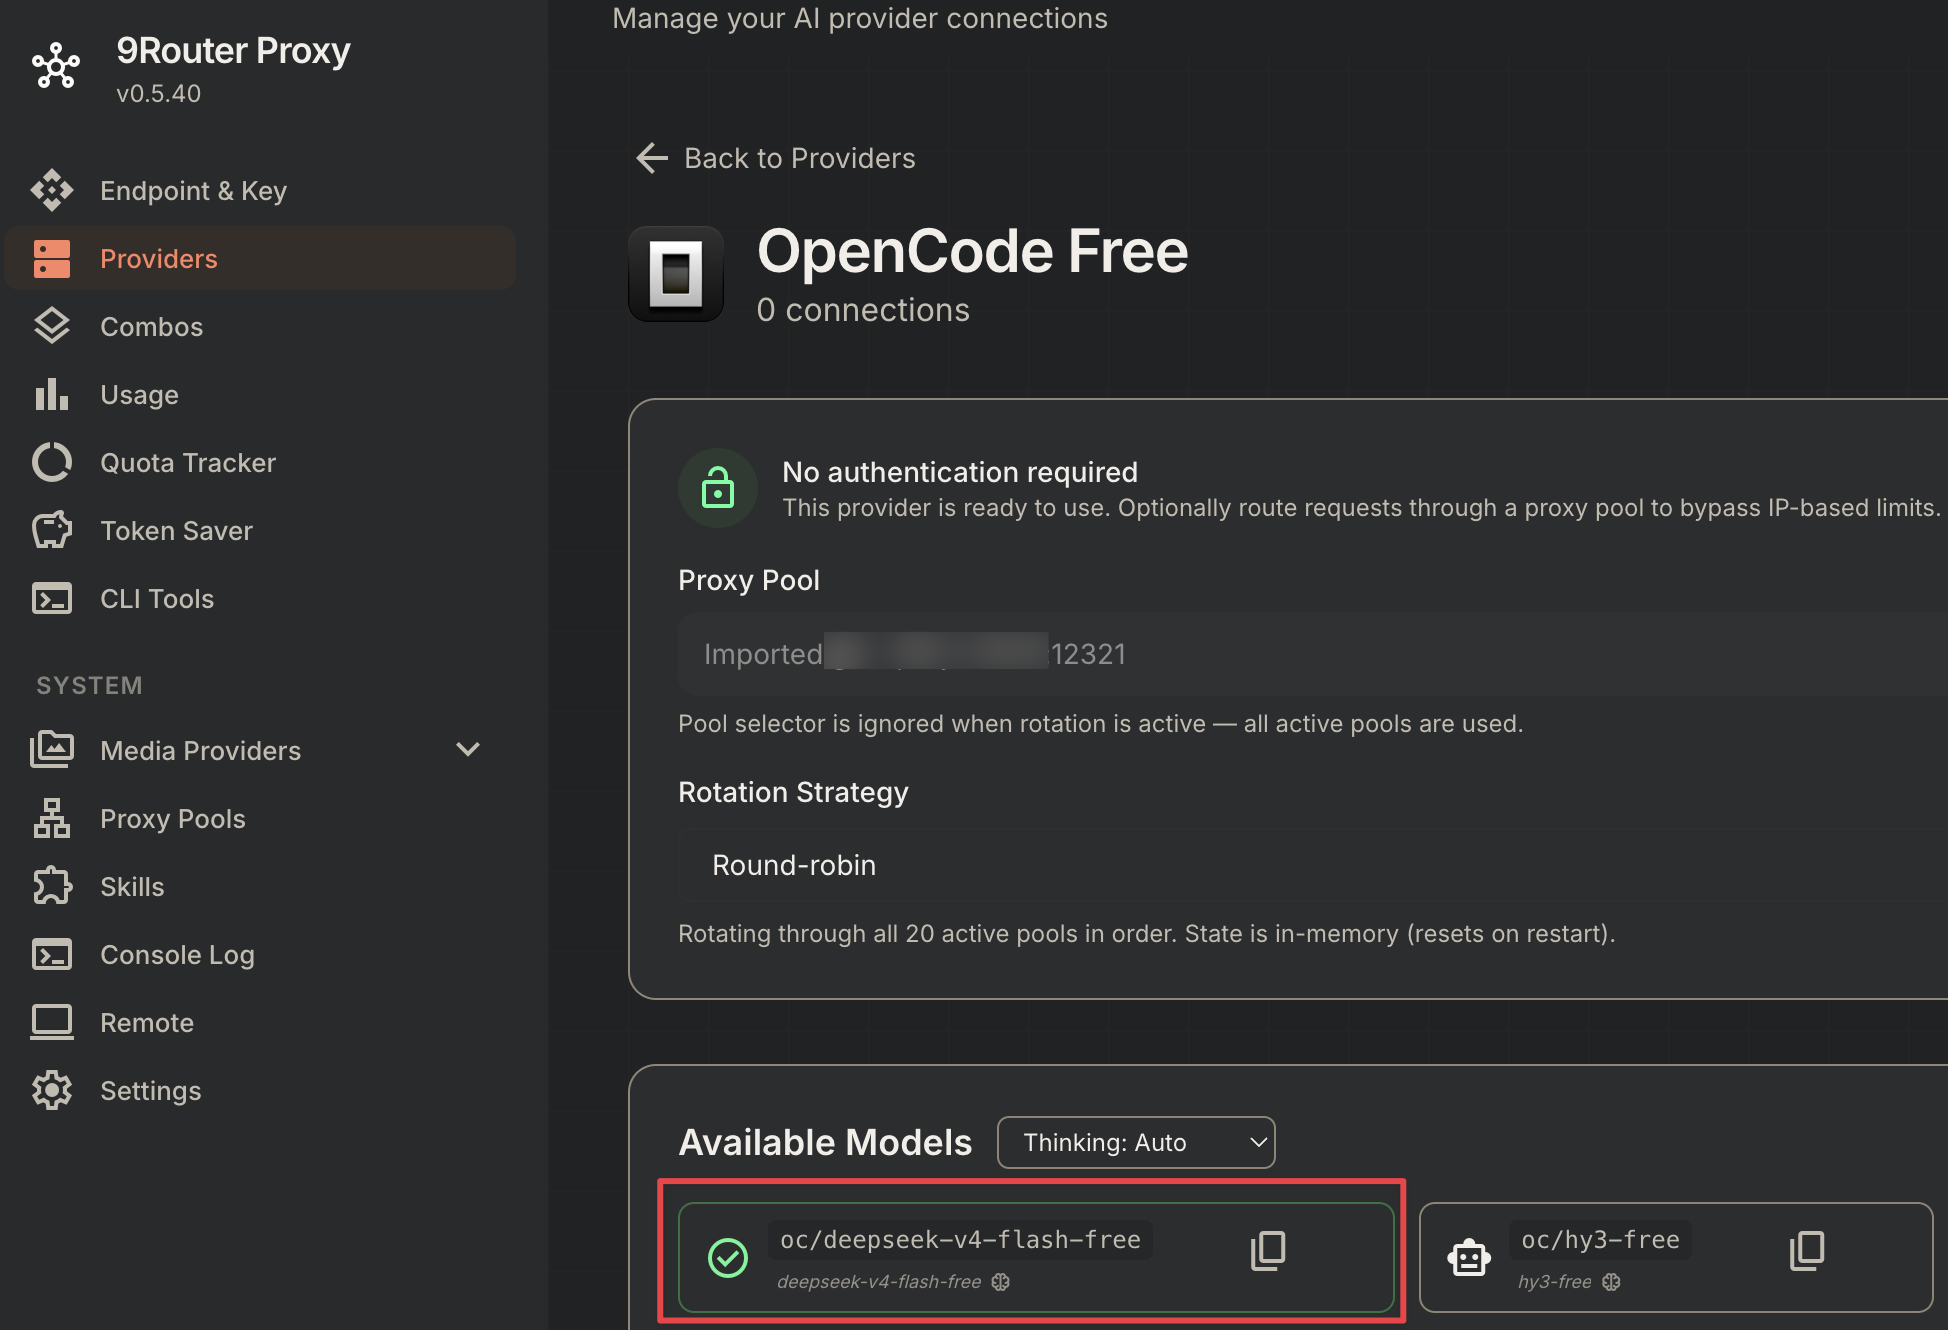
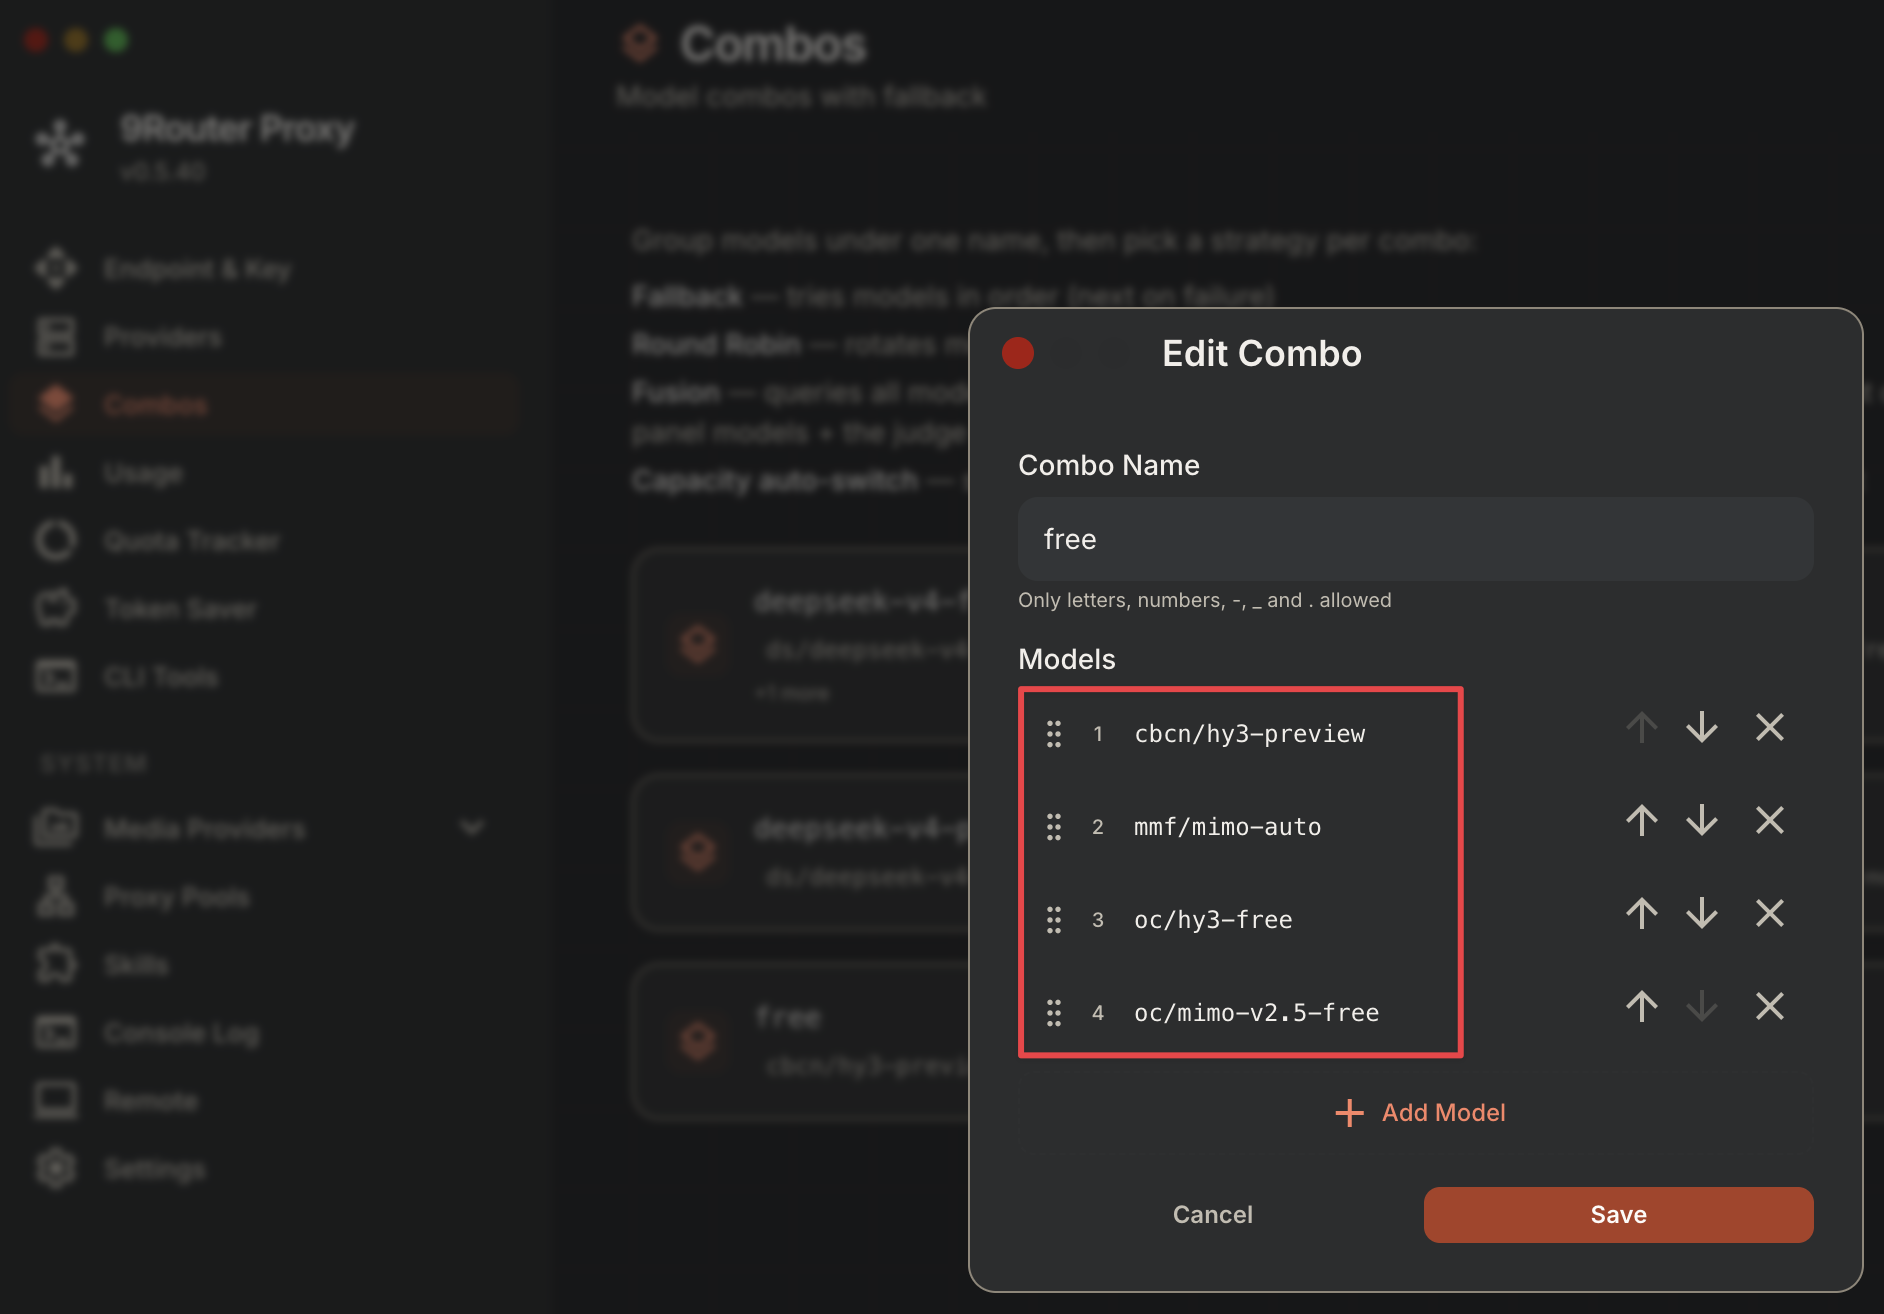
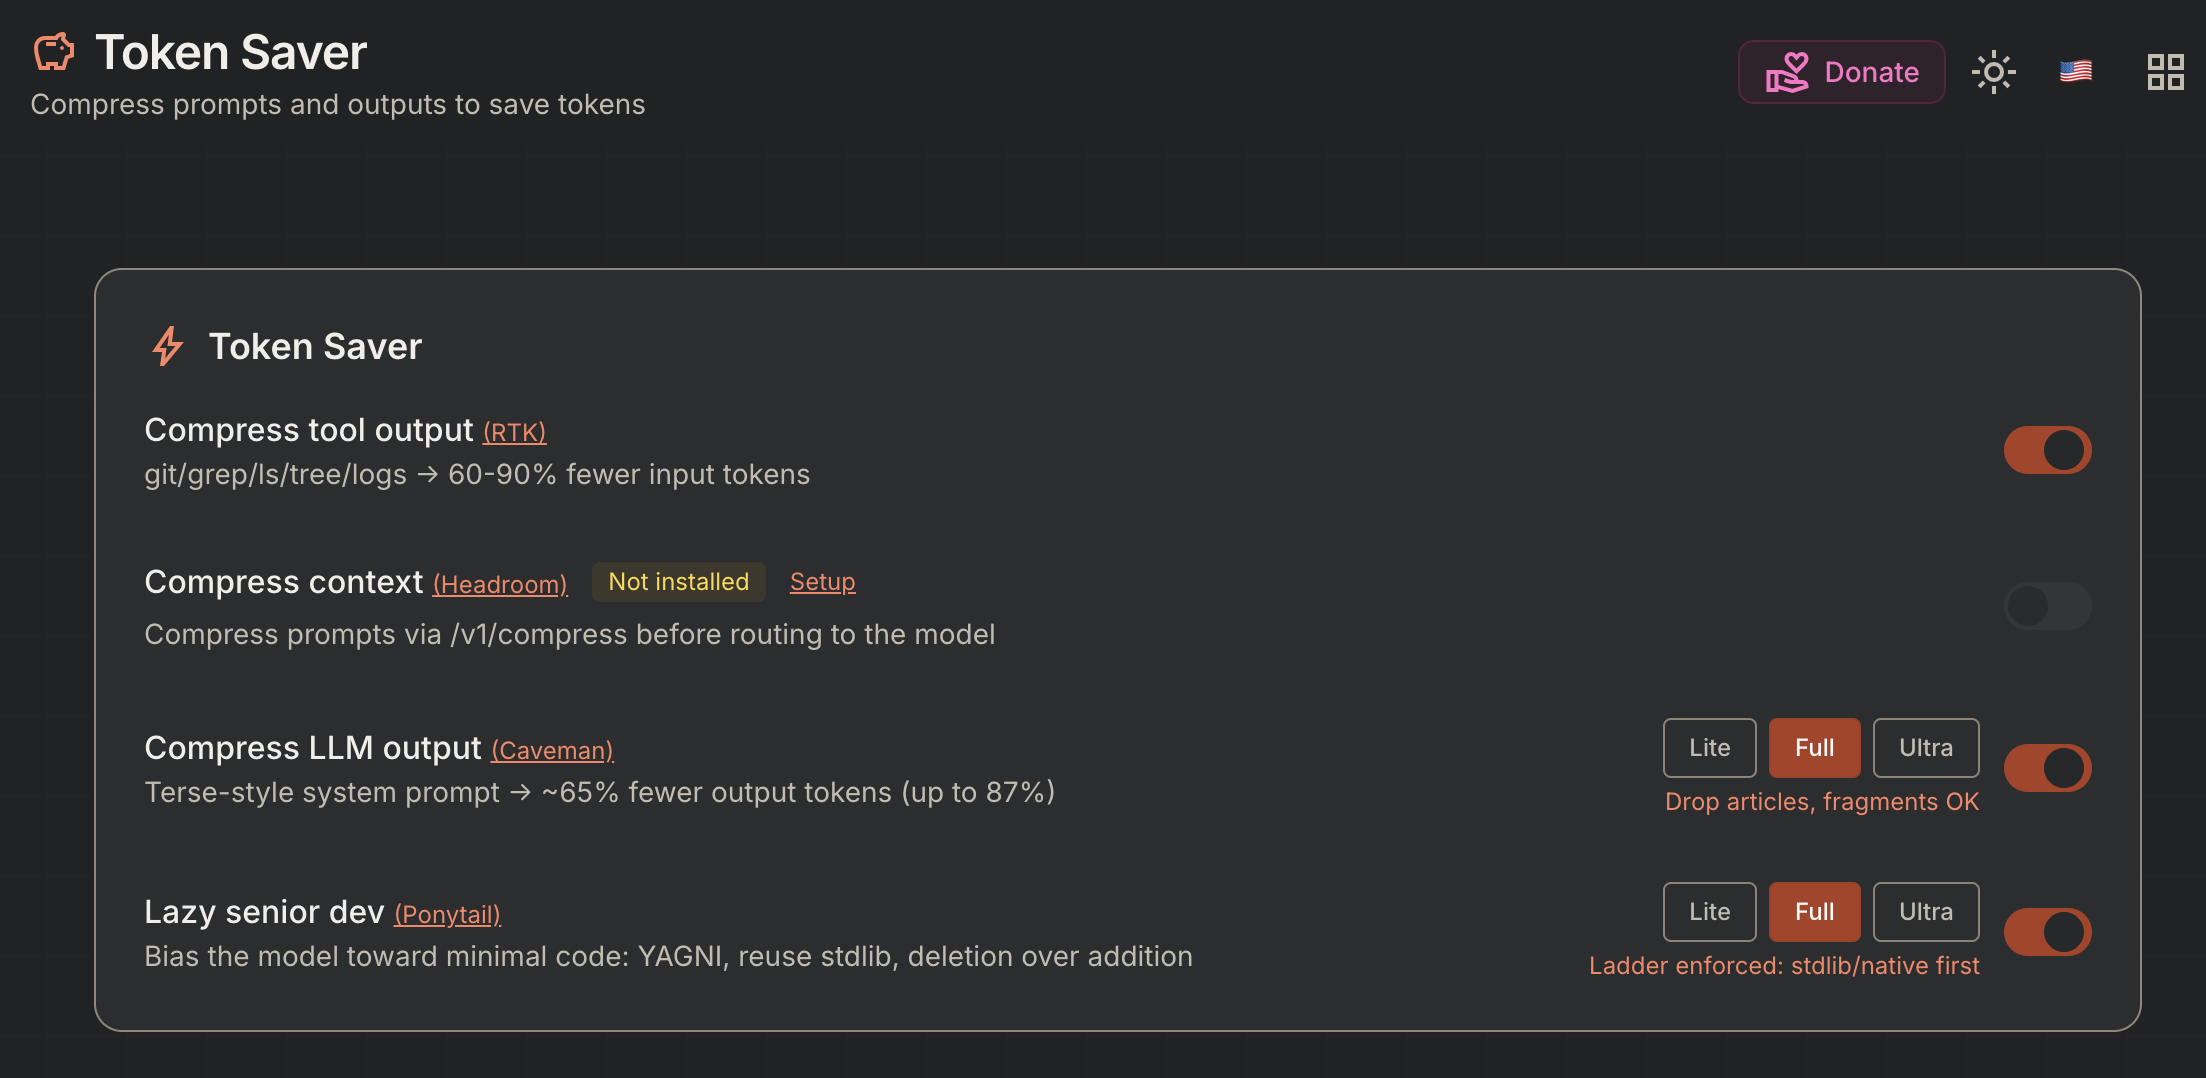
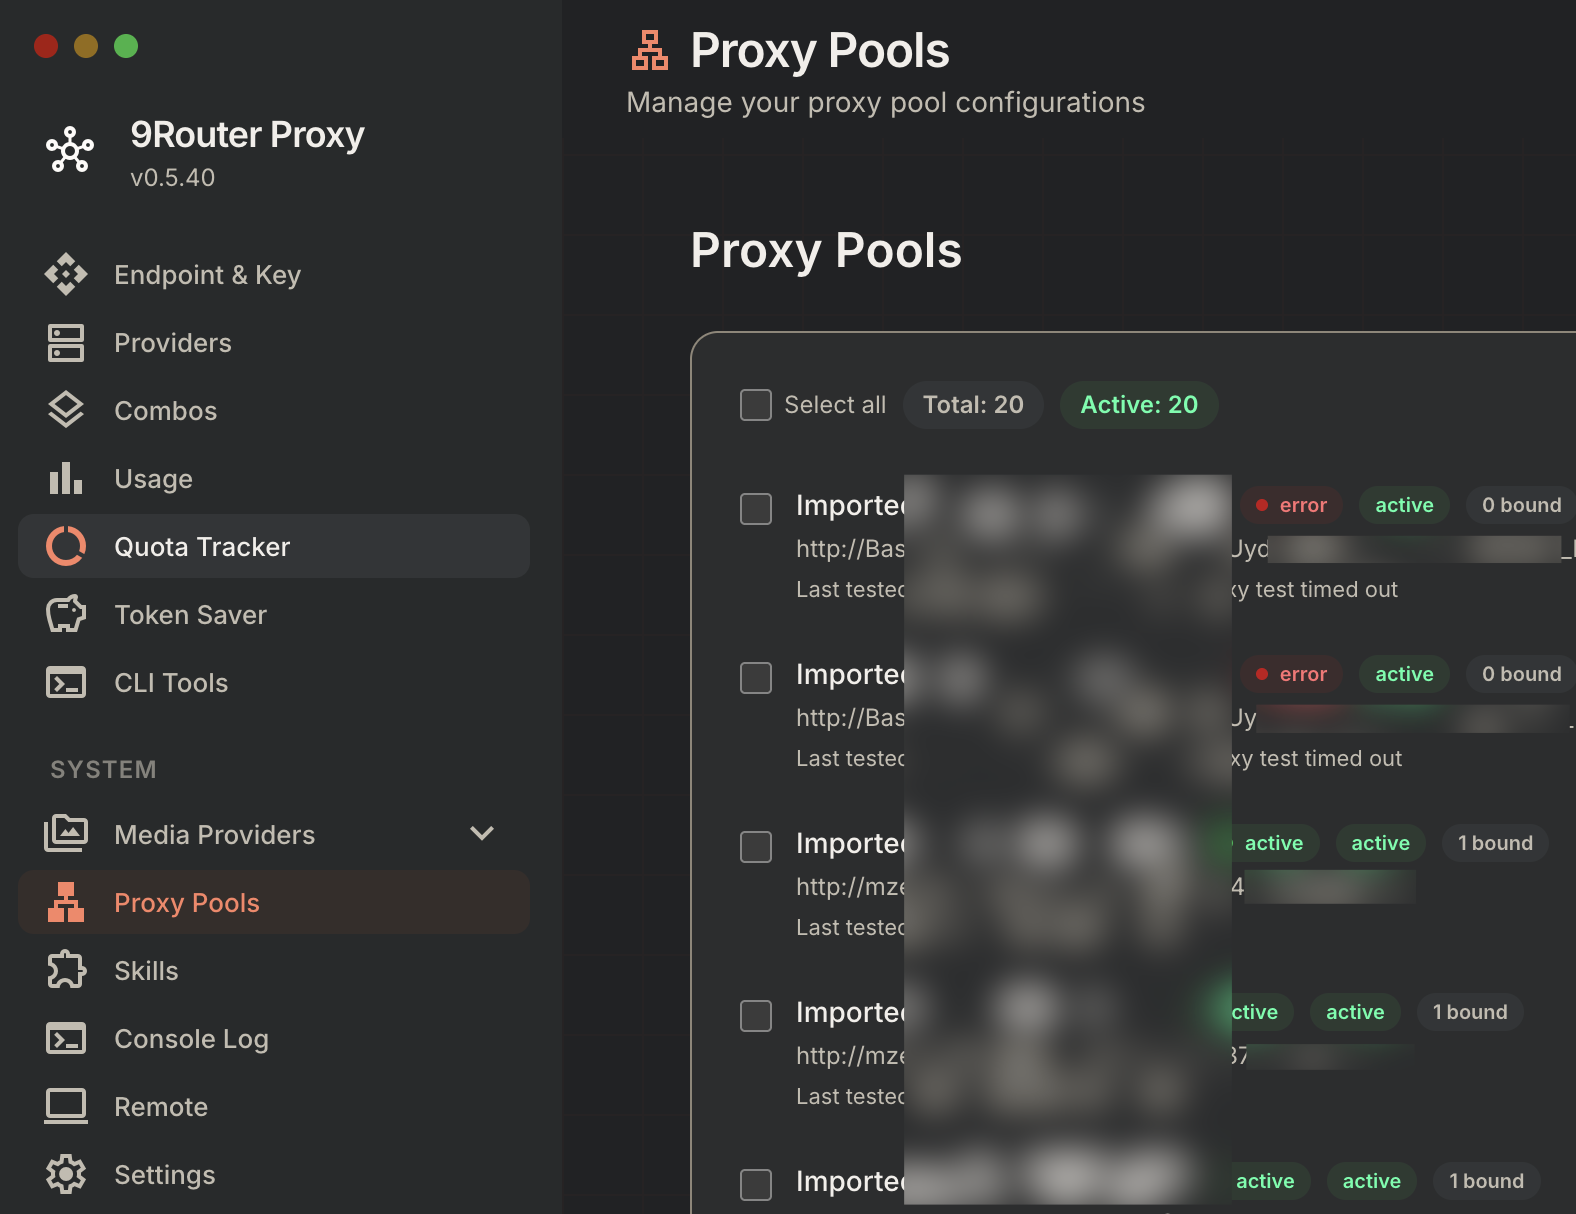
Unlimited grok-4.5 + deepseek-v4-flashLately I've seen tons of relay services offering grok-4.5 as low as 0.1 yuan per 1M tokens. Dug in — the trick is dead simple.At its core it's an account pool polling free grok accounts for their quota. No public number on free grok-4.5 limits, but what I found is ~1M tokens/day. In practice on pi it felt like less.Grok accounts don't currently care about IP, but I'd still route through a proxy pool — one account, one IP, safer. Those same IPs can also poll free models on opencode and mimo code (deepseek-v4-flash, mimo-v2.5-pro).I wired up a 20-IP pool. opencode + mimo code free models easily cover a general agent's daily tasks.For the account/proxy pool tooling, use 9router — it lets you bundle different models into one custom route. E.g. free models from different providers under different names, merged into a single "free" endpoint.Its token-saver is also great: cuts token use across tools, language, and code.9router seems to have a bug. Over public internet it fails constantly; local deploy or Tailscale works rock solid.IPs: webshare. Free tier gives 10 IPs, 1GB/month — more than enough if you budget it.9router: github.com/decolua/9routerFree proxies: webshare.io/?referral_code=pauzhzfueq8v