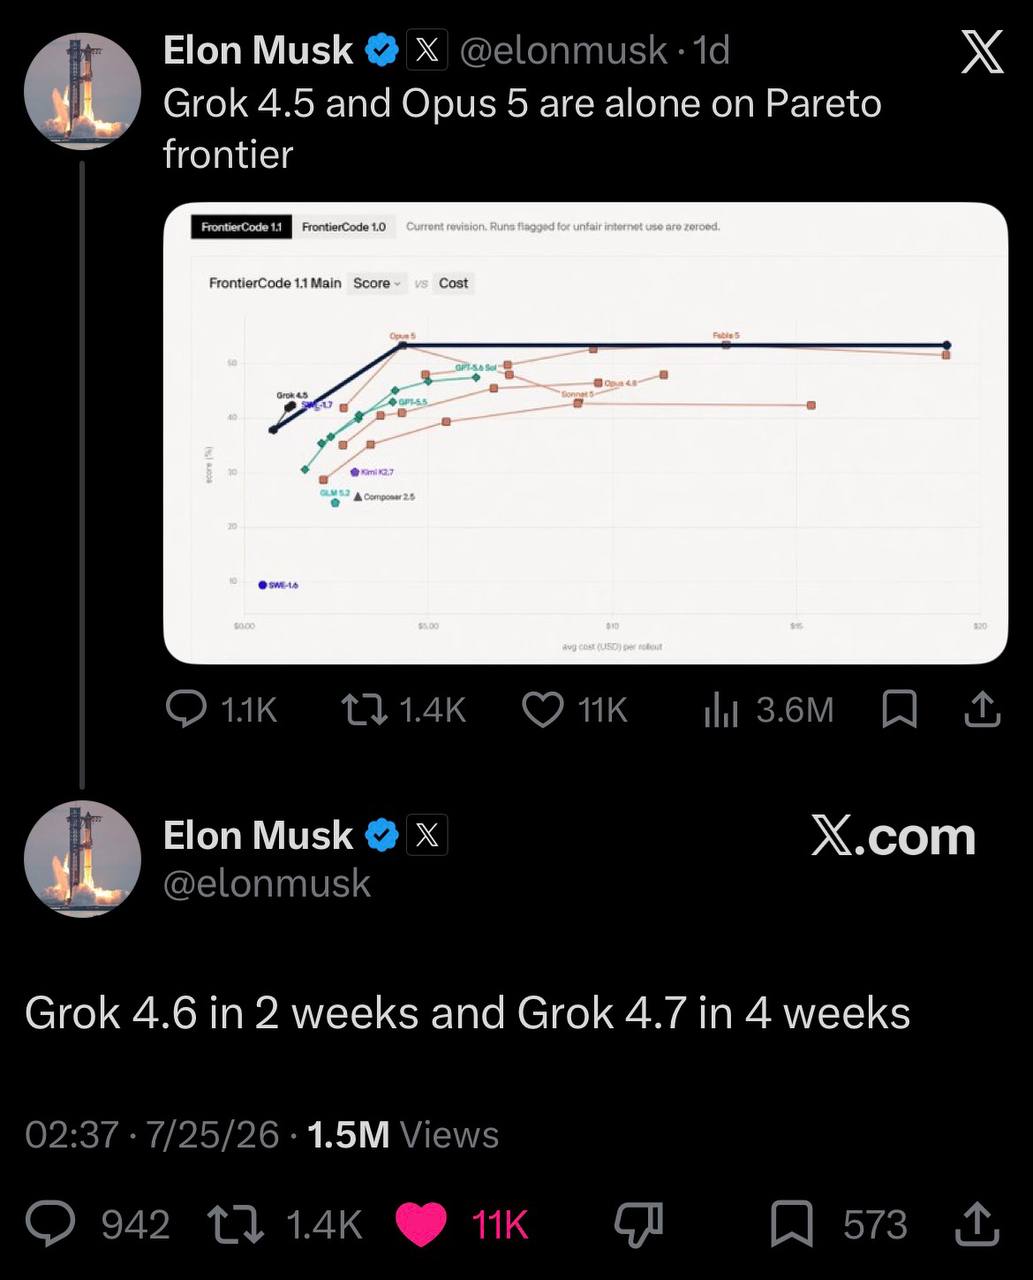
grok-4.6 in 2 weeks, 4.7 in 4. Musk says they're gunning for Kimi K3.
More posts
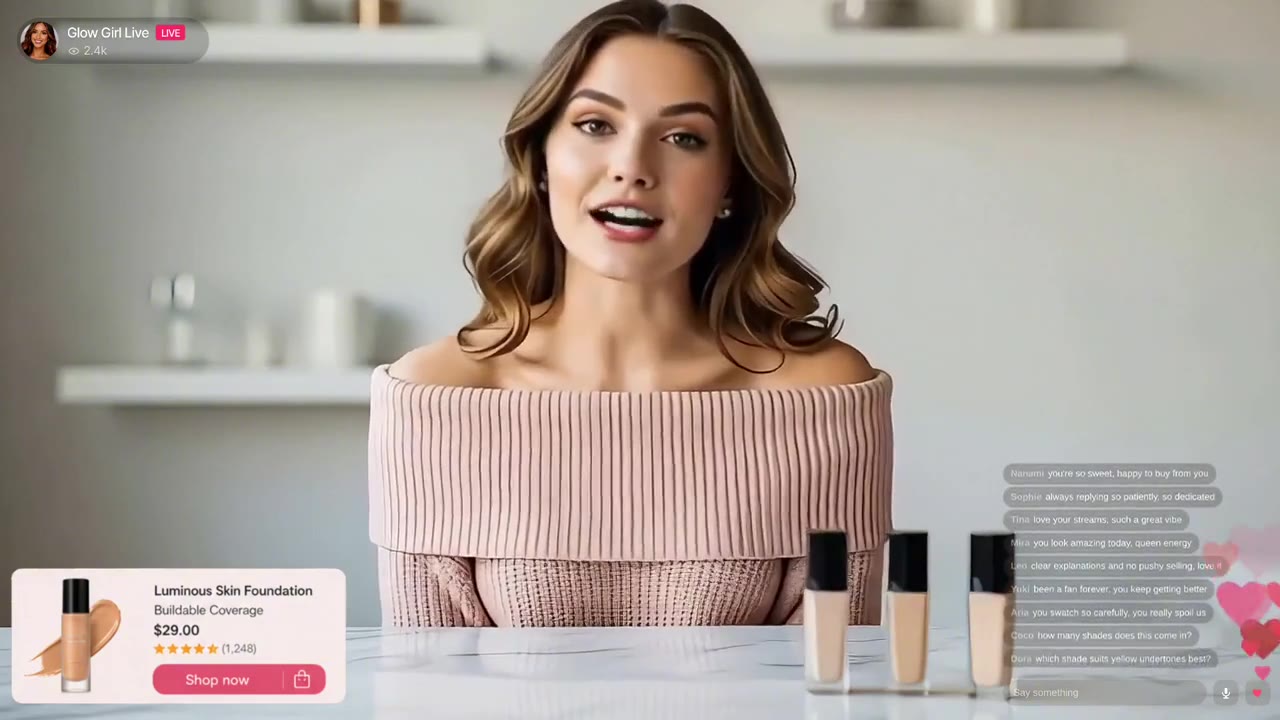
. Full-duplex, full-body digital human. Siri-style turn-taking is half-duplex: you talk, then it talks. A1 runs full-duplex, listening while it replies, talking over you and cutting in like a real person. The full-body part is what got me. This thing walks, turns, crouches to grab objects, holds them up, swaps products mid-demo. First time I've seen that in a digital human. For live commerce it's basically a host that picks up your product, demos it, and changes outfits to match your brand, 24/7, no cuts. They ship a standard API, so you can drop it into anything. Point it at your product and it's a support agent. Drop it in a game and it's a companion. Put it on a stream and it's your host. The use cases pretty much write themselves.
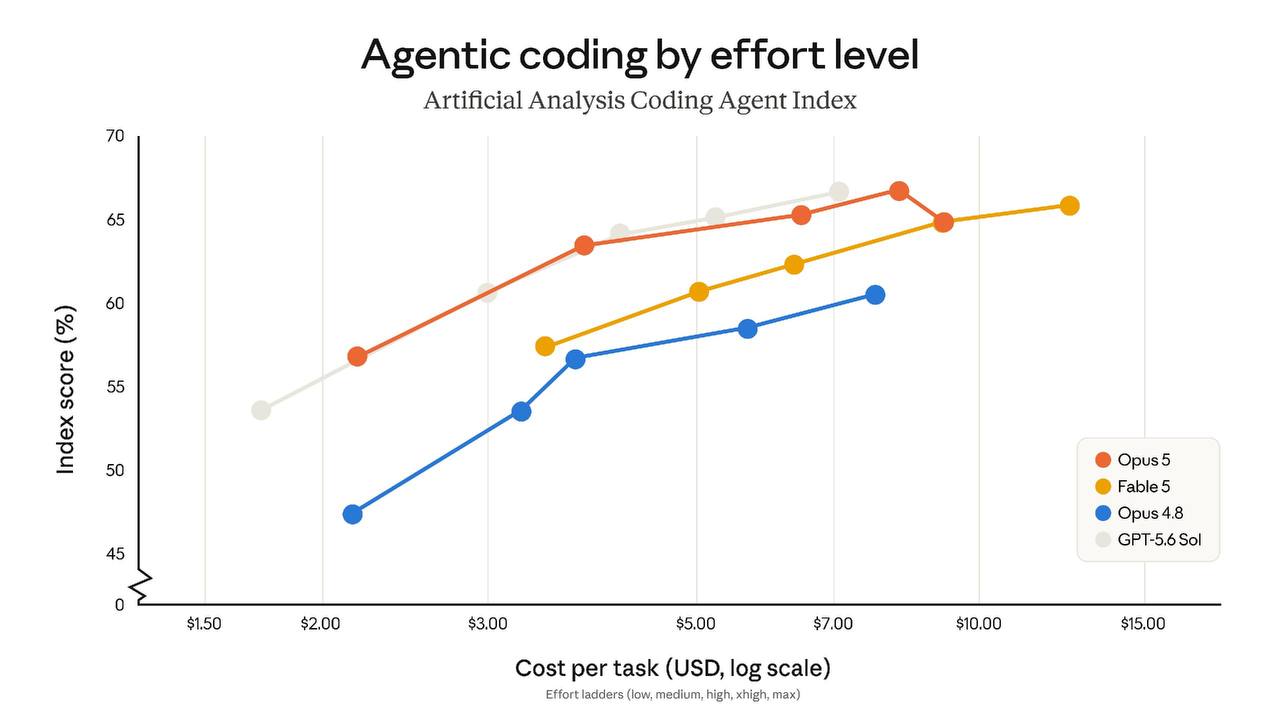
Near-Fable-5 level intelligence at half the price. 43.3% on Frontier-Bench — more than 2x Opus 4.8, and cheaper. On CursorBench (high), it's within 0.5% of Fable 5. And it's getting more AGI by the day — takes initiative like a real person, reflects and verifies its own work. Other models just patch bugs. This one digs out the root cause. For long tasks it takes over your dev environment and runs monitoring itself — only pings you when it genuinely can't decide.
. 1.6T params, ~48B active, native multimodal, aimed at long-horizon agents, trained start to finish on Chinese hardware. Images get quantized into multi-level discrete tokens, and that's where Visual Coding and 3D pick up. On the RL side, failed trajectories get turned back into verifiable training tasks. W4A4 inference, 43% faster prefill. Meituan's own evals put it between Claude Opus 4.8 and Opus 5.

It stacks layers instead of parameters. The decoder has 32 layers, but layers 4 through 27 run twice with shared weights, so a forward pass does 56 layers of work while the checkpoint stays at 9B. Their own eval numbers: 71.38 on BIRD-Dev and 13.72 on AutomationBench, both above Qwen3.5-27B. Terminal Bench is still behind.
