DeepSeek Harness is the best mobile agent setup right now
More posts
agent, server included.
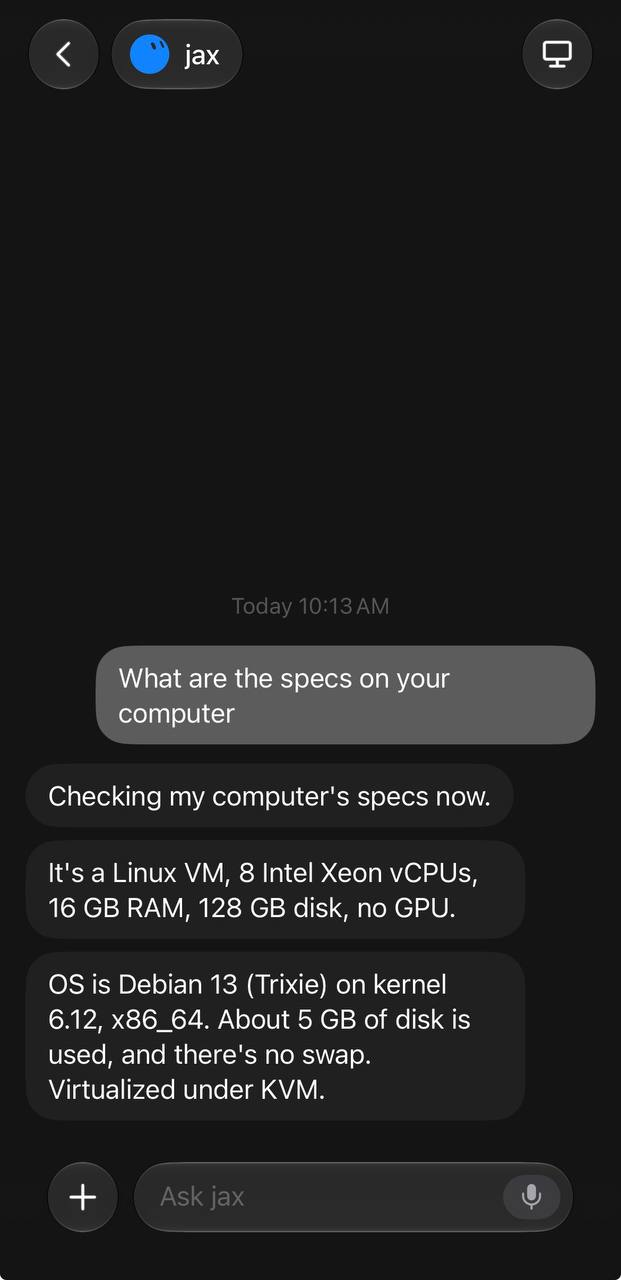
Yesterday Grok bot got pushed down to SuperGrok Plus. Today it dropped again to SuperGrok. So buying SuperGrok gets you Grok bot + a cloud server on top. Asked about the bot's hardware. 16GB RAM. Heavy gets 128GB. Bot quota doesn't seem to share with Build either. Mine hit the weekly cap, but the bot still chats.

DeepSeek hiked prices 12x (that's +1100%) after Aug 16
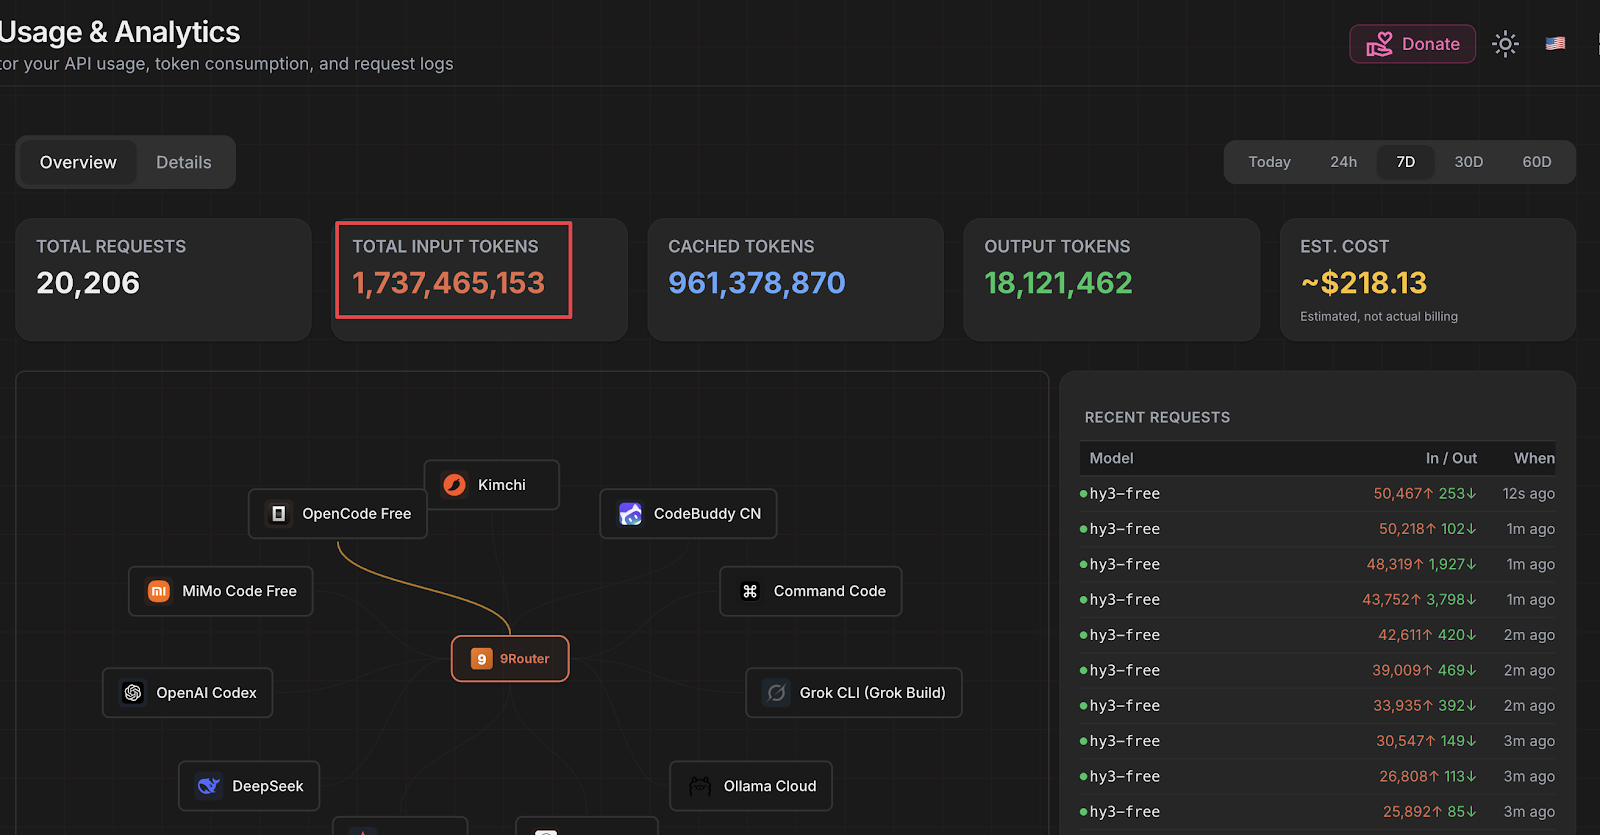
. This past week it cost me over ¥1,000, and ds is still mostly my fallback. I go through a lot of tokens, but across every model I'm pushing 1B+ a week. I'm mostly coding, though this applies elsewhere. Don't run everything through one model. Web lookups and local search go to free or cheap ones. I only pull the top tier for planning, big decisions, and the parts that actually hurt. So at minimum two tiers: a top sub like ChatGPT or Grok, plus a cheap/free model. Hy3 handles the chores. What I run now: ChatGPT + Grok dual sub for the heavy lifting; commandcode's $1 plan to flip between top and cheap on demand; a pool of 50 IPs cycling opencode's hy3-free (each IP gets free daily quota, no login); and workbuddy's daily check-in for points I burn on cheap hy3 calls. It's a stupid amount of plumbing for one week of bills. The ¥1,000 stung enough that I sat down and built it.

Meituan shipped LongCat-2.5
. 1.6T params, ~48B active, native multimodal, aimed at long-horizon agents, trained start to finish on Chinese hardware. Images get quantized into multi-level discrete tokens, and that's where Visual Coding and 3D pick up. On the RL side, failed trajectories get turned back into verifiable training tasks. W4A4 inference, 43% faster prefill. Meituan's own evals put it between Claude Opus 4.8 and Opus 5.

SenseTime open-sourced SenseNova Loop-9B-Preview.
It stacks layers instead of parameters. The decoder has 32 layers, but layers 4 through 27 run twice with shared weights, so a forward pass does 56 layers of work while the checkpoint stays at 9B. Their own eval numbers: 71.38 on BIRD-Dev and 13.72 on AutomationBench, both above Qwen3.5-27B. Terminal Bench is still behind.