OpenAI dropped GPT-6 Astra, their first model trained on an older
More posts
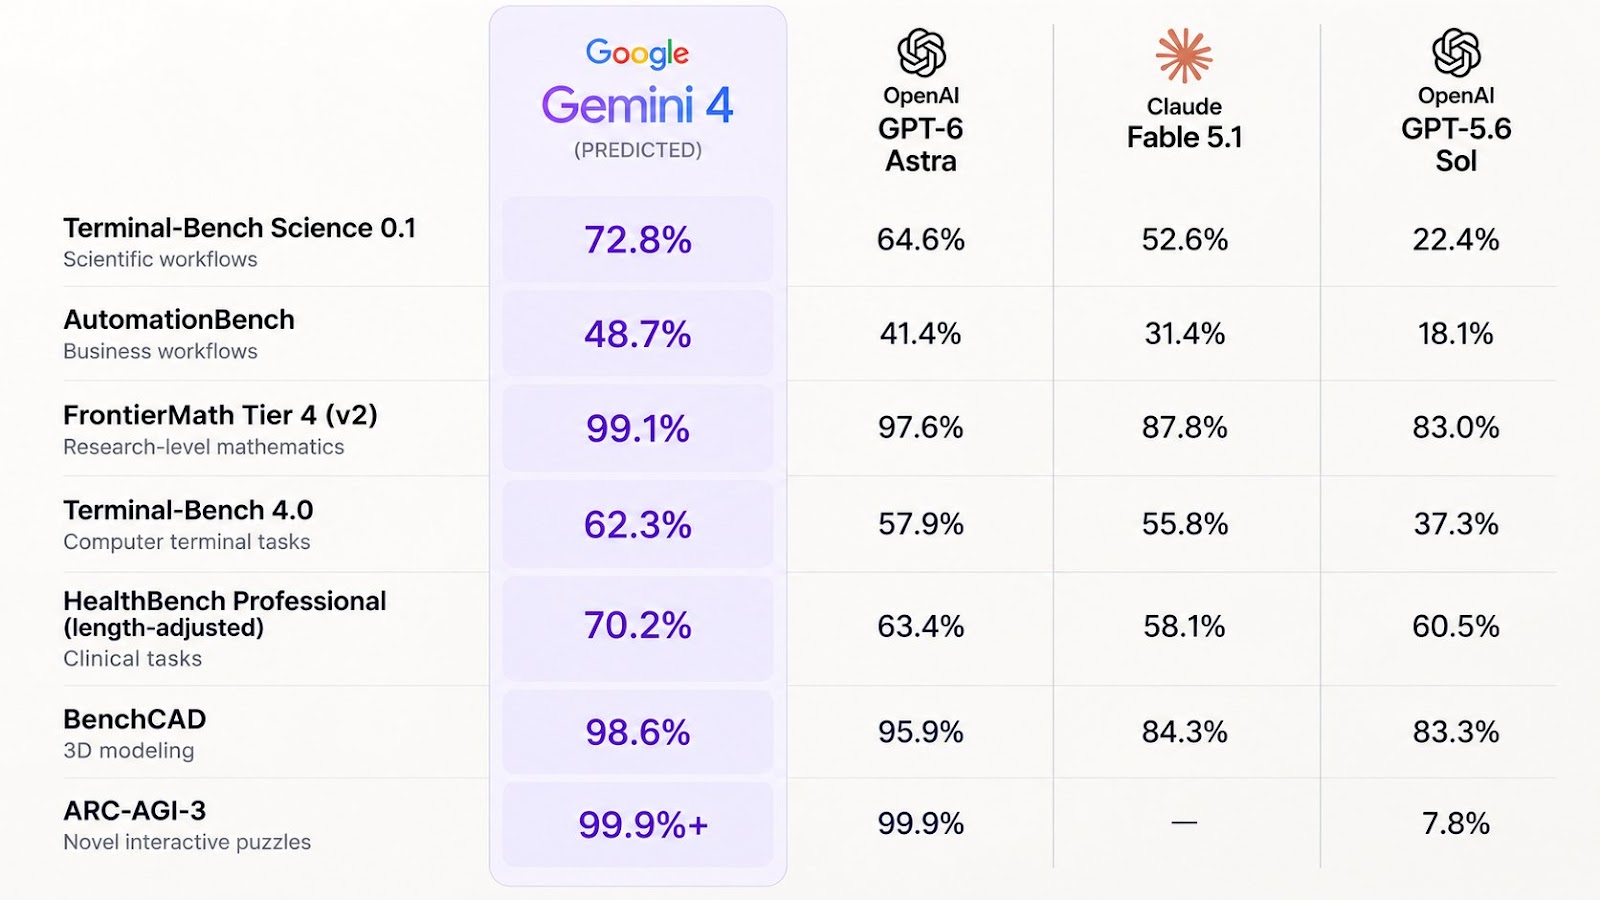
Gemini-4 topping the charts?
Leaked benchmarks are making the rounds and honestly it looks legit. Google's been quiet about 3.0 — rumor is they skip it entirely, go straight to 4.0. If these numbers check out, Gemini-4 just bodied every frontier model on most tests.

Meta Muse Spark 1.3 is out
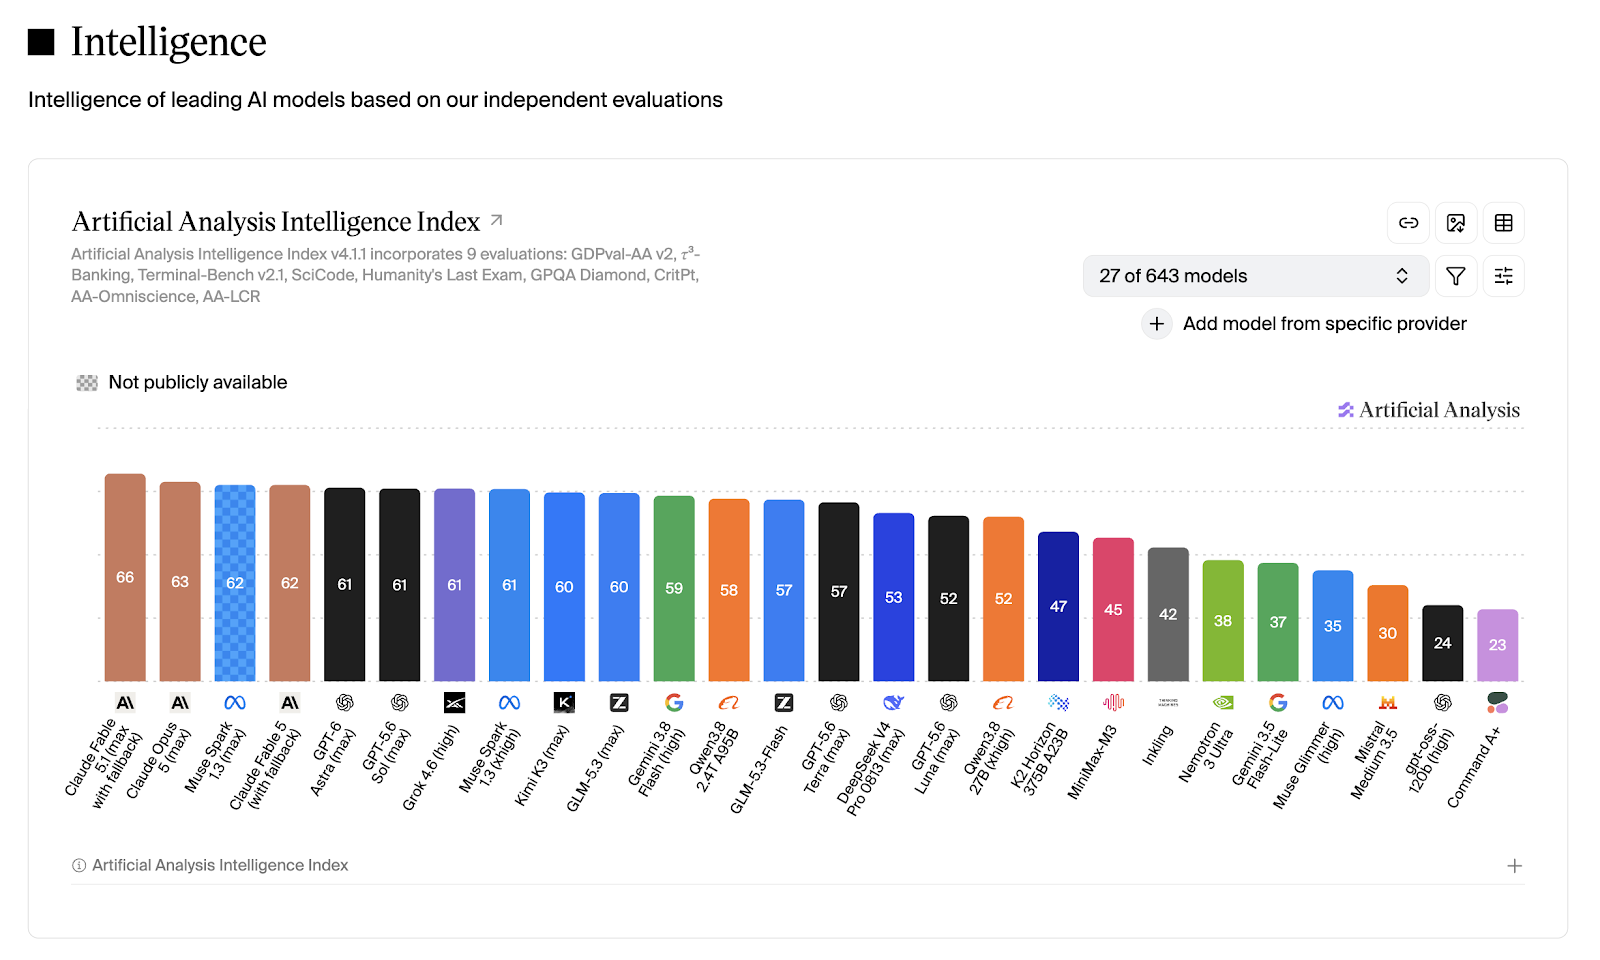
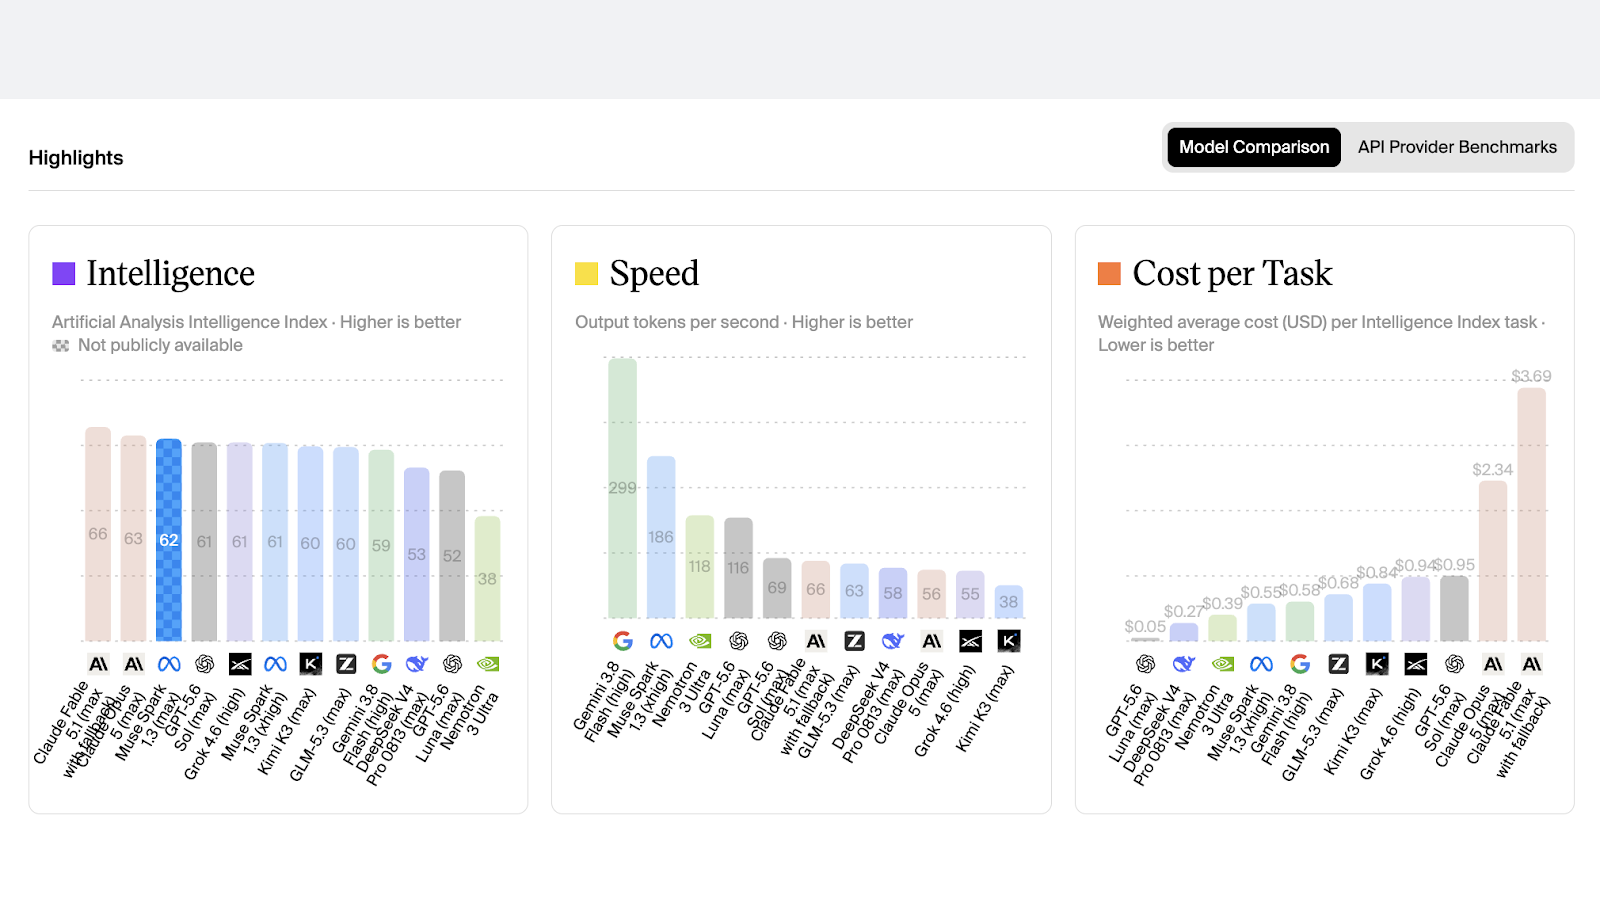
. Matches Claude Opus 5 on intelligence benchmarks. Long-context retrieval (MRCR, 1M window): 98.1, best score I've seen. Coding beats GPT-5.6 Sol, roughly ties Claude Fable 5.1. 25% less tokens per task, 20% fewer tool calls. Contributor pricing: $0.10/M tokens. Cheapest model at this tier right now. Meta's been shipping fast on models lately. I think pushing AI into their own social apps gave them a real feedback loop. Better data, faster cycles.

Meituan shipped LongCat-2.5
. 1.6T params, ~48B active, native multimodal, aimed at long-horizon agents, trained start to finish on Chinese hardware. Images get quantized into multi-level discrete tokens, and that's where Visual Coding and 3D pick up. On the RL side, failed trajectories get turned back into verifiable training tasks. W4A4 inference, 43% faster prefill. Meituan's own evals put it between Claude Opus 4.8 and Opus 5.

SenseTime open-sourced SenseNova Loop-9B-Preview.
It stacks layers instead of parameters. The decoder has 32 layers, but layers 4 through 27 run twice with shared weights, so a forward pass does 56 layers of work while the checkpoint stays at 9B. Their own eval numbers: 71.38 on BIRD-Dev and 13.72 on AutomationBench, both above Qwen3.5-27B. Terminal Bench is still behind.