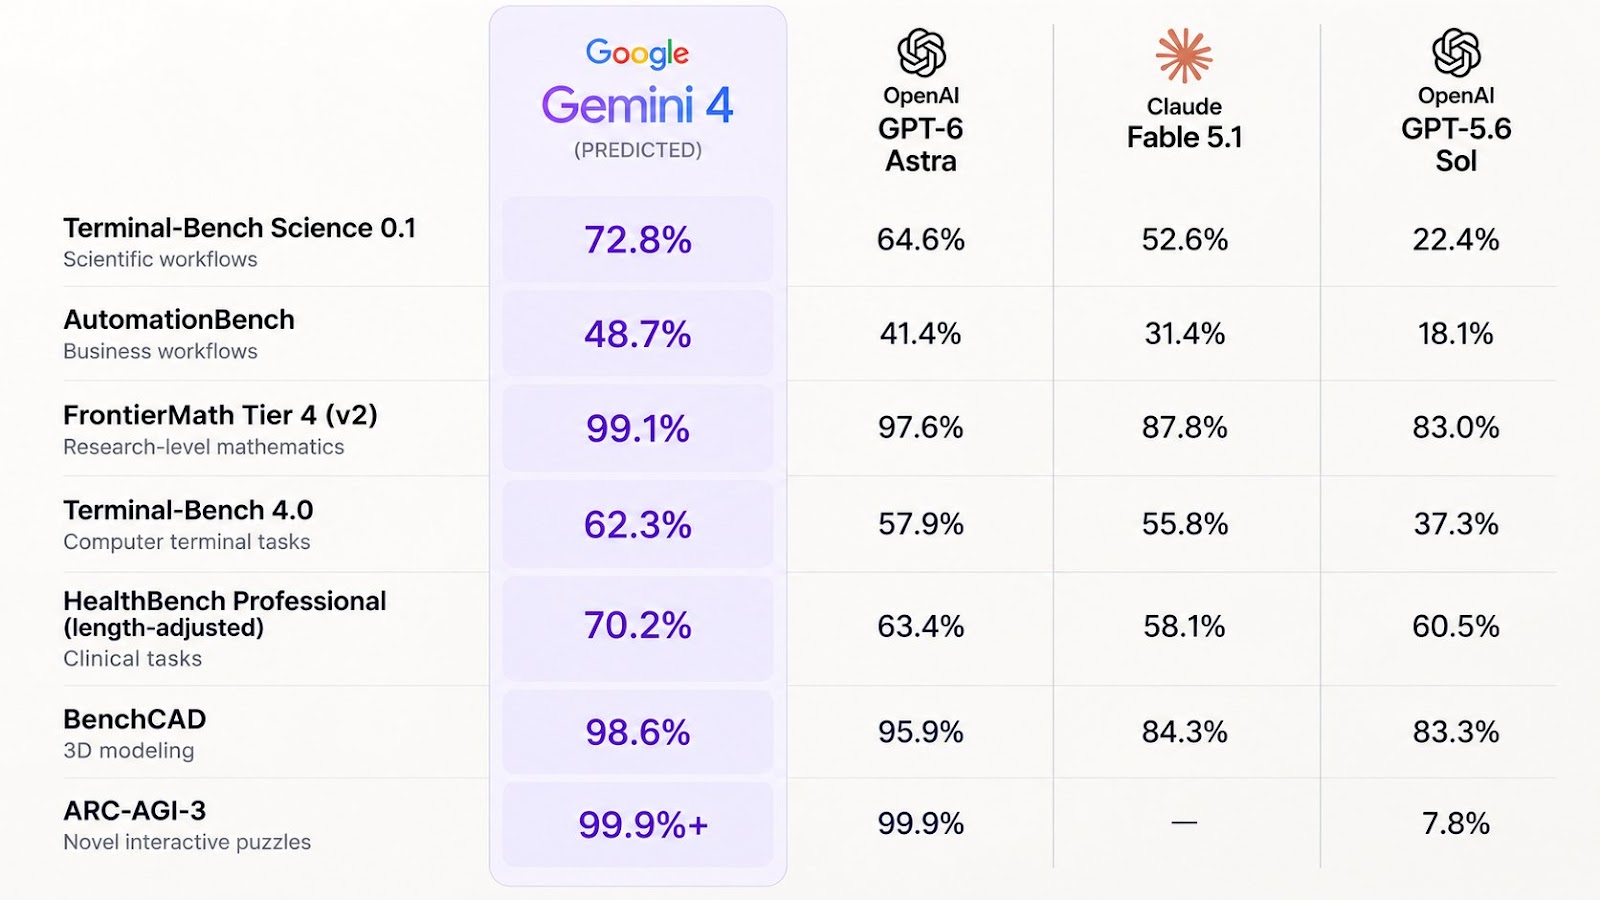
Gemini-4 topping the charts?
More posts
Grok-bot’s box is one of those things that’s barely worth using
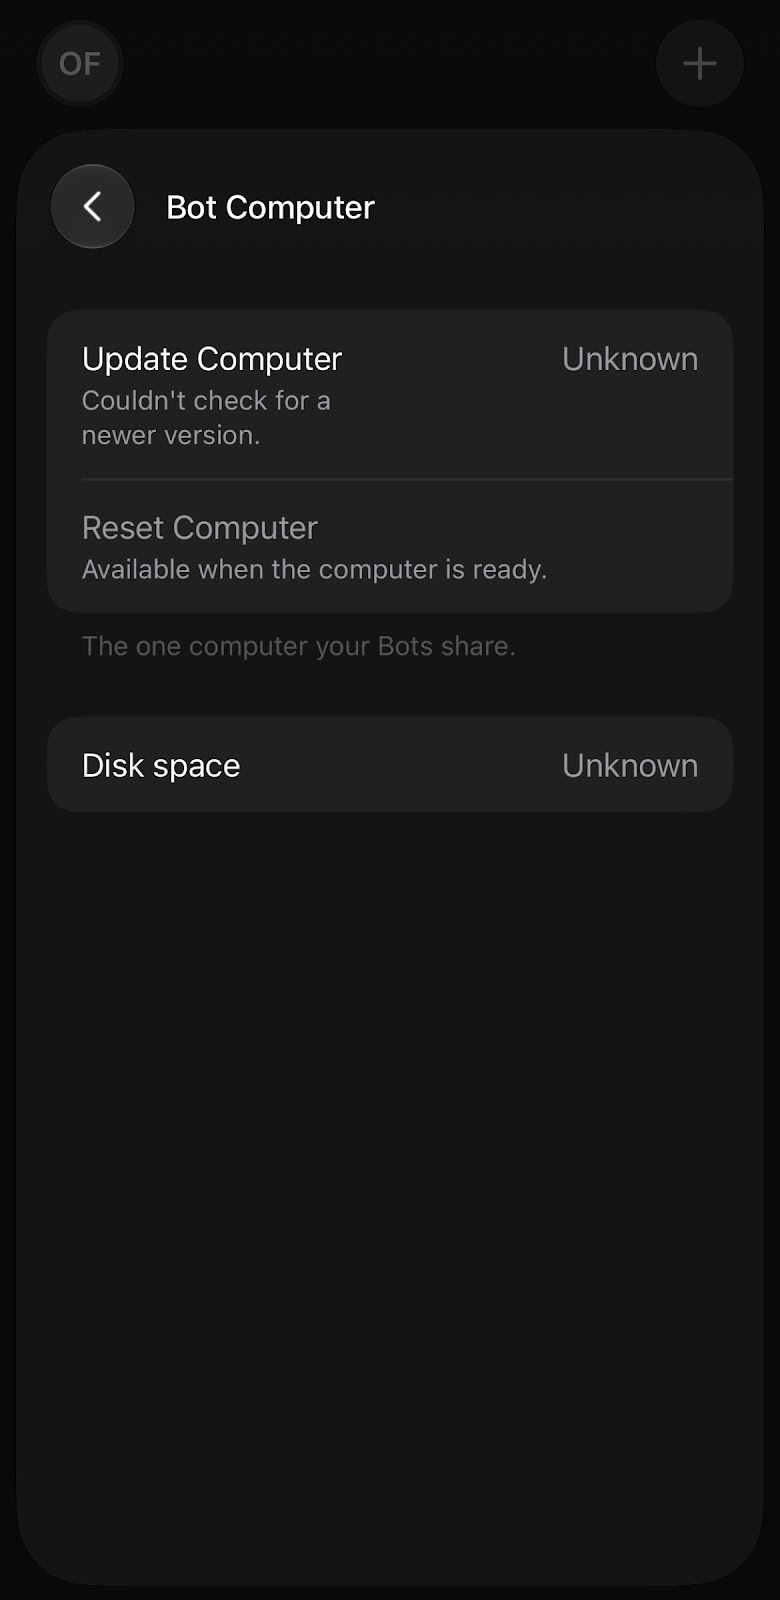
, but you still don’t throw it away.It’s an 8-core / 16+128G machine, except it isn’t a real Linux server. It’s just a Docker container. No systemd, no daemons, no auto-restart, no boot-on-start, no public IP. Every so often a grok-bot update spins up a new instance. Stuff in home survives the update. Running processes don’t. You have to get the bot to bring them back up. So if you actually want to use the machine, grok-bot has to keep it alive. My setup: install Hermes, write a watchdog that relaunches Hermes every minute, then tell grok-bot to kick the watchdog every five minutes. New instance lands → grok-bot starts the script → script starts Hermes → Hermes starts everything else. It’s holding for now. Two problems though. One: grok-bot only pokes it every five minutes. Weekly quota hit 60% in two days. Quota just reset today, otherwise the base plan isn’t enough. Two: the box is flaky. Anything a bit heavy and it dies. Grok-bot goes silent too. Only fix is restore the machine in settings.

OpenAI dropped GPT-6 Astra, their first model trained on an older
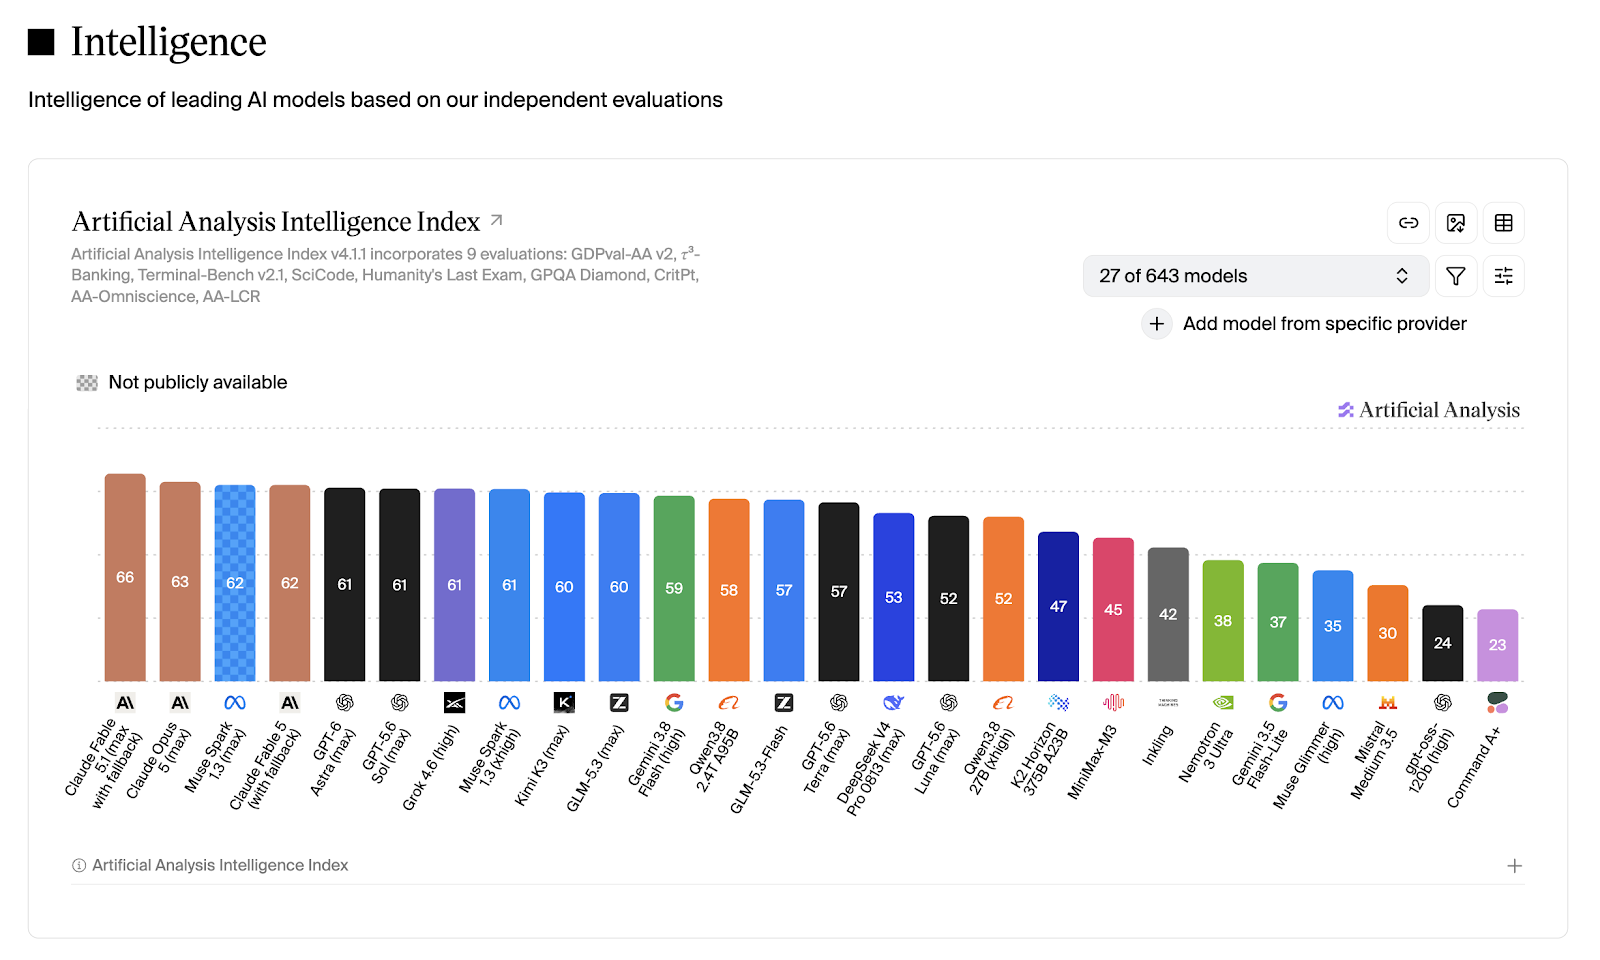
model's output. Intelligence score matches GPT-5.6-Sol at 61. Where it shines: computer use and cybersecurity. $10/M input, $50/M output — 2.5x Sol. But it finishes tasks faster and eats fewer tokens.

Meituan shipped LongCat-2.5
. 1.6T params, ~48B active, native multimodal, aimed at long-horizon agents, trained start to finish on Chinese hardware. Images get quantized into multi-level discrete tokens, and that's where Visual Coding and 3D pick up. On the RL side, failed trajectories get turned back into verifiable training tasks. W4A4 inference, 43% faster prefill. Meituan's own evals put it between Claude Opus 4.8 and Opus 5.

SenseTime open-sourced SenseNova Loop-9B-Preview.
It stacks layers instead of parameters. The decoder has 32 layers, but layers 4 through 27 run twice with shared weights, so a forward pass does 56 layers of work while the checkpoint stays at 9B. Their own eval numbers: 71.38 on BIRD-Dev and 13.72 on AutomationBench, both above Qwen3.5-27B. Terminal Bench is still behind.