opencode's free tier got cut off from external calls
More posts
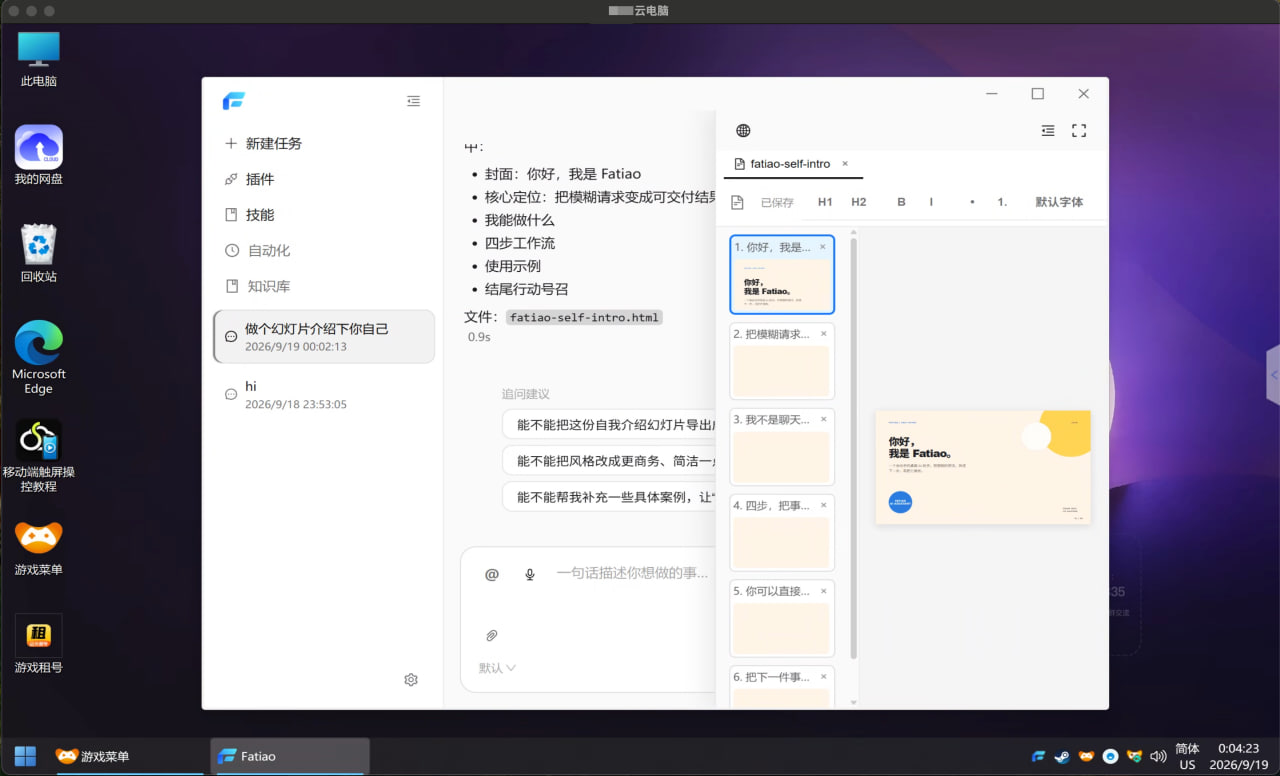
Cloud PCs are a solid way to test stuff.
All I have is a MacBook, and my product is a Windows app. Before this, testing meant either an ARM Windows VM or an hour at an internet cafe with an x86 machine. Cloud PCs are mature enough now that it doesn't matter, and they're cheap. Roughly 1-2 RMB an hour, which makes them handy for testing or remote dev.

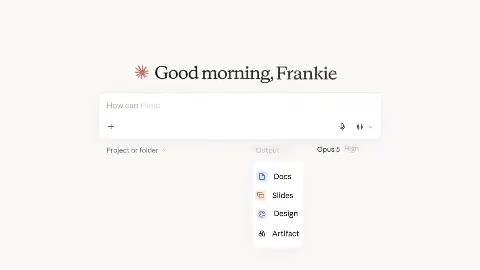
Claude just did the same with Chat and Cowork
ChatGPT merged Chat and Codex into one entry point. Claude just did the same with Chat and Cowork. So you don't have to think about whether you want a chat or a task anymore. Describe what you need in the chat and the agent works it out on its own, whether that means running something long, calling tools, or handing you the finished thing. Claude Docs is out too, for writing documents together. Multiple people can work on them, and you can export to Word, PDF, or Google Docs. Then there's Claude Slides, which generates decks you can edit and present, and it exports to PPT.
Meituan shipped LongCat-2.5
. 1.6T params, ~48B active, native multimodal, aimed at long-horizon agents, trained start to finish on Chinese hardware. Images get quantized into multi-level discrete tokens, and that's where Visual Coding and 3D pick up. On the RL side, failed trajectories get turned back into verifiable training tasks. W4A4 inference, 43% faster prefill. Meituan's own evals put it between Claude Opus 4.8 and Opus 5.

SenseTime open-sourced SenseNova Loop-9B-Preview.
It stacks layers instead of parameters. The decoder has 32 layers, but layers 4 through 27 run twice with shared weights, so a forward pass does 56 layers of work while the checkpoint stays at 9B. Their own eval numbers: 71.38 on BIRD-Dev and 13.72 on AutomationBench, both above Qwen3.5-27B. Terminal Bench is still behind.