Cloud PCs are a solid way to test stuff.
More posts
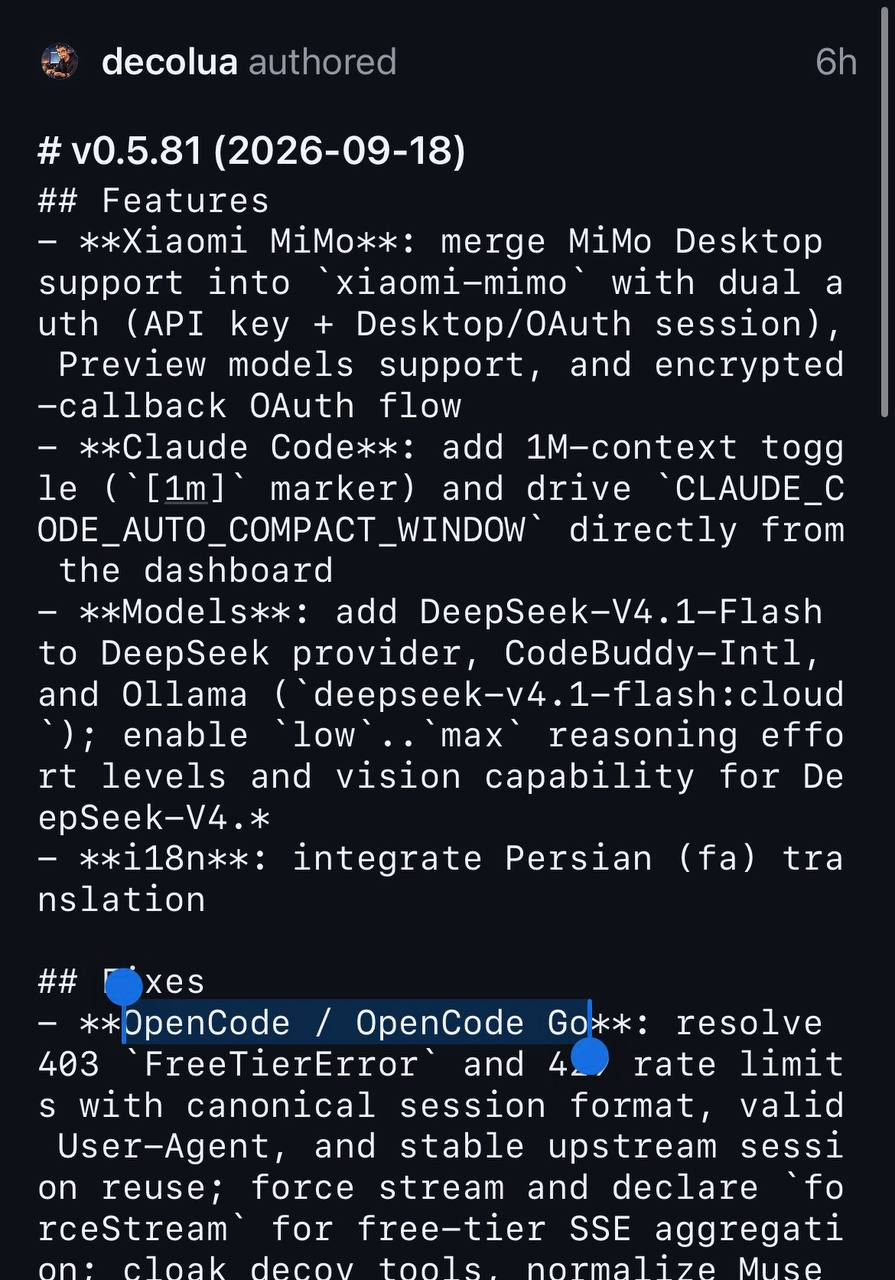
Speed wins. The free models in opencode are working again.
Someone actually had it fixed the same night and opened a PR. Then the 9router author pushed an update. No clue whether he merged the PR or rewrote it by hand, but opencode free works fine on the new version. OpenCode's free models only talk to their official client now. 9router's fix is fingerprint spoofing.

opencode's free tier got cut off from external calls
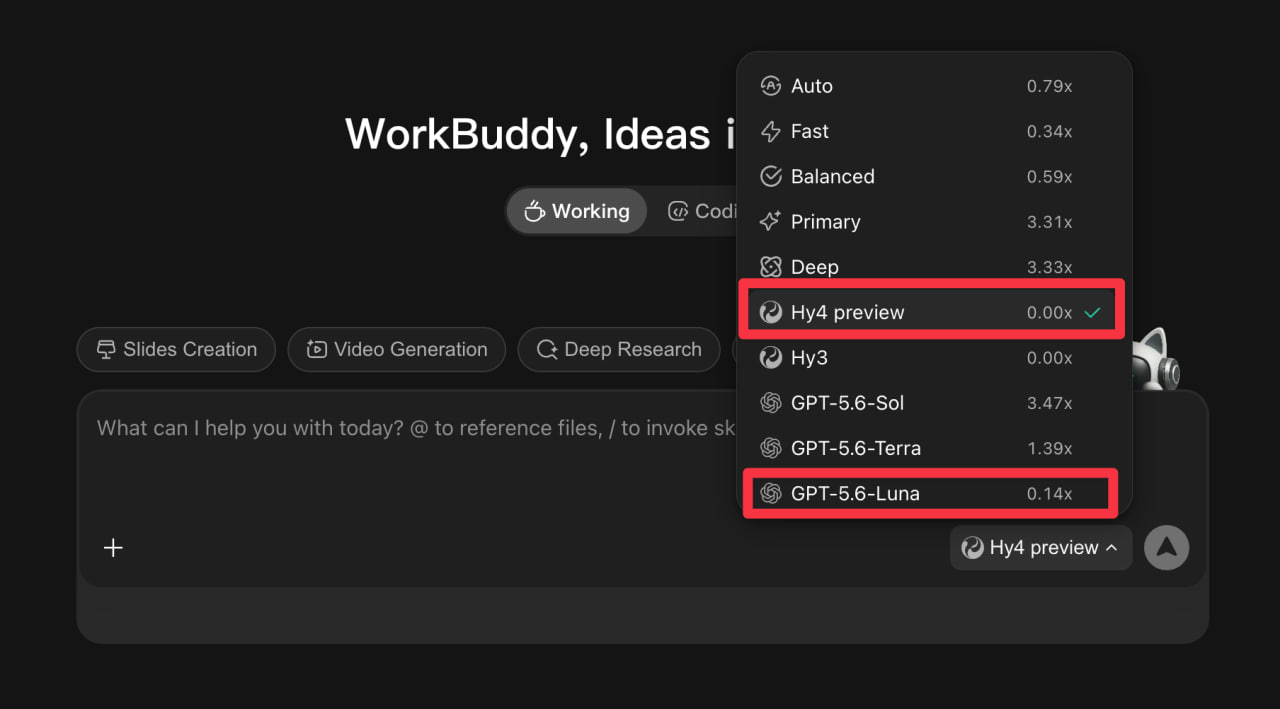
So opencode's free tier got cut off from external calls. That's a bigger problem than it sounds, because a lot of open source stuff had opencode free wired in as a backend, Hermes agent being one of the popular ones. Not just the reverse proxy people grumbling about it either. Plenty of agent users are in the same boat. I read through what everyone's doing about it. The no-auth free models are all dead. What people say actually works: make a bunch of international workbuddy accounts with alias emails and rotate them through an IP pool to keep pulling from the free hy-4 model. Or just pay for the cheap gpt-5.6-luna. 100 credits per account per month, 30 of them refunded every day, so if your IP pool is big enough you'll never burn through them.

Meituan shipped LongCat-2.5
. 1.6T params, ~48B active, native multimodal, aimed at long-horizon agents, trained start to finish on Chinese hardware. Images get quantized into multi-level discrete tokens, and that's where Visual Coding and 3D pick up. On the RL side, failed trajectories get turned back into verifiable training tasks. W4A4 inference, 43% faster prefill. Meituan's own evals put it between Claude Opus 4.8 and Opus 5.

SenseTime open-sourced SenseNova Loop-9B-Preview.
It stacks layers instead of parameters. The decoder has 32 layers, but layers 4 through 27 run twice with shared weights, so a forward pass does 56 layers of work while the checkpoint stays at 9B. Their own eval numbers: 71.38 on BIRD-Dev and 13.72 on AutomationBench, both above Qwen3.5-27B. Terminal Bench is still behind.