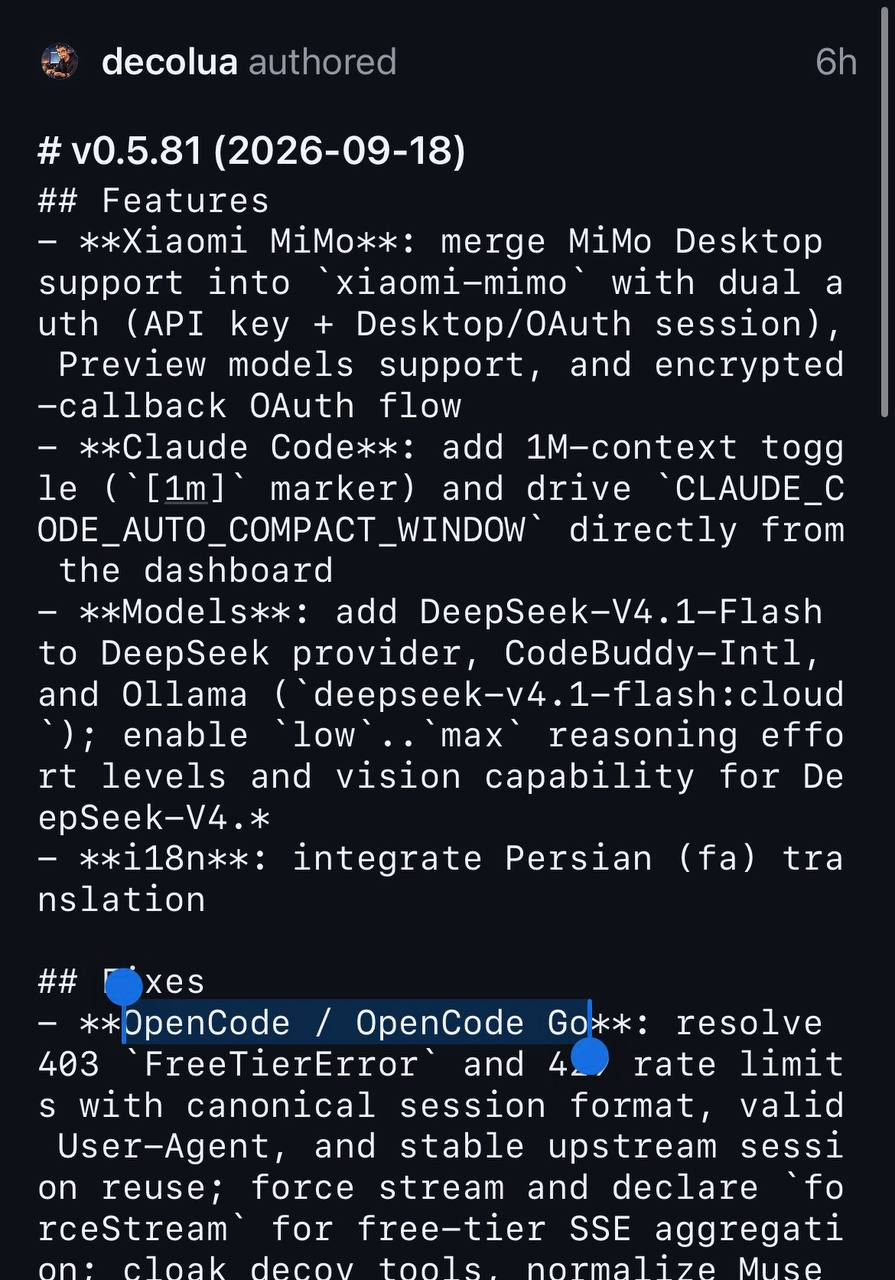
Speed wins. The free models in opencode are working again.
More posts
September's hottest model is one that doesn't speak.
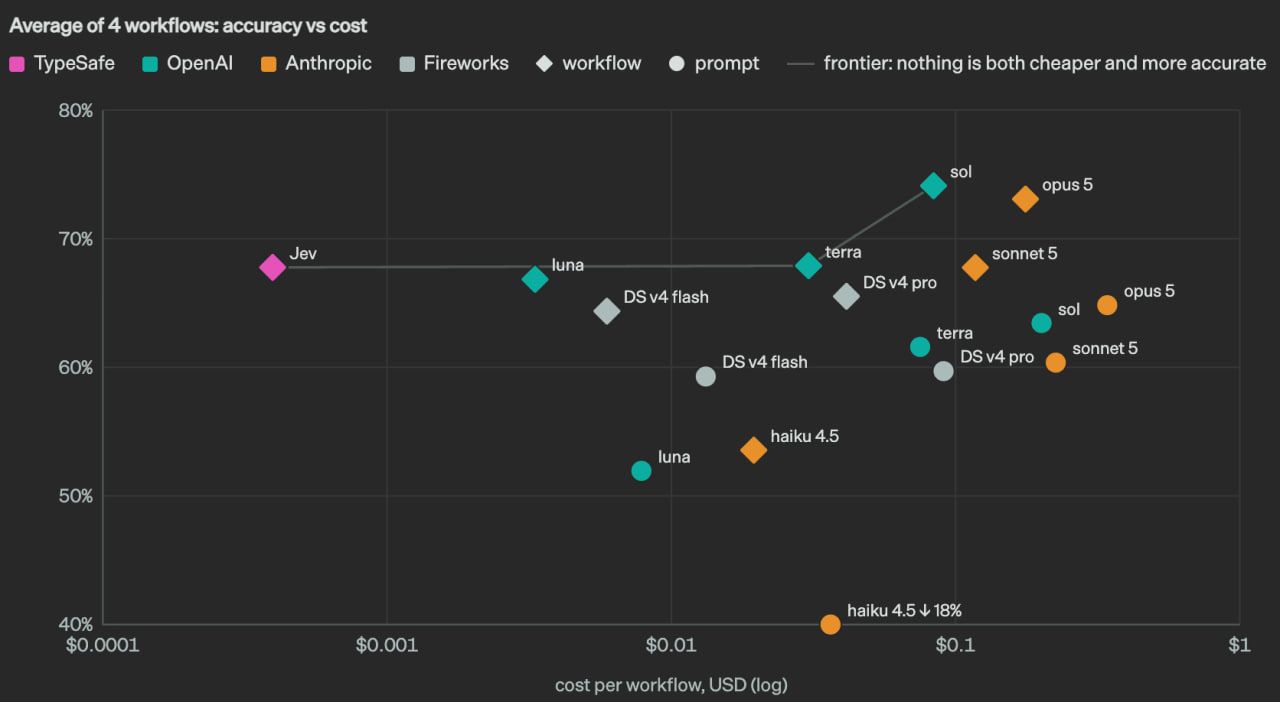
I keep running into Jev. It's basically the agent version of if. Jev doesn't chat with you, it makes calls. Feed it a support ticket and ask who should take it. Give it the options, billing, technical, sales. It doesn't explain, doesn't ramble. Just the answer and how sure it is: technical, 85%. Which is why it's good at intent stuff. Computer use, support triage, spam comments, picking a model for a given task, sanity-checking what another model wrote. Fast and cheap. What it can't do: explain its reasoning (there isn't any), write prose (it doesn't write), and if none of the options is right it'll still pick one. It's whitelist-only right now. If you want in early, it's on OpenRouter. https://typesafe.ai

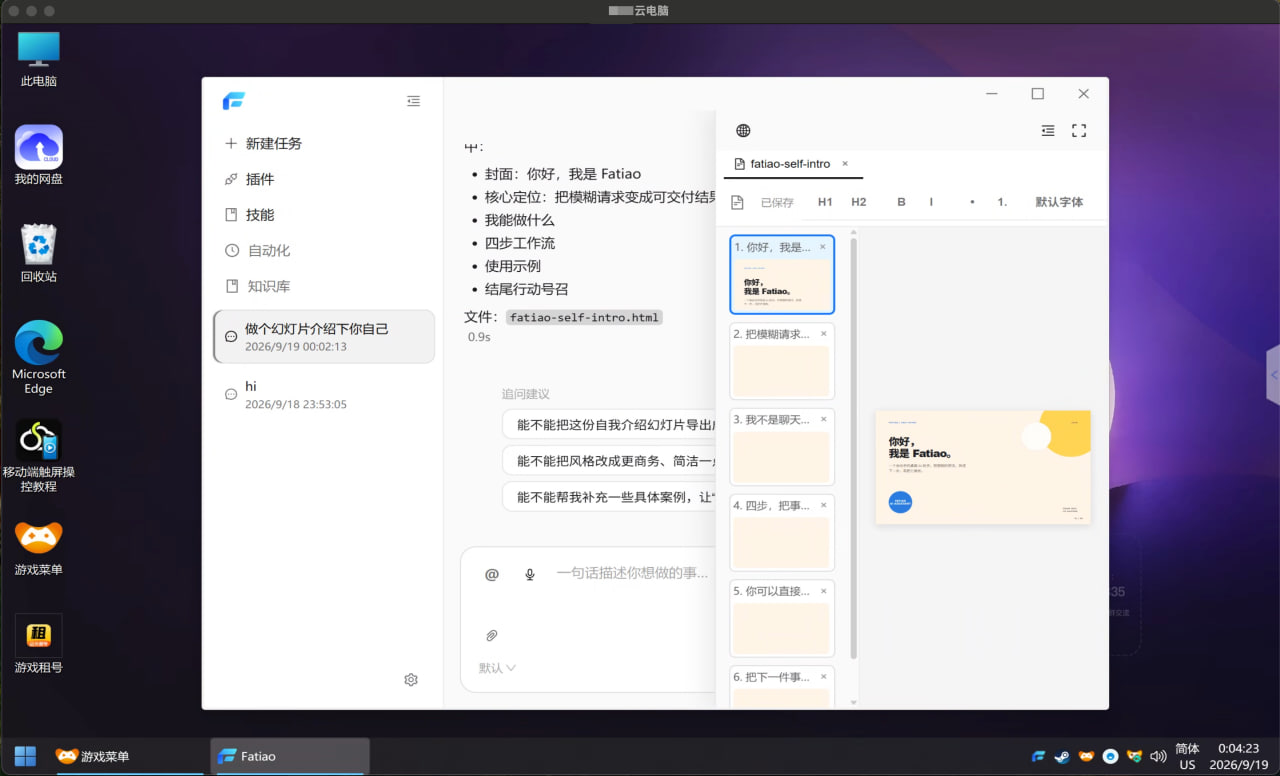
Cloud PCs are a solid way to test stuff.
All I have is a MacBook, and my product is a Windows app. Before this, testing meant either an ARM Windows VM or an hour at an internet cafe with an x86 machine. Cloud PCs are mature enough now that it doesn't matter, and they're cheap. Roughly 1-2 RMB an hour, which makes them handy for testing or remote dev.

Meituan shipped LongCat-2.5
. 1.6T params, ~48B active, native multimodal, aimed at long-horizon agents, trained start to finish on Chinese hardware. Images get quantized into multi-level discrete tokens, and that's where Visual Coding and 3D pick up. On the RL side, failed trajectories get turned back into verifiable training tasks. W4A4 inference, 43% faster prefill. Meituan's own evals put it between Claude Opus 4.8 and Opus 5.

SenseTime open-sourced SenseNova Loop-9B-Preview.
It stacks layers instead of parameters. The decoder has 32 layers, but layers 4 through 27 run twice with shared weights, so a forward pass does 56 layers of work while the checkpoint stays at 9B. Their own eval numbers: 71.38 on BIRD-Dev and 13.72 on AutomationBench, both above Qwen3.5-27B. Terminal Bench is still behind.