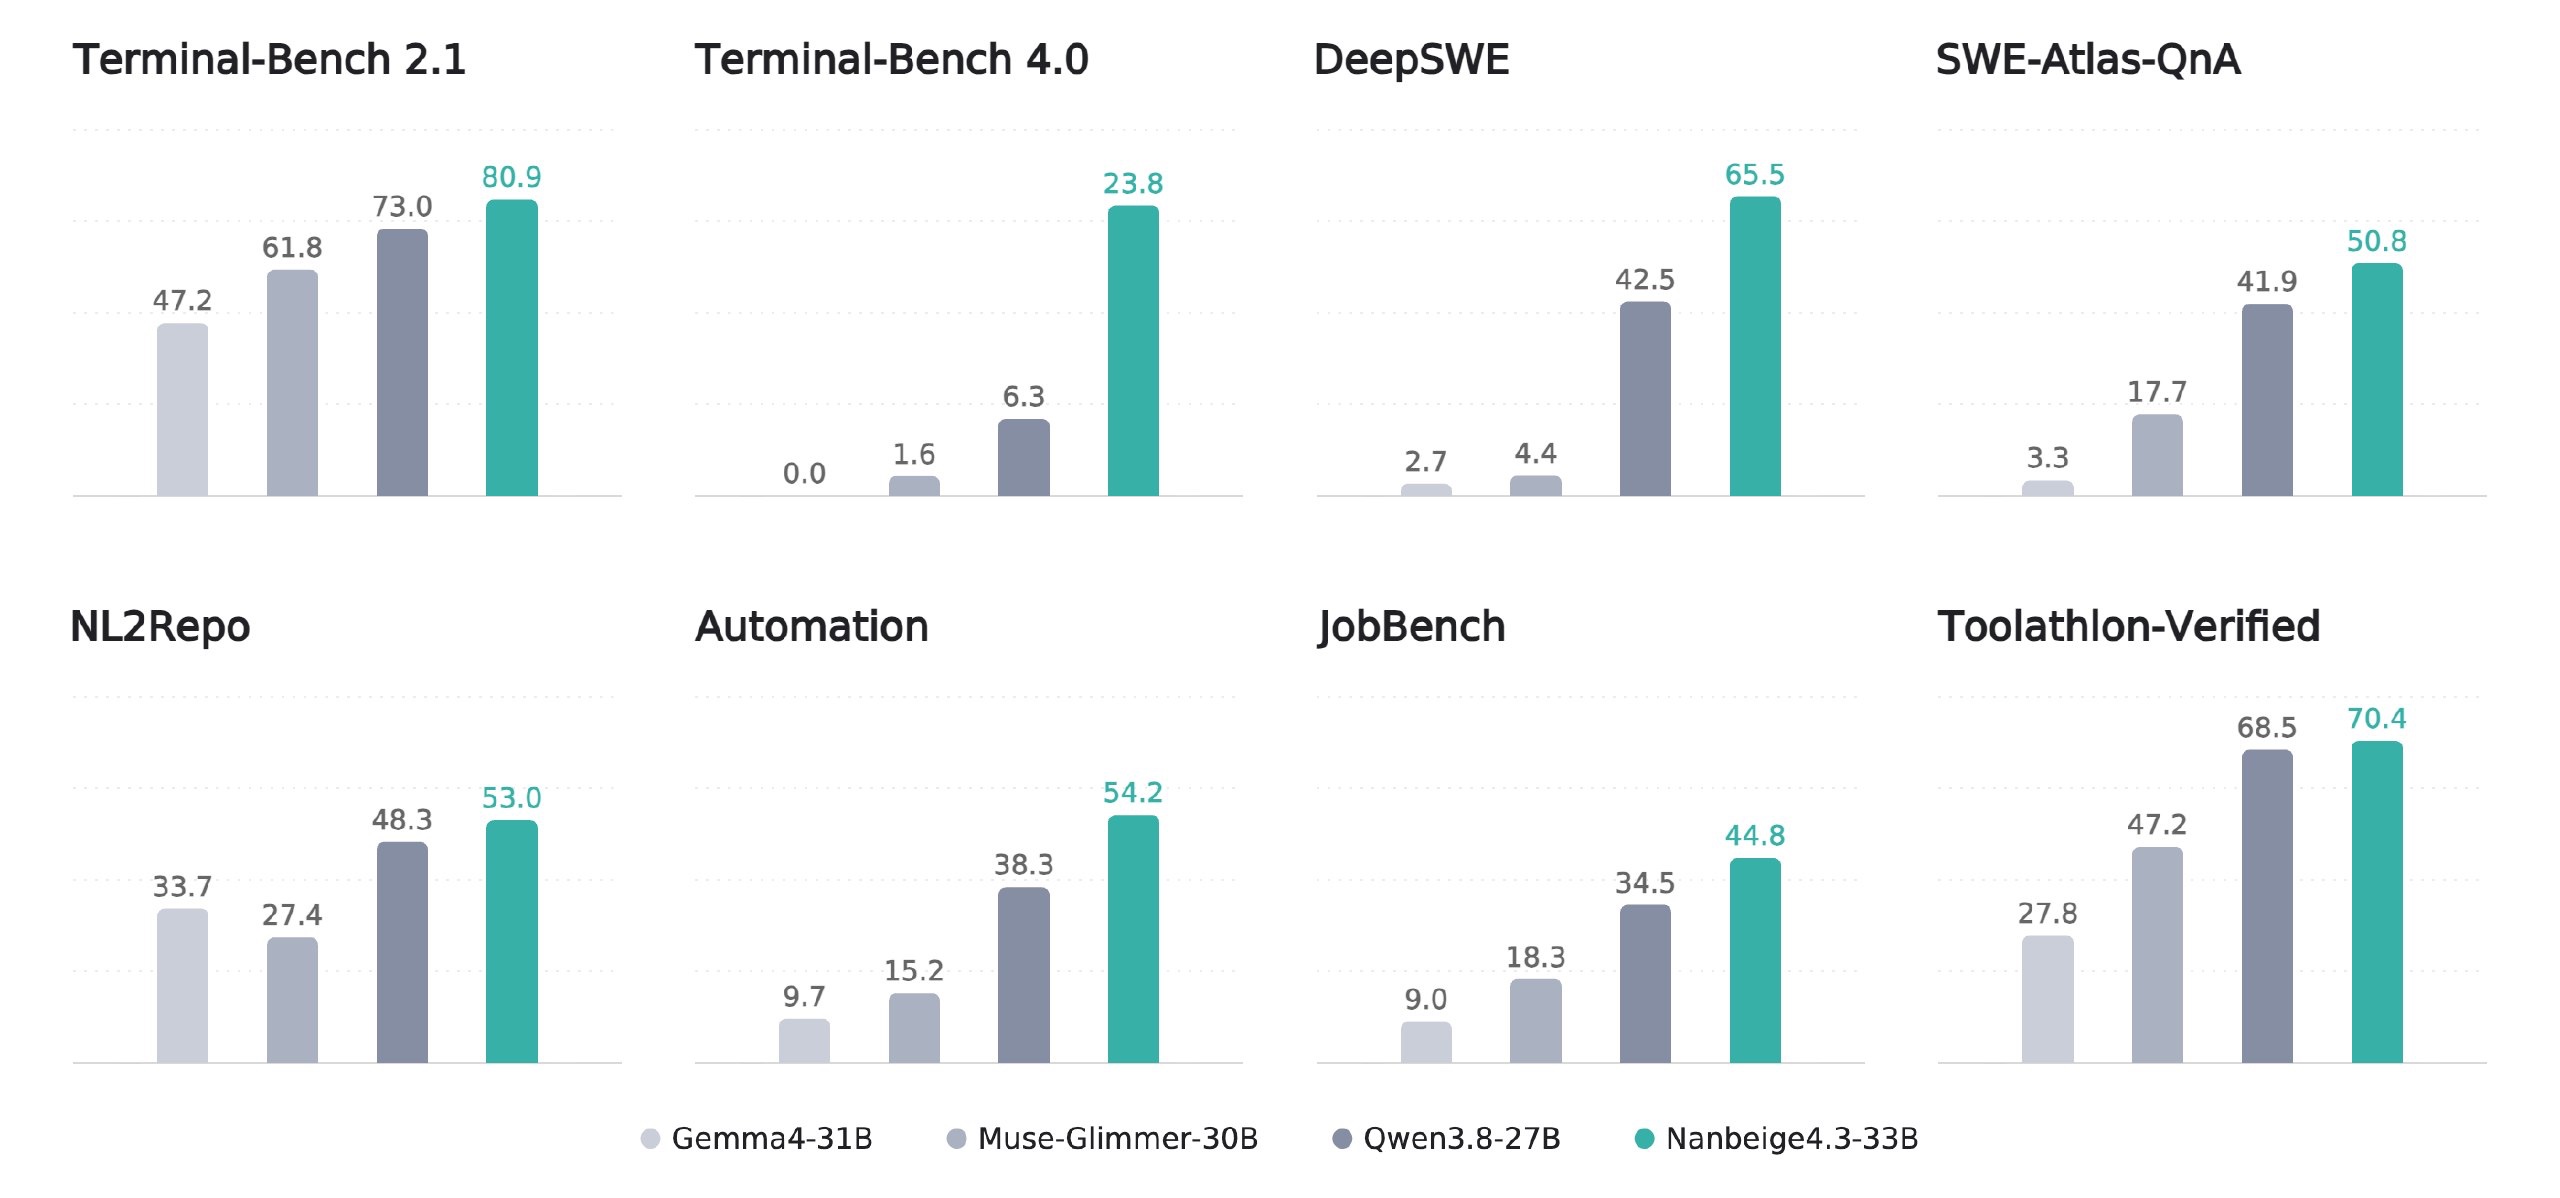
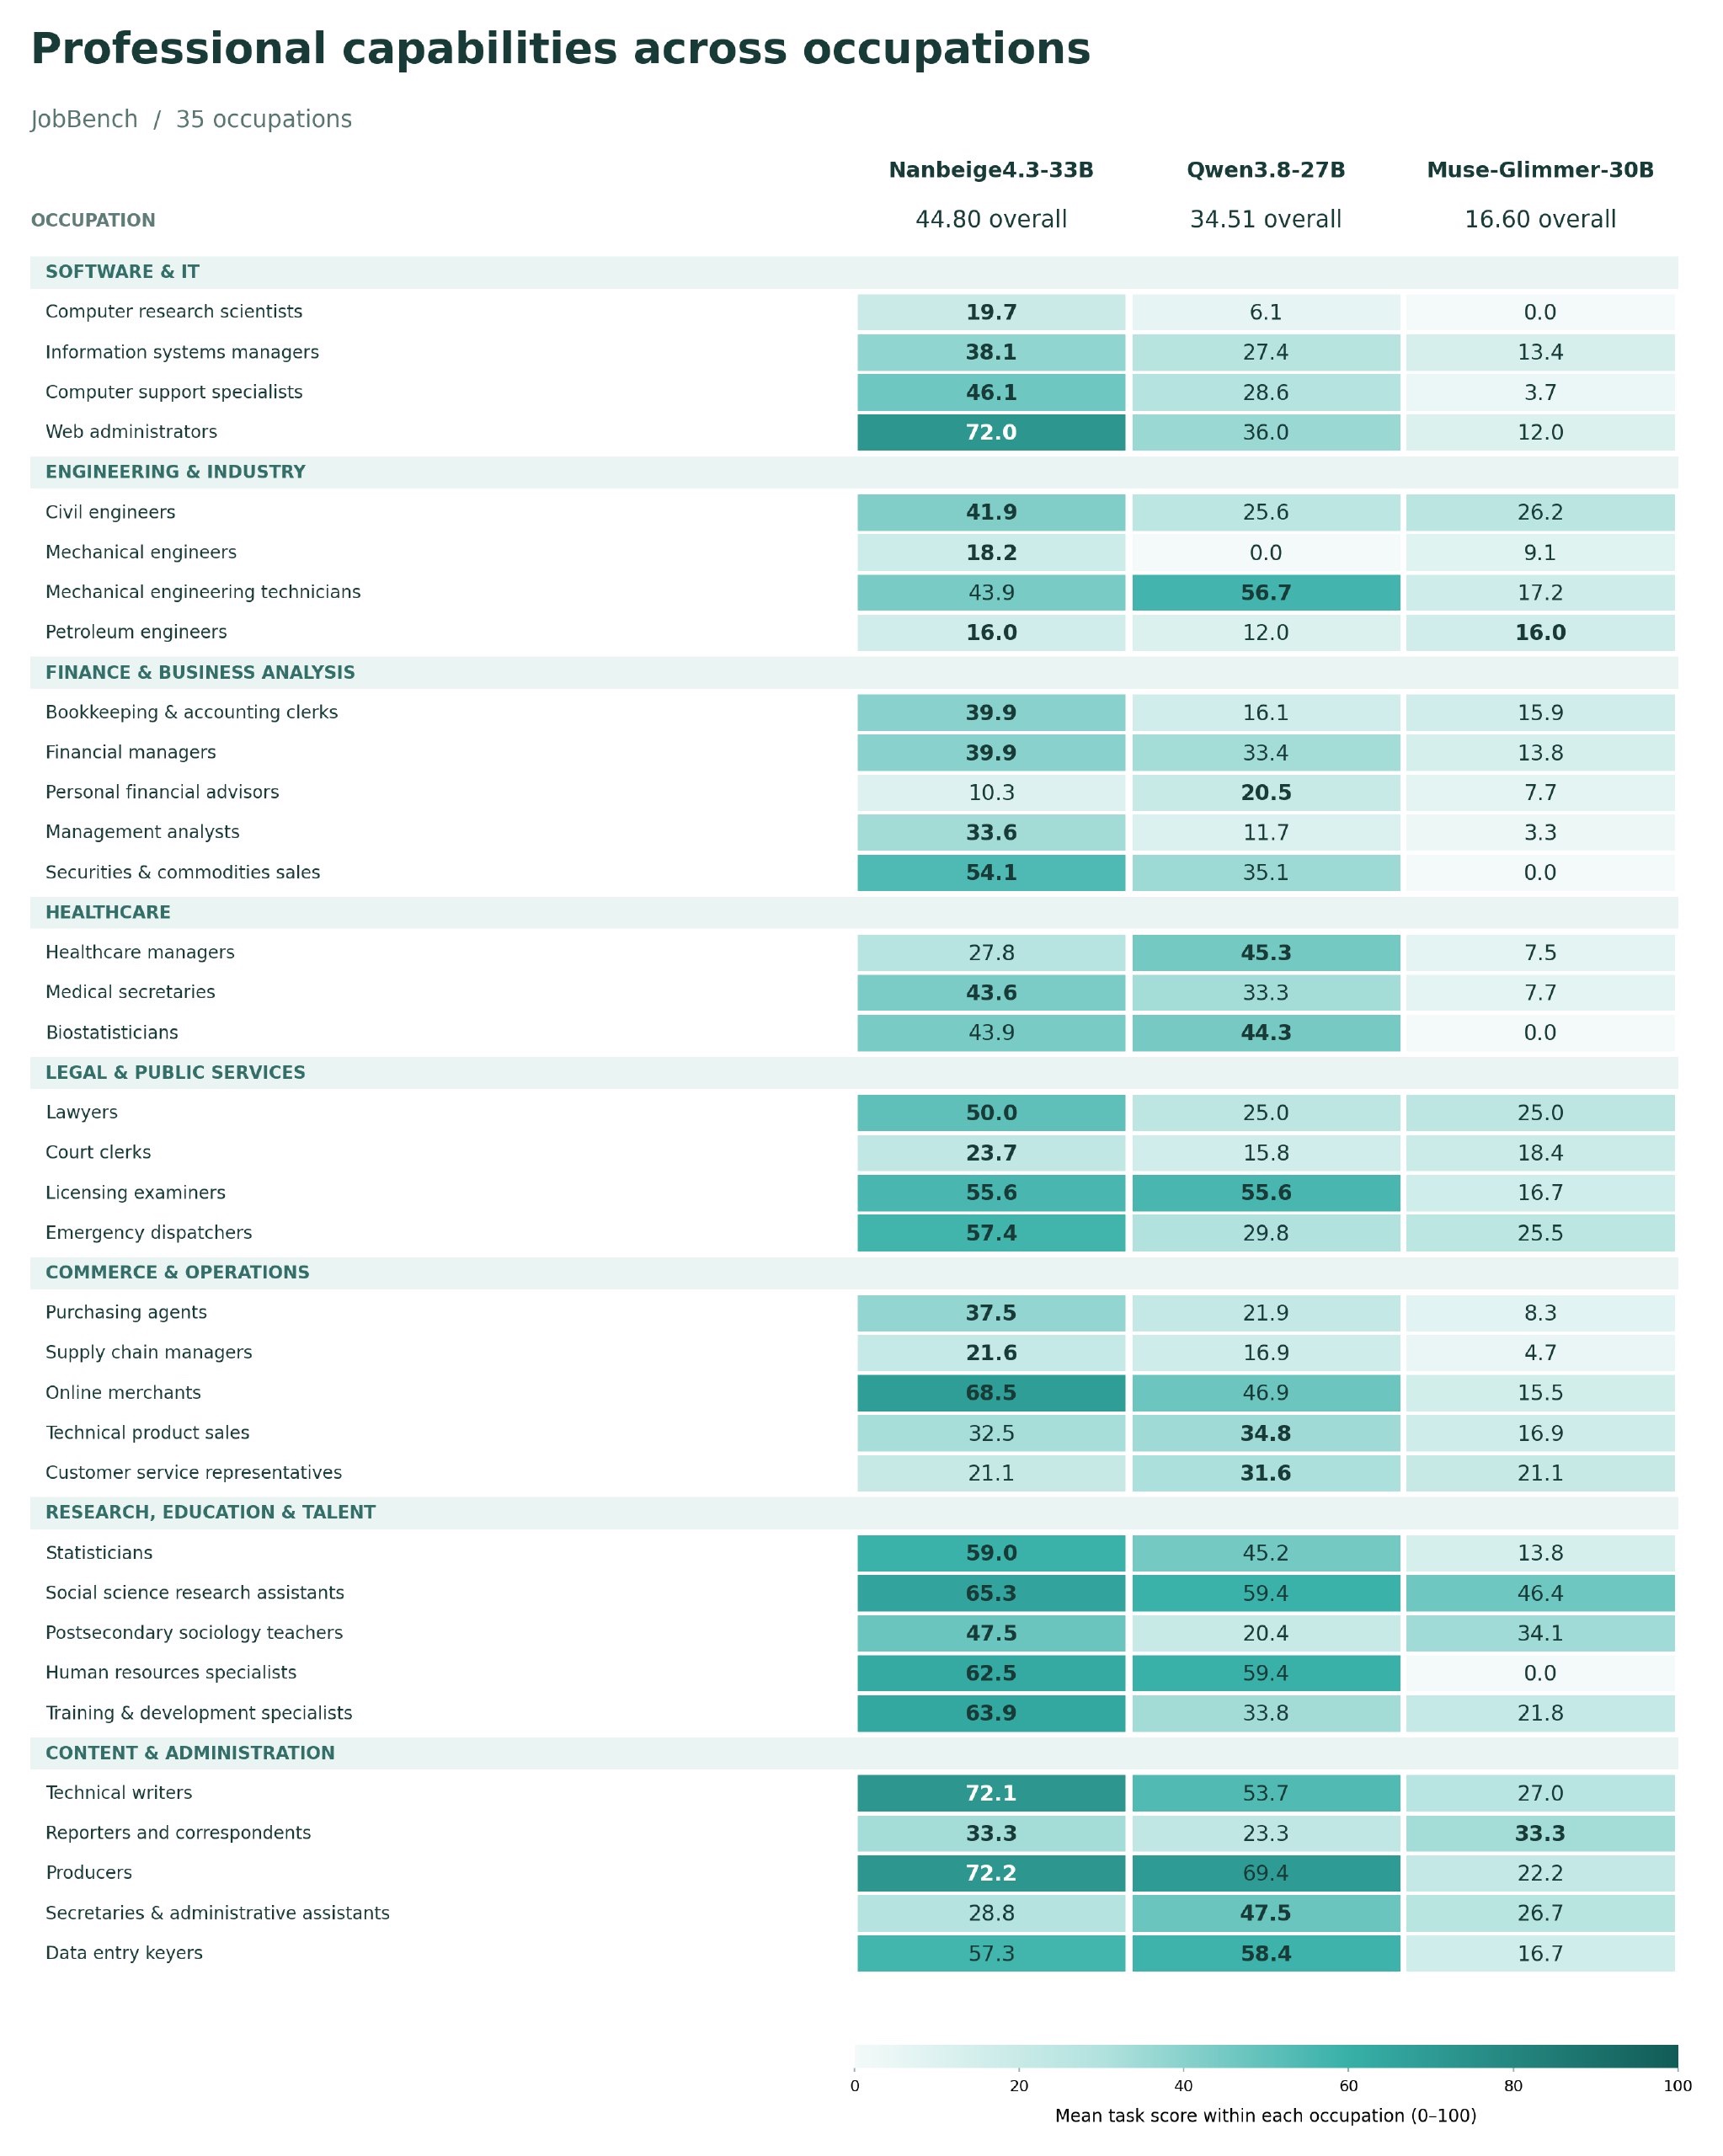
Nanbeige, the model lab inside BOSS Zhipin, just open-sourced Nanbeige4.3-33B. A 33B dense model, 512K context, Apache 2.0. It wins 17 of the 20 benchmarks they picked.
The wins aren't close. Terminal-Bench 2.1: 80.9 against Qwen3.8-27B at 73.0. DeepSWE: 65.5 against 42.5. Automation Bench, their office-automation suite: 54.2 against 38.3. A 33B dense model doing that to a 27B is not what the scaling curve from last year predicted.
The three losses: SWE-Bench Pro 60.3 to 61.7, GDPval 84.8 to 86.4, GPQA Diamond 89.5 to Gemma4-31B's 91.3. Two of those are near-misses, and GPQA is the one benchmark here that rewards memorized science trivia more than agentic work, so I'd weight it least.