Grok-bot’s box is one of those things that’s barely worth using, but you still don’t throw it away.It’s an 8-core / 16+128G machine, except it isn’t a real Linux server. It’s just a Docker container. No systemd, no daemons, no auto-restart, no boot-on-start, no public IP.
Every so often a grok-bot update spins up a new instance. Stuff in home survives the update. Running processes don’t. You have to get the bot to bring them back up.
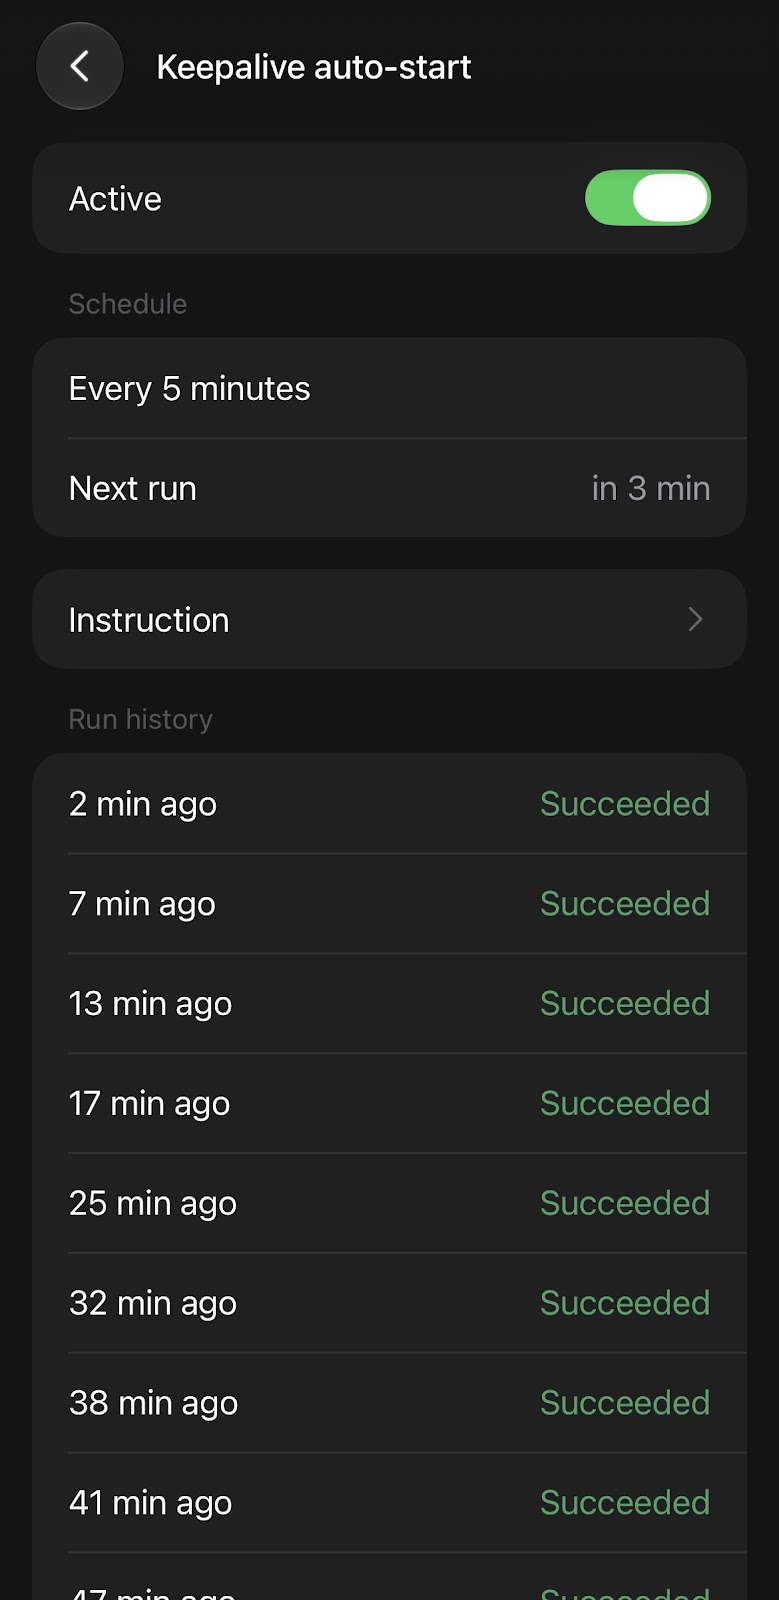
So if you actually want to use the machine, grok-bot has to keep it alive. My setup: install Hermes, write a watchdog that relaunches Hermes every minute, then tell grok-bot to kick the watchdog every five minutes.
New instance lands → grok-bot starts the script → script starts Hermes → Hermes starts everything else.
It’s holding for now. Two problems though.
One: grok-bot only pokes it every five minutes. Weekly quota hit 60% in two days. Quota just reset today, otherwise the base plan isn’t enough.
Two: the box is flaky. Anything a bit heavy and it dies. Grok-bot goes silent too. Only fix is restore the machine in settings.